
The CFD enthusiast has become a ML researcher. Senior Researcher at LG CNS AI Lab. Opinions are solely my own and do not express the opinions of my employer.
Seoul
Joined November 2010
- Tweets1.4K
- Following762
- Followers119
- Likes4.2K





Jongsu Liam Kim retweeted

wow insane, they are literally livestreaming the RL training run of Mimo V2.6 Pro (1T, 42B active) and Flash (309B, 15B active) with per batch data/harness composition and a ton of internal training metrics
mimo.xiaomi.com/rl/


Nearly half a year of silence. We spent it studying one problem: how far RL can scale.
MiMo-V2.6 is in the middle of its RL run right now. Three things we scaled: compute (~2B tokens per step, 1568 prompts × 16 rollouts, fully async), environments and harnesses (multi-task agentic RL, mixed across multiple harnesses in one run), and grader compute (agentic in-group credit assignment, with test-case and rubric-based rewards). We'll open-source the details piece by piece over the coming weeks.
Streaming the run: mimo.xiaomi.com/rl/
Jongsu Liam Kim retweeted

drama summary for those confused:
- Aug 15th: Tristan Buckmaster & Levent Alpöge make progress on a few important math problems
- they do NOT have a proof for the $1,000,000 Millenium Prize problem. BUT, they do claim to have a proof for a similar (non-Millenium) Navier Stokes problem that could help lead the way there
- Levent works at Anthropic, but this research was independent of his work there, with a mix of GPT and Claude models. Tristan is not related to Anthropic.
- Early Sep: Rumor spreads to OpenAI that Anthropic has solved a major problem. Tristan emails OpenAI to clarify. without revealing the problem they solved or how they did it.
- After hearing of the rumor, OpenAI started researching Navier Stokes with a new internal model.
- Sep 6th: OpenAI's Sebastien Bubeck tells Tristan that they solved the $1,000,000 Millenium Prize Navier Stokes problem. The approach is very similar to Tristan & Levent's approach to the non-Millenium problem.
- Tristan is suspicious of the timing, as only few others were trying this approach. OpenAI says the model didn't access his user data directly, but leaves unanswered whether Tristan's chat conversations were part of the training.
- OpenAI says they would partially credit Tristan for the $1,000,000 discovery (even though Tristan did not solve the $1,000,000 problem) — but only if they remove Levent as an author, as he works for Anthropic.
- Sep 8th: Tristan refuses to remove Levent, and rushes to publish their results independently.
Currently unclear is whether Anthropic had a separate solution for the $1,000,000 problem, or whether the rumor was about Tristan & Levent's independent research.


Jongsu Liam Kim retweeted

GPT 6 Astra is estimated to have ~1.2T Active Parameters and ~10T Total Parameters.
Reports indicate pre-training for GPT-5.5 (codename Spud) concluded on March 24 at the Abilene campus. Astra's pretraining run (Doug) would have taken over that cluster after that, OpenAI confirmed the math results were achieved by an internal version of Astra on August 1. So pretraining ran roughly late March to late June/early July, that is ~90–110 days.
Abilene's operational figure was approximately 150,000 to 200,000 GPUs as of May 2026, with inference sharing the site. So ">100k" for the run means 100 to 150k GPUs.
Around August 25, information circulated that OpenAI had completed a base model called "Bel" with over 10 trillion parameters, successor to Doug. Bel finished ~Aug 25 but Astra was already doing math Aug 1, so Astra is almost certainly on Doug, and Bel is a later model.
Compute for pretraining alone: 120k GPUs × 2.25e15 (BF16) × 0.30 MFU × 100 days ≈ 7e26 FLOP. Range 4e26 to 1.5e27 depending on FP8 and MFU.
Whole 100 days on pretraining, which is now plausible since RL ran afterward (the big RL run was restarted in August per Vellum/CNBC reporting).
Now the data wall does real work. Solve N_active = C / (6·D):
Tokens D N_active at 7e26
40T 2.9T
60T 1.9T
80T 1.5T
100T 1.2T
Realistic 2026 corpora with synthetic data and repeats top out ~60–100T, so active params land at 1 to 2T. Even at the conservative 4e26 end with 80T tokens, you get ~830B active.
Astra bills $50/M output at 62 t/s vs Sol's $30/M, a 1.7x price step, consistent with roughly 1.5 to 2.5x active params over its predecessor, not a 10x jump. Rough, but it argues against the >2T end.
Active parameters: ~1T–1.5T (central ~1.2T)
Total parameters: ~10–14T assuming 8–12x MoE sparsity (GPT-4's leaked ratio was ~6.5x; modern large MoE runs 10x+)

GPT-6 Astra, trained on ~100K+ NVIDIA Grace Blackwell NVLink72. From ChatGPT to o1 to Astra in 4 years.
AGI has arrived. Congratulations @OpenAI team.
400K GPUs coming online next.
Jongsu Liam Kim retweeted

o1, o3, early gpt-5 instant/thinking models, all of it was built on the same gpt-4o base model, confirmed by greg brockman
so from gpt-4o in April 2024, all the way through december 2025, openai didn't pretrain a single model. just post training, RL, and reasoning improvements squeezed out of the same foundation.
the first new real pretrain atleast confirmed by openai was gpt-5.5 (spud) in April 2026. gpt-5.6 is built on the same base.
which makes astra the next major pretrain after spud. and that's exactly why it's a big deal.
Jongsu Liam Kim retweeted

최근 읽은 기술 철학에 관한 글 중에서 가장 정교하고 치밀한 글인 것 같다. 조금 길고 읽기 난해했지만, 그래도 읽기를 잘 했다. 소프트웨어 업계에 종사하는 모든 사람들에게 일독을 권한다.
deadsimpletech.com/blog/no-s…

Jongsu Liam Kim retweeted

Behavioral cloning mystery
seohong.me/blog/behavioral-c…
I wrote a new blog post about "mysteries" in behavioral cloning that appear with real-world robot data (e.g., overfitting is "good"). I also tried to demystify them and shared my thoughts!

Jongsu Liam Kim retweeted

Regular Rubin is 2 dies - 288 GB HBM4
Rubin ultra was supposed to be 4 dies, but rumor is it got despecced to 2+2 config with 2 packages of 2 dies connected over PCB. If the rumor is 192 GB it most likely means per package but still puts the total for the unit @ 2 x 192 = 384 GB.
So still probably a big perf increase over normal Rubin but curious as to why they would make the decision.

HBM MASSIVE CONTENT DOWNGRADE ALERT🚨🚨: Nvidia Rubin Ultra will ship with 192GB of HBM4 8-hi. Not only is this a huge downgrade from the original Rubin Ultra which was previewed with 1TB of HBM, but it is even lower than regular Rubin which has 288GB. How did HBM content for Rubin Ultra get cut to 1/5th of the original? The number of cubes got cut to 8 when 4 die Rubin Ultra was scrapped. Then the stack height got reduce to 8-hi instead of 16-hi. Last it is cut to HBM4 which uses 24Gb dies instead of 32Gb dies with HBM4E, although an 8-hi HBM4E upgrade could com later. What was Nvidia's reasoning behind this? (1/2)🧵


Jongsu Liam Kim retweeted

sharing a new long-form blog post: ai chip architectures
it covers the leading chip architectures (nvidia, amd, tpus, trainium, cerebras, groq) across architecture, scaling (scale-up and scale-out), and software stacks.
it helps build an intuition for the architectures and their trade-offs.
jacobpeake.com/ai-chip-archi…


Jongsu Liam Kim retweeted

Thoughts About Scaling Law
Scaling, but not only of parameters. Every model release now ends with the same question: how many parameters? It isn't a question that can be answered on its own. Parameter count is only meaningful alongside three others — how much data you have, where you intend to spend your compute, and who will run the model, under what conditions.
The field learned this the hard way. Kaplan et al. (2020) fit an exponent that told everyone to grow parameters faster than data — roughly 2.7:1 — and the industry complied: GPT-3, Gopher, MT-NLG. Hoffmann et al. (2022) redid the experiment across four hundred models and found the compute-optimal split is closer to 20 tokens per parameter, and that with sufficient compute the two should grow at the same rate rather than drifting apart. The error in the earlier fit compounded with every order of magnitude of compute, which is why the largest models of that generation were the most misallocated. The trillion-parameter round was, in retrospect, a detour the whole field took together and then reversed.
Chinchilla wasn't the end either. It optimized training compute for models that would be trained once and evaluated. Today a model is called billions of times a day and inference dominates lifetime cost. Put inference into the objective and the optimum moves toward smaller models trained far longer — deliberate over-training, which is what Llama-2-7B and Gemma-2-9B were doing at roughly 290 and 889 tokens per parameter.
Sparsity moved the target again. In a MoE model two quantities have to be kept apart: total parameters govern roughly how much the model can hold — knowledge, facts, the long tail — while activated parameters and effective depth govern roughly how far it can think, how many steps of a causal chain it can carry before it comes apart. A dense 20:1 ratio does not transfer. And the ratio isn't a single number at all: Roberts et al. (2025) find the optimal tokens-per-parameter is task-dependent, with memorization favoring more parameters and reasoning favoring more data. Follow-up work on MoE observes that at fixed TPP, pushing total parameters higher actually degrades reasoning, while activating more experts reliably helps it.
This matters for what we are building toward. Finding a vulnerability is not a retrieval problem. It doesn't come from having memorized more CVEs; it comes from carrying a twenty-step chain of inference to the end without losing the thread. That capability does not live in total parameter count.
Which brings us to this release. Total parameters appear to matter up to a threshold — enough to hold the world — after which additional capability comes from scaling elsewhere: effective depth per forward pass, and above all post-training. GLM-5.3 is our controlled experiment on that claim. Same base, same architecture, same total and activated parameters as GLM-5.2. One month of scaling long-horizon environments and RL. The gains are not marginal. Well, scaling has more than one dial. We turned the post-training one this time because it had the most slack left in it — not because the others are finished. Base model size, pretraining data, compute spent per forward pass: all of them are still on the table, and we will come back to each. What this experiment taught us is that the dials do not have to be turned together, and that the one worth turning next is rarely the one that was worth turning last. We are not done scaling. Next time, maybe mid-training, pre-training, and even more.

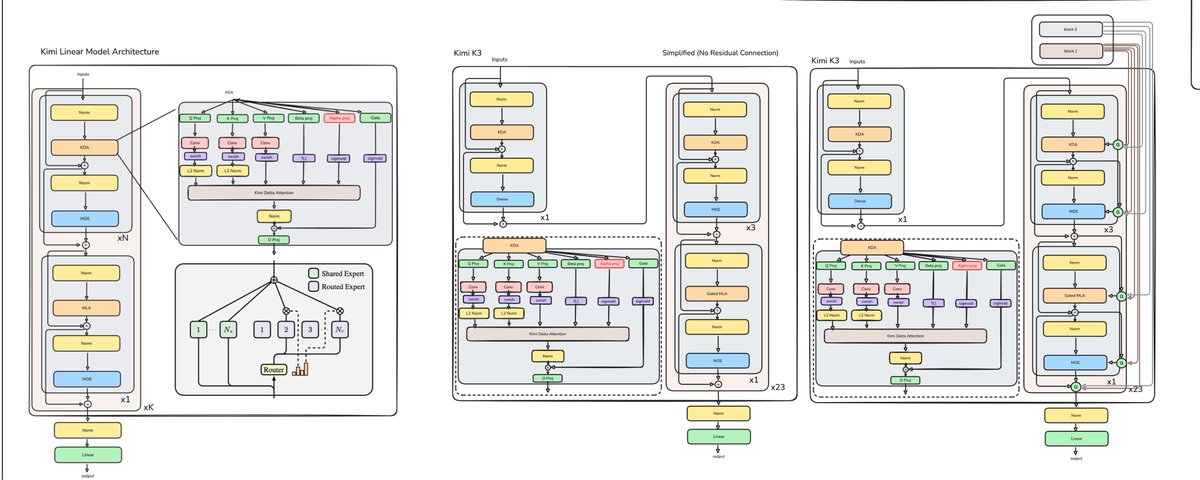
Prof. Mark Schmidt’s ICML tutorial today was incredible: cs.ubc.ca/~schmidtm/Document…
He tied scattered concepts into a simple framework, connecting my fragmented knowledge. Great humor, too. Absolute masterpiece.
Jongsu Liam Kim retweeted
every infra piece you need to know to do RL on GLM-5
primeintellect.ai/blog/rl-at…




Jongsu Liam Kim retweeted

Stanford @frontiersystems, Week 1 (Full Lecture)
AI Scaling, Bottlenecks, and Why Compute Isn't a Commodity Yet
00:00 Compute Coachella
00:29 Simple Life Heuristic
01:08 Uncertainty Creates Opportunity
01:42 Four Bottlenecks Framework
01:51 Empirical Proof Matters
02:05 Cloud Costs Are Shifting
02:15 Verifiable vs Fuzzy Progress
02:48 Scaling Predictability Explained
03:43 CapEx Explosion in Big Tech
04:06 Chips Aren’t Commodities
04:45 Compute Scarcity Conclusion