Skunzu retweeted
THIS IS A REAL F*CKING GOLDMINE
Anthropic just shared one of the best tricks for Claude Code
The idea: run Sonnet 5.5, Haiku 5.5 and Opus 5.5 together, each one doing only the job it's best at
Better output and way fewer tokens: every task lands on the right model
You just start Claude Code like this:
CLAUDE_CODE_SUBAGENT_MODEL=haiku claude --model sonnet
here's how it splits:
→ Sonnet 5.5 runs the main session, writes the code and applies the fixes
→ Haiku 5.5 swarms the repo in parallel: search, grep, docs and test audits, each in its own context
→ Opus 5.5 sits in its own architect subagent for the big decisions and signs off on the diff
→ you stop burning Opus on routine work and stop flooding the main session with raw logs
Opus only steps in at three moments:
→ before a plan locks
→ when the same error hits twice
→ before calling it done (signing off on the git diff)
Sonnet builds, Haiku swarms, Opus reviews
JEV engineering is the same move one layer down: the forks that need no thinker (which agent, which tool, retry or stop) go to JEV in milliseconds, and the big models only see the ones that split
the full tree
> Sonnet 5.5 runs the main session and writes the code
> search maps the repo on Haiku 5.5 (read-only)
> grep finds call sites on Haiku 5.5 (own context, only the summary comes back)
> audit checks diffs on Haiku 5.5 in a temporary worktree (isolation: worktree)
> architect runs on Opus 5.5 (its model: opus beats the haiku default), reviews the final diff
> JEV routes micro-forks in milliseconds
paste the tree and this prompt into Claude Code ↓
"Reconfigure my Claude Code setup around this tree:
1. Run the main session on Sonnet 5.5 and set CLAUDE_CODE_SUBAGENT_MODEL=haiku
2. Create four subagents in .claude/agents/: search (maps the repo), grep (finds call sites) and audit (checks diffs) on Haiku 5.5, plus architect with model: opus
3. Set isolation: worktree on audit so it never touches my working branch
4. Add one rule to CLAUDE.md: send every repo search and test run to a Haiku 5.5 subagent, and call architect before a plan locks, after the same error twice and before done
5. Route fast deterministic forks (tool choice, path selection, retries) through JEV
Show me every change as a diff first. No edits until I say go"
↳ code.claude.com/docs/en/sub-…
save it, you'll need it
Skunzu retweeted
THIS IS SO F*CKING UNDERRATED
Anthropic put one of the best Claude Code tricks in its own docs, and almost nobody uses it.
The idea: stop stuffing procedures into CLAUDE.md. Move every step-by-step job into a skill.
CLAUDE.md loads into every single session. A skill's body only loads when it's actually used, so long checklists cost almost nothing until the moment you need them.
You start with one folder:
mkdir -p .claude/skills/release-check
here's the split:
→ CLAUDE.md keeps facts only: stack, commands, rules
→ every procedure becomes .claude/skills//SKILL.md
→ only its one-line description sits in context until the job comes up
→ model: haiku and context: fork run the heavy ones in their own subagent
The skill only shows up at three moments:
→ when your request matches its description
→ when you type /release-check yourself
→ when you touch files that match its paths
CLAUDE.md remembers. Skills load. Haiku does the chores.
JEV engineering is the same move one layer down: the forks that need no thinker (which skill, which file, retry or stop) go to JEV in milliseconds, and the big models only see the ones that split
the full tree
> CLAUDE.md holds facts only, short
> .claude/skills/release-check/SKILL.md holds the procedure
> description: one line that says when to use it
> !`git diff HEAD` injects the live diff before Claude reads it
> model: haiku + context: fork runs it outside the main session
> Opus 5.5 reads only the result
> JEV routes micro-forks in milliseconds
paste the tree and this prompt into Claude Code ↓
"Audit my CLAUDE.md around this tree:
1. Split it into facts (keep) and procedures (move out).
2. Turn each procedure into .claude/skills//SKILL.md with a one-line description of when to use it.
3. For read-only chores, add model: haiku and context: fork.
4. Add paths: to skills that only matter for certain folders.
Show me every change as a diff first. No edits until I say go."
↳ code.claude.com/docs/en/skil…
your CLAUDE.md should get shorter every week.
Skunzu retweeted
THIS SHOULD BE F*CKING ILLEGAL
9 repos, 465K stars, and Opus 5.5 finally stops burning your money on work it never needed to do.
if Opus 5.5 is eating your budget and you have no idea where it goes, copy this:
claude-code-router: sits in front of Claude Code and sends every request to the cheapest model that can handle it. Haiku does the grep, Opus only gets the hard part. 37k stars
github.com/musistudio/claude…
rtk: shrinks test, build and git output before the model ever sees it. one binary, up to 90% less bash noise in your context. 83k stars
github.com/rtk-ai/rtk
claude-mem: remembers what happened in your past sessions and feeds back only the part that matters, so you stop paying to re-explain your project every morning. 100k stars
github.com/thedotmack/claude…
context-mode: huge tool output goes into a local database instead of your context window, and Claude pulls out only the lines it needs. 29k stars
github.com/mksglu/context-mo…
caveman: makes Claude answer in short telegraphic sentences. the code stays exactly the same, and output is the expensive side on Opus 5.5 ($20 per million). 112k stars
github.com/JuliusBrussee/cav…
ccusage: reads your local Claude Code logs and shows which sessions and which days actually burned the tokens. 19k stars
github.com/ryoppippi/ccusage
serena: gives Claude symbol-level lookups through a language server, so it reads the one function and not the 2,000 lines around it. 30k stars
github.com/oraios/serena
code-review-graph: maps your repo as a graph and hands Claude only the code connected to the change you're reviewing. 32k stars
github.com/tirth8205/code-re…
jev-ultrafast: a browser agent where Jev picks every click, and a text model only wakes up when something has to be typed. 23k stars
github.com/browser-use/jev-u…
none of them makes Opus smarter. every one stops it from paying for work it never needed to do
run ccusage before and after, so you know what you actually saved
Skunzu retweeted

THIS IS STUPIDLY F*CKING GOLD
10,608 launches in 24h. 7,130 blocked. 56 trade signals. Almost nobody filters launches like this Opus 5.5 reverse-engineer board does.
Stop treating every new launch as an entry. Each one collapses into three odds that sum to 1: +60% first, -30% first, or nothing in 60 minutes. Net EV after costs under +3% means skip.
No gut feel, no FOMO, and every skip shows its math.
You trace any decision back like this:
orb trace RUN-084199 --from-buy
the six agents:
→ Scout reads 43 events a second
→ Cartographer links wallets into 1,271 groups
→ Judge follows 43 wallets
→ Quant scored 106 setups in 24h
→ Guard blocks 72%
→ Executor keeps 1.7% in play, hard limit 15%
three moments that decide it:
→ $MOGOWL blocked, 45% of buyers share one funder
→ $BENWOOD blocked, snipers still hold 31%
→ $FLUPUP gets through at 0.78, passed quant and guard
One live example on screen: 0.24 to hit +60%, 0.47 to hit -30%. Edge -12.6%, costs 3.9%, net EV -16.4%. Skipped.
↳ board is tagged sample and research mode. no PnL here, just a filter that said no to 7,130 launches in a day
Skunzu retweeted
THIS IS AN ABSOLUTE F*CKING GOLDMINE
Anthropic just dropped one of the best tricks for Claude Code.
The idea: Opus 5.5 writes the whole plan as a script, and a swarm of cheaper agents runs it.
Bigger jobs and way fewer Opus tokens, because the script carries the plan and Opus only sees the final answer.
You just launch Claude Code like this:
claude --model opus --effort ultracode
here's the split:
→ Opus 5.5 turns your task into a workflow script
→ Haiku 5.5 agents scan every file in parallel
→ Sonnet 5.5 agents patch each fix in their own isolated copy
→ you stop burning Opus context on a hundred agent transcripts
Opus only shows up at three moments:
→ writing the workflow before the run
→ reading the verified results after it
→ signing off before anything ships
Opus plans. Haiku scans. Sonnet ships.
JEV engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to JEV in milliseconds, and the big models only see the ones that split
the full tree
> Opus 5.5 runs the main session and writes the workflow
> scan audits every file on Haiku 5.5
> edit patches each fix on Sonnet 5.5 in an isolated copy
> verify double-checks every finding on Sonnet 5.5
> Opus 5.5 reads only what survived verification
> JEV routes micro-forks in milliseconds
paste the tree and this prompt into Claude Code ↓
"Rebuild my Claude Code setup around this tree:
1. Run the main session on Opus 5.5 with ultracode on.
2. In every workflow, run read-only scan stages on Haiku 5.5 and edit stages on Sonnet 5.5, each edit in its own isolated copy.
3. Add one rule to CLAUDE.md: every finding gets an independent verifier agent before it's reported, and fix loops stop after two rounds with no progress.
4. Route fast deterministic forks (tool choice, path selection, retries) through JEV.
Show me every change as a diff first. No edits until I say go."
↳ code.claude.com/docs/en/work…
you'll use this on every big task from now on.

THIS IS AN ABSOLUTE F*CKING GOLDMINE
Anthropic just dropped one of the best tricks for Claude Code.
The idea: Opus 5.5 writes the whole plan as a script, and a swarm of cheaper agents runs it.
Bigger jobs and way fewer Opus tokens, because the script carries the plan and Opus only sees the final answer.
You just launch Claude Code like this:
claude --model opus --effort ultracode
here's the split:
→ Opus 5.5 turns your task into a workflow script
→ Haiku 5.5 agents scan every file in parallel
→ Sonnet 5.5 agents patch each fix in their own isolated copy
→ you stop burning Opus context on a hundred agent transcripts
Opus only shows up at three moments:
→ writing the workflow before the run
→ reading the verified results after it
→ signing off before anything ships
Opus plans. Haiku scans. Sonnet ships.
JEV engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to JEV in milliseconds, and the big models only see the ones that split
the full tree
> Opus 5.5 runs the main session and writes the workflow
> scan audits every file on Haiku 5.5
> edit patches each fix on Sonnet 5.5 in an isolated copy
> verify double-checks every finding on Sonnet 5.5
> Opus 5.5 reads only what survived verification
> JEV routes micro-forks in milliseconds
paste the tree and this prompt into Claude Code ↓
"Rebuild my Claude Code setup around this tree:
1. Run the main session on Opus 5.5 with ultracode on.
2. In every workflow, run read-only scan stages on Haiku 5.5 and edit stages on Sonnet 5.5, each edit in its own isolated copy.
3. Add one rule to CLAUDE.md: every finding gets an independent verifier agent before it's reported, and fix loops stop after two rounds with no progress.
4. Route fast deterministic forks (tool choice, path selection, retries) through JEV.
Show me every change as a diff first. No edits until I say go."
↳ code.claude.com/docs/en/work…
you'll use this on every big task from now on.
Skunzu retweeted
THIS IS STUPIDLY F*CKING GOLD
10,589 launches in 24h. 7,123 blocked. 52 trade signals. This Jev board has a trick almost nobody uses.
The idea: stop letting one model decide if a launch deserves an entry. Six agents score every launch, and the executor only fires when net EV after costs clears +3%. In the first 49 runs that's 18 entries, 27 skips, 4 blocks.
No gut calls, no FOMO entries, and every skip leaves a reason in the log.
You trace any decision back like this:
orb trace RUN-084199 --from-buy
here's the split:
→ Scout reads the feed at 41 events a second
→ Cartographer links wallets into 1,241 groups
→ Judge follows 32 wallets
→ Quant scores 87 setups a day
→ Guard blocks 72% of what reaches it
→ Executor keeps 1.8% in play against a 15% limit
You only look at three moments:
→ Guard blocks a launch because 45% of its buyers share one funder
→ Quant sees edge -10.6%, costs 3.9%, net EV -14.4% and skips
→ a launch passes Quant and Guard and goes to the executor
↳ animated concept with sample numbers, not a live P&L. the +3% after costs rule is the part worth copying
Skunzu retweeted
THIS IS STUPIDLY F*CKING GOOD
Anthropic's own Claude Code playbook has a trick almost nobody uses.
The idea: stop running one giant session on a 300-file job. Opus 5.5 writes the plan once, then Claude Code runs headless, one fresh Haiku 5.5 session per file, 8 at a time.
No context rot, no 4-hour transcript, and you see the exact cost of every file.
You just run Claude Code like this:
claude -p "$task" --model haiku --max-turns 8 --output-format json
here's the split:
→ Opus 5.5 reads the repo once and writes tasks.txt, one line per file
→ Haiku 5.5 does one file per session with a clean context
→ Sonnet 5 only touches the files that come back FAIL
→ you read a cost column instead of babysitting a chat
You only look at three moments:
→ before the loop starts (read tasks.txt)
→ when the FAIL rate goes over 10%
→ before you merge
Opus plans. Haiku grinds. Sonnet cleans up.
JEV engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to JEV in milliseconds, and the big models only see the ones that split
the full tree
> Opus 5.5 writes tasks.txt: every file + the one rule to apply
> xargs -P 8 runs 8 headless Haiku 5.5 sessions at once
> each session: fresh context, max 8 turns, only Edit and git commit allowed
> each one must answer OK or FAIL, nothing else
> --output-format json gives you the result and total_cost_usd per file
> FAIL lines go to Sonnet 5 with the error attached
> JEV routes micro-forks in milliseconds
paste the tree and this prompt into Claude Code ↓
"Set up a fan-out run for this repo:
1. Use Opus 5.5 to write tasks.txt: one line per file that needs [your change], plus the exact rule to apply.
2. Write run.sh: for each line, call claude -p with --model haiku --max-turns 8 --allowedTools "Edit" "Bash(git commit:*)" --output-format json, 8 in parallel with xargs -P 8. The prompt must end with: reply OK if done, FAIL if not.
3. Log file, OK/FAIL and total_cost_usd to results.csv.
4. Send every FAIL back through Sonnet 5 with its error, then stop.
Show me tasks.txt and run.sh first. Don't run anything until I say go."
↳ code.claude.com/docs/en/head…
this is how you clear a week of refactors in one afternoon.


Skunzu retweeted

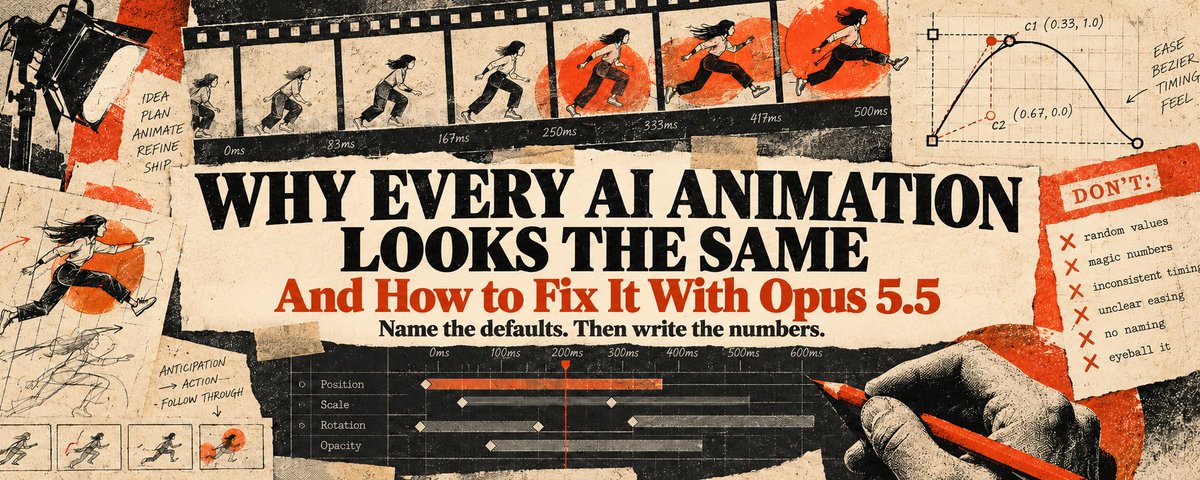
AI can generate an entire animation in minutes. So why do most of them still look exactly the same?
The same 300ms transitions. The same bouncing elements. The same fade-ins, floating objects, and perfectly predictable camera movements.
Even when you ask for something cinematic or premium, the model falls back on patterns it has seen thousands of times.
I've been experimenting with a different approach using Opus 5.5.
Instead of describing how the animation should feel, I define exactly how it should behave.
> BAN LIST: remove generic motion patterns before generation
> TIMING: specify durations, delays, distances, and easing curves
> TIMELINE: give every movement an exact start time
> FRAMES: freeze the animation and inspect what actually happens
> REVIEW: measure the differences between the result and the brief
> REFINE: change the numbers without rebuilding everything
The animation in this video follows that approach.
The interesting part isn't how many objects are moving. It's how the camera, depth, timing, and transitions work together.
Small changes to the numbers can completely change how a scene feels.
the full six-step workflow in the article below, including how to get Opus 5.5 to review and improve its own motion design👇

THIS IS STUPIDLY F*CKING GOOD
Anthropic's own Claude Code playbook has a trick almost nobody uses.
The idea: stop running one giant session on a 300-file job. Opus 5.5 writes the plan once, then Claude Code runs headless, one fresh Haiku 5.5 session per file, 8 at a time.
No context rot, no 4-hour transcript, and you see the exact cost of every file.
You just run Claude Code like this:
claude -p "$task" --model haiku --max-turns 8 --output-format json
here's the split:
→ Opus 5.5 reads the repo once and writes tasks.txt, one line per file
→ Haiku 5.5 does one file per session with a clean context
→ Sonnet 5 only touches the files that come back FAIL
→ you read a cost column instead of babysitting a chat
You only look at three moments:
→ before the loop starts (read tasks.txt)
→ when the FAIL rate goes over 10%
→ before you merge
Opus plans. Haiku grinds. Sonnet cleans up.
JEV engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to JEV in milliseconds, and the big models only see the ones that split
the full tree
> Opus 5.5 writes tasks.txt: every file + the one rule to apply
> xargs -P 8 runs 8 headless Haiku 5.5 sessions at once
> each session: fresh context, max 8 turns, only Edit and git commit allowed
> each one must answer OK or FAIL, nothing else
> --output-format json gives you the result and total_cost_usd per file
> FAIL lines go to Sonnet 5 with the error attached
> JEV routes micro-forks in milliseconds
paste the tree and this prompt into Claude Code ↓
"Set up a fan-out run for this repo:
1. Use Opus 5.5 to write tasks.txt: one line per file that needs [your change], plus the exact rule to apply.
2. Write run.sh: for each line, call claude -p with --model haiku --max-turns 8 --allowedTools "Edit" "Bash(git commit:*)" --output-format json, 8 in parallel with xargs -P 8. The prompt must end with: reply OK if done, FAIL if not.
3. Log file, OK/FAIL and total_cost_usd to results.csv.
4. Send every FAIL back through Sonnet 5 with its error, then stop.
Show me tasks.txt and run.sh first. Don't run anything until I say go."
↳ code.claude.com/docs/en/head…
this is how you clear a week of refactors in one afternoon.
Skunzu retweeted
holy sh*t. 10,607 pump.fun launches in 24h, 7,130 blocked, 56 trade signals. Stop letting one agent pick the entry
the trick is the rule in the header. every launch ends one of three ways: +60% first, -30% first, or neither in 60 min
orb trace RUN-084199 --from-buy
the scout reads 44 events per second
the cartographer links wallets into 1,271 groups
the guard blocks 73% of what reaches it
the bot only needs a human at three critical moments:
→ at the guard: $BONBIT gets blocked because 45% of its buyers share one funder. who decided 45% is the line?
→ at the quant: net EV -14.6% after 3.9% costs, so it skips. is +3% after costs the right bar?
→ at the label: 1,345 outcomes measured today feed a model still marked "in training". when is the sample big enough?
seven signals. three outcomes. one decision record.
This is Jev engineering one layer down. Of the last 70 launches it measured, 34 hit +60% first, 23 hit -30% first, 13 did neither. The decision stack ends at 6 entries, 68 skips and 14 blocks, so almost all the work is saying no
label first, block second, enter last
- the full bot setup
> 6 agents: scout, cartographer, judge, quant, guard, executor
> 7 signals: launch rate, curve inflow, followed flow, bundled share, creator risk, graduation rate, market phase
> 3 outcomes per launch: +60% first, -30% first, neither in 60 min
> skip rule: EV below +3% after costs
> executor cap: 1.8% in play, 15% limit
paste this prompt into Claude Code below:
"Build a research-mode decision layer for new pump.fun launches in my project. No real trades:
1. Label every launch with one outcome: +60% first, -30% first, or neither in 60 min
2. Split the work into six agents:
> scout, cartographer, judge, quant, guard, executor
> each one writes a line to a shared decision record
3. Block a launch when too many buyers share one funder, and log that share
4. Skip anything with expected value below +3% after costs and fees
5. Paper executor only, with a hard cap on how much is in play
Show the plan and every file diff first. Do not apply edits until confirmed"
↳ the dashboard is a concept render in research mode with sample numbers, not a live account


Skunzu retweeted
Claude Opus 5.5 threw the same paint balloon at a wall on all five effort levels. Low cost $1.42. Max cost $33.22.
One prompt, one run each, API prices. Max worked over 2 hours, low finished in 43 minutes.
Cover the labels and pick max.
Most people pay 23x for a difference they'd miss with the labels off.


Skunzu retweeted

REA is the most dangerous thing on the internet right now...
And 99% of people have no idea how to use it.
You pay every month for apps whose features are already sitting on your computer.
Send this single prompt to Opus 5.5 and reverse-engineer any paid closed-source app
Then save the article below on how to become REA engineer👇