

Co-founder @anyshiftio (ex @driftctl → @snyksec). Wrote the IaC Cookbook. Infrastructure, LLMs, ancient philosophy.
Paris, France
Joined January 2009
- Tweets2K
- Following1.7K
- Followers566
- Likes3.7K





these 'composer predictions' in codex are diabolical, they are sharper than my sharpest question that took 5' to formulate inelegantly
54
my Dot is making short work of yet another French tax audit. Dot isn’t available in the EU, but tax audits are. no waitlist. no usage limits.
67
Stephane Jourdan retweeted

"When you peel off the layers of proprietary YAML and jargon, CI today boils down to running shell scripts on a server, and reading the logs. With such a primitive execution and data model, waste is everywhere, and it gets worse as you scale"
dagger.io/blog/dagger-10-bet…
Stephane Jourdan retweeted
After 5 years in v0, it's finally happening.. Dagger 1.0 is in beta and we need your help testing it.
If you've tried Dagger before, a lot has changed... We've been cooking.

Announcing Dagger 1.0 beta.
Replace Jenkins and GitHub Actions with CI that matches the speed and scale of coding agents without wasting compute or tokens.
Featuring: test-native CI, dev shells, local and remote execution, official modules, and more.
dagger.io/blog/dagger-10-bet…
experimenting with OAI Decisions API over hundreds of cases: median scoring latency went from 1204 ms down to 185 ms (and it was 25.7% cheaper). And that's against Luna 6 that's already amazing. Wow
49
very nice experience today with my Dot: i was chatting with it about a research topic when it mentioned a podcast about it, but no access to the transcript. That's when i discovered that my Dot could use open-source models directly: it used fast-whisper (small) to get the data!
1
134

9/11, i was 20, i'd just upgraded to Mandrake Linux 8.1 beta 3. Also, i'm sitting on the floor, watching CNN live on my CRT TV, taking photos with my crappy digital camera for friends on IRC, because news sites were overwhelmed by the traffic. IRC still worked throughout that day


1
91
we gave our infra graph a hostname and a 2h window. it traced cloudflare → aws → ecs, reconstructed the deployment, found the automation behind it, and stopped where the evidence stopped. that’s the graph i want agents investigating!
1
92
SOTA level: the PR is still open in the MCP spec repo 😅
We shipped experimental Skills over MCP in @anyshiftio Graph MCP anyway.
Codex found the remote skill, read its guidance and used it on a blind, authenticated query.
Happy Friday 🔥


What's your oldest unmerged PR? Mine is a 14 years old Vagrant + Route53 fix from 2012. Forgot to request a reviewer back then. lol

63
In 2025, we averaged 47 merged PRs a week.
Today, we’re merging more than 60 a day.
In fact, the last 7 days produced more than the entire first quarter of 2025. And by August, we’ve already delivered 2.2× our total 2025 PR volume.
4
183
something else i like about Luna: it's super token efficient for my use-case. -9.4% less input, -31.9% output. (data from internal evals)

4
267
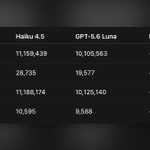
6,336 API calls across 6 LLMs and 352 infrastructure questions.
Haiku, Luna and Terra all reached 100% final-answer accuracy.
Luna delivered it at 21% of Haiku’s observed cost, then explicit prompt reuse cut another 14.2%.
Full benchmark: anyshift.io/blog/llm-routed-…
2
67
We enabled explicit prompt caching for Luna. In a paired 1056-request eval, model cost fell 14%, cache-read share increased from 97.9% to 99.5%, and cache-write share fell 86% with no change in latency, routing accuracy, or reliability. Prod cost: roughly $0.22 per 1000 reqs
1
81
same here. and before ruby: excitation of shipping stuff in the late 90s on my first linux servers. Def same vibe decades apart!

Not since the earliest days of discovering Ruby have I been this excited to jump out of bed and get in front of the keyboard. A million ideas, all bouncing around in my head, just waiting to be prompted. What a time to be alive!
157


