

Pinned Tweet
🚨 VideoAuto-R1 from Meta!🚨
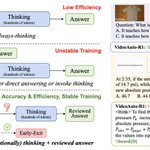
🚀Excited to share our VideoAuto-R1: the first video understanding framework that only reasons when necessary. Our VideoAuto-R1 produces dramatically better results than video reasoning models such as Video-R1 by +10% on both video perception and reasoning benchmarks with significantly improved efficiency, reducing the average response length by∼3x. Our VideoAuto-R1 also outperforms Qwen3-VL-8B by >2.5% on video reasoning benchmarks. For those of you who want to know how we did it, I have 4 words for you: Thinking Once, Answering Twice. Check out the following for more details!
Paper: arxiv.org/abs/2601.05175
Project details and demo: ivul-kaust.github.io/project…
with: @MingchenZhuge @zechunliu @garvinchen2 @liuzhuang1234 @Hu_Hsu @klightlm @ChongZhou7 @erniecyc @_sakshams_ @balakrishnan_vr @raghuraman @BernardSGhanem @vikasc @YoungXiong1 etc

Shuming Liu retweeted

🫱 Introducing 𝐍𝐞𝐮𝐫𝐚𝐥 𝐂𝐨𝐦𝐩𝐮𝐭𝐞𝐫s:
𝐰𝐡𝐚𝐭 𝐢𝐟 𝐀𝐈 𝐝𝐨𝐞𝐬 𝐧𝐨𝐭 𝐣𝐮𝐬𝐭 𝐮𝐬𝐞 𝐜𝐨𝐦𝐩𝐮𝐭𝐞𝐫𝐬 𝐛𝐞𝐭𝐭𝐞𝐫, 𝐛𝐮𝐭 𝐛𝐞𝐠𝐢𝐧𝐬 𝐭𝐨 𝐛𝐞𝐜𝐨𝐦𝐞 𝐭𝐡𝐞 𝐫𝐮𝐧𝐧𝐢𝐧𝐠 𝐜𝐨𝐦𝐩𝐮𝐭𝐞𝐫 𝐢𝐭𝐬𝐞𝐥𝐟?
Beyond today's conventional computers, agents, and world models, Neural Computers (NCs) are new frontiers where computation, memory, and I/O move into a learned runtime state.
We ask: whether parts of runtime can move inward into the learning system itself. This is our first step toward the Completely Neural Computer (CNC): a general-purpose neural computer with stable execution, explicit reprogramming, and durable capability reuse.
Work done with Mingchen Zhuge (@MingchenZhuge), Changsheng Zhao, Haozhe Liu (@HaoZhe65347 ), Zijian Zhou (@ZijianZhou524 ), Shuming Liu (@shuming96 ), Wenyi Wang (@Wenyi_AI_Wang ), Ernie Chang (@erniecyc ), Gael Le Lan, Junjie Fei, Wenxuan Zhang, Zhipeng Cai (@cai_zhipeng ), Zechun Liu (@zechunliu ), Yunyang Xiong (@YoungXiong1 ), Yining Yang, Yuandong Tian (@tydsh ), Yangyang Shi, Vikas Chandra (@vikasc), Juergen Schmidhuber (@SchmidhuberAI)

Shuming Liu retweeted

VideoAuto-R1
Video Auto Reasoning via Thinking Once, Answering Twice
huggingface.co/papers/2601.0…

Shuming Liu retweeted

just spent time to read this paper.
I think the design of output format {a1}{think}{a2} is smart. so that RL can use dual-answer reward to surprise the prediction before and after thinking.
videoauto-r1: arxiv.org/pdf/2601.05175


🚨 VideoAuto-R1 from Meta!🚨
🚀Excited to share our VideoAuto-R1: the first video understanding framework that only reasons when necessary. Our VideoAuto-R1 produces dramatically better results than video reasoning models such as Video-R1 by +10% on both video perception and reasoning benchmarks with significantly improved efficiency, reducing the average response length by∼3x. Our VideoAuto-R1 also outperforms Qwen3-VL-8B by >2.5% on video reasoning benchmarks. For those of you who want to know how we did it, I have 4 words for you: Thinking Once, Answering Twice. Check out the following for more details!
Paper: arxiv.org/abs/2601.05175
Project details and demo:: ivul-kaust.github.io/project…
with: @shumin96 @MingchenZhuge @zechunliu @garvinchen2 @liuzhuang1234 @Hu_Hsu @klightlm @chongzhou7 @erniecyc @_sakshams_ @balakrishnan_vr @raghuraman @BernardSGhanem @vikasc etc

Shuming Liu retweeted

📢Excited to share our new paper "Motion-Aware Concept Alignment for Consistent Video Editing". A training-free framework for video semantic mixing:
🔁Blend new concepts into specific objects
🎯Maintain spatial stability & temporal coherence
📊Outperform basselines
A thread🧵

Shuming Liu retweeted

Excited to share our new paper "Beyond the Last Answer: Your Reasoning Trace Uncovers More than You Think"!
We show that digging into an LLM’s intermediate “subthoughts” and aggregating their answers can significantly boost math reasoning performance.
A thread 🧵

Shuming Liu retweeted

Ever noticed how one scene seamlessly transitions into another in films? That’s a match-cut—a subtle yet powerful cinematic trick.
Our MatchDiffusion, generates two videos from text prompts, designed to form a seamless match-cut—effortlessly and training-free. 🎥✨ 1/n
Shuming Liu retweeted
🔔 new 𝗔𝗴𝗲𝗻𝘁-𝗮𝘀-𝗮-𝗝𝘂𝗱𝗴𝗲 paper:
𝗖𝗮𝗻 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁𝘀 𝗲𝘃𝗮𝗹𝘂𝗮𝘁𝗲 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁𝘀 𝗮𝘀 𝗲𝗳𝗳𝗲𝗰𝘁𝗶𝘃𝗲𝗹𝘆 𝗮𝘀 𝗵𝘂𝗺𝗮𝗻𝘀? 𝗬𝗲𝘀, 𝘁𝗵𝗲𝘆 𝗰𝗮𝗻!
📄 arxiv.org/abs/2410.10934v1
👨💻 github.com/metauto-ai/agent-…
Introducing 𝗔𝗴𝗲𝗻𝘁-𝗮𝘀-𝗮-𝗝𝘂𝗱𝗴𝗲, a groundbreaking proof-of-concept that reduces costs and time by 97%, while providing rich, intermediate feedback. It precisely captures the natural step-by-step processes of agentic systems. We also developed 𝗗𝗲𝘃𝗔𝗜, a new benchmark featuring 55 automated AI development tasks and 365 requirements. Agent-as-a-Judge not only outperforms LLM-as-a-Judge but also closely mirrors human evaluations with greater efficiency and precision.
The real game-changer? It provides reliable reward signals, paving the way for scalable, self-improving agentic systems.
Thanks my Meta/KAUST mentors/peers/collaborators @SchmidhuberAI @tydsh @zechunliu @vikasc @YoungXiong1 @vikasc @Obs01ete @erniecyc @oneDylanAshley ... – at Menlo Park, CA


Shuming Liu retweeted

📢 Open Call: Fully funded #PhD student positions starting in 2025 at IVUL @KAUSTVision Lab with Prof. @BernardSGhanem
If you are passionate about computer vision and machine learning, contact us now and apply to #JoinOurTeam.
🔗 Our lab: cemse.kaust.edu.sa/ivul – at Kingdom of Saudi Arabia

Shuming Liu retweeted

ColorMAE: Exploring data-independent masking strategies in Masked AutoEncoders
@CarlosH_93 @shuming96 @BernardSGhanem
tl;dr: color masked pixels in green, it helps.
Jokes aside, mid-size continuous regions appear to be better for MAE pretraining.
arxiv.org/pdf/2407.13036


Shuming Liu retweeted

Announcing the creation of *KAUST Center of Excellence in Generative AI*; official launch on July 1, 2024. Joint with @BernardSGhanem @SchmidhuberAI @bremen79 @TheSandyCoder and a few more KAUST colleagues. KAUST funding ($11m over 5 years) + industrial funding. We are looking for further industry partners!
@KaustResearch @cemseKAUST @KAUST_News @AI_KAUST @kaustMLhub

Shuming Liu retweeted
Thrilled to share that our research group at KAUST is making waves at #CVPR2024! We've had EIGHT papers accepted this year. Huge congrats to all the authors and our incredible collaborators! 🦾📚 #AI #ML #ComputerVision @CVPR
Let’s connect in Seattle next week! 🇺🇸 @KaustResearch

Shuming Liu retweeted

Can a language model understand JPEGs 💾? We trained ours 🦙 on raw byte streams, and it learned to speak JPEG-ese! We find the model's can understand file properties, fix anomalies, and generate new JPEGs 🖼️, all while bypassing the decompression step 🚀.
A thread 🧵

Shuming Liu retweeted

We are excited to release OpenTAD: an open-source toolbox for temporal action detection (TAD). OpenTAD unifies the implementation of 14 (more are coming) TAD methods with 8 datasets. Star us and stay tuned for further updates. @KaustVision
Link: github.com/sming256/OpenTAD

Shuming Liu retweeted
🚀✨ SynthCLIP is out! 🎉 In the past few months, I've been working on an end-to-end synthetic pipeline for CLIP training. Today, the paper is out on Arxiv, and our 30M samples synthetic-image pairs dataset is available on @huggingface ! Thread. 🧵
Paper: arxiv.org/abs/2402.01832
