
PhD student @berkeley_ai. Prev. undergrad @MIT, intern @Waymo @GoogleDeepMind
Berkeley, CA
Joined June 2012
- Tweets53
- Following202
- Followers2.5K
- Likes807






Pinned Tweet
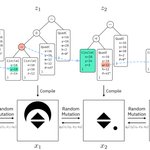
My first PhD paper!🎉We learn *diffusion* models for code generation that learn to directly *edit* syntax trees of programs. The result is a system that can incrementally write code, see the execution output, and debug it. 🧵1/n
wow

π-0.5 is here, and it can generalize to new homes! Some fun experiments with my colleagues at @physical_int, introducing π-0.5 (“pi oh five”). Our new VLA can put dishes in the sink, clean up spills and do all this in homes that it was not trained in🧵👇
Can LLMs do lateral thinking puzzles? I tested a bunch of language models on questions from @lateralcast and the #OnlyConnect gameshow! (1/2) 🧵
I wrote up the full results on my blog, shreyaskapur.com/blogs/later… alongside example outputs from models. (2/2)
Shreyas Kapur retweeted

LMs can generalize to implications of facts they are finetuned on. But what mechanisms enable this, and how are these mechanisms learned in pretraining? We develop conceptual and empirical tools for studying these qns. 🧵


Shreyas Kapur retweeted

Can interpretability help defend LLMs? We find we can reshape activations while preserving a model’s behavior. This lets us attack latent-space defenses, from SAEs and probes to Circuit Breakers. We can attack so precisely that we make a harmfulness probe output this QR code. 🧵
I'll be at NeurIPS, let me know if you want to catch up or chat about program synthesis, world models, neurosymbolic, search, probabilistic programming, or mourning the loss of King Da Ka.
Shreyas Kapur retweeted

I am currently holding my dad's cryopreserved brain tumor samples in hopes of creating a personalized vaccine for immunotherapy. However, there are some critical and time-sensitive questions in the attached post: xitter.cf/tejasdkulkarni/status/…
This is time-sensitive so would appreciate any DMs/RTs.


I had a lot of fun working on this. I didn't believe that a chess playing neural net could learn to do look-ahead just in its weights, so I was definitely the non-believer in this project.

These languages are small, and we only show this approach on a fairly narrow inverse-graphics task. In the future, we hope to show that this approach may potentially work more generally with languages with loops and variables. 8/n
We managed to get part of our project running in the browser,
Website🌎: tree-diffusion.github.io
Paper📄: arxiv.org/abs/2405.20519
Code🖥️: github.com/revalo/tree-diffu…
Thanks for my wonderful collaborator @jenner_erik, and advisor Stuart Russell!
n/n 🧵