Founder & CEO @ Volantis - we’re solving the memory bottleneck by using optics to connect huge amounts of fast memory to chips.
SF Bay Area, CA
Joined August 2013
- Tweets11.5K
- Following488
- Followers3.8K
- Likes50.2K



Pinned Tweet
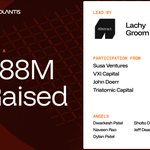
Excited to announce Volantis's $88M Series A.
We are solving Al's memory bottleneck by using optics, enabling chips with huge amounts of fast & cheap memory.
By boosting both the memory bandwidth and capacity per chip by orders of magnitude, we enable ultra-fast inference (up to 10,000 tps/user) for large models (>10T) - with low $/tok to boot.
Initially, this will enable insanely fast agents - think coding agents that finish in minutes or even seconds instead of hours.
More excitingly, optics is a fundamentally scalable way to increase memory systems. Not 2X/year, but by orders of magnitude across new generations. This will enable a structurally new Al industry, including restarting scaling laws, holding entire repos in context windows & more.
Our team has pioneered many core semiconductor technologies: the 1st CoWoS product, early HBM, the 1st silicon photonics CPO systems, the 1st high volume tunable VCSELs, the 1st processors to directly communicate using light & more.
We’ve already sent data >10× farther than equally tiny electrical wires inside a chip package. Our next iteration is already taped out and targets world-record bandwidth density over relevant distances, read more: volantissemi.ai/news-insight…


Choosing whether to allocate scarce watts between low-latency and high-throughput chips is a scary decision
It's hard to predict over the next 3 years how much demand will be low-latency vs high-throughput
Luckily with Volantis, you can have both modes in one chip :)

inference providers have to choose to be either fast or cheap
if you choose speed as a provider, you'll have idle gpus. but if you optimize to be cheap, customers are going to be waiting
the pay-as-you-go pricing model means you pay per token, and the provider pays for gpu time.
being fast means putting fewer people on each gpu, so each token costs more
groq and cerebras chose to be fast. they keep the # of people they serve per gpu low
coreweave, novita, and crusoe chose to be cheap. they charge much less
this is just how gpus work. on a blackwell, if one person uses the gpu alone, they get 1,000 tokens a second, and the gpu produces 1,000 tokens a second in total because one person can't keep it busy
if many people share the gpu, it produces 60,000 tokens a second in total, but each person only gets about 20 to 100 of those

Petrodollar recycling:
Americans buy oil --> Middle East
Middle east buys --> American bonds
DRAM-dollar recycling:
US Tech Companies buy DRAM --> Korea
Koreans receive DRAM bonuses --> Buy US Equities
This is only possible if tiny, submicron wires could somehow cross an entire chip/wafer length in ~2ns
....which might actually be possible ;)

Congrats! Excited to see what comes next

launched a model
accidentally served trillions of tokens a day
29.4% of the fortune 500 showed up
raised a really big series A from @a16z
it's been 3 weeks
we would like to sleep now
We’re solving the memory bottleneck with optics….

Intelligence must draw on memory. The mind must not simply compile data — as an algorithm now does more quickly than we can — but recall lived experiences, which contain depths of meaning that only the human soul can recognize, and connect more deeply with the goodness of these experiences. Everything that is good begins “with the Spirit” and thus possesses a breath, a dynamism and a sense of communion that, once experienced, are engraved upon the heart. vatican.va/content/leo-xiv/e…
Korea is now making about as much in memory profits as the entire middle east does in oil (pre-Iran war)
Doesn’t this technically mean that gpt-6 repaired an incorrect navier-stokes proof by bel?
arxiv.org/abs/2610.08144

Tapa Ghosh retweeted

We've been following @semiDL and team for over a year and are thrilled to be a part of their Series A. Tapa's assembled a world-class team tackling the core problems of memory capacity and bandwidth that hold back model intelligence. Excited to see this team build!

Excited to announce Volantis's $88M Series A.
We are solving Al's memory bottleneck by using optics, enabling chips with huge amounts of fast & cheap memory.
By boosting both the memory bandwidth and capacity per chip by orders of magnitude, we enable ultra-fast inference (up to 10,000 tps/user) for large models (>10T) - with low $/tok to boot.
Initially, this will enable insanely fast agents - think coding agents that finish in minutes or even seconds instead of hours.
More excitingly, optics is a fundamentally scalable way to increase memory systems. Not 2X/year, but by orders of magnitude across new generations. This will enable a structurally new Al industry, including restarting scaling laws, holding entire repos in context windows & more.
Our team has pioneered many core semiconductor technologies: the 1st CoWoS product, early HBM, the 1st silicon photonics CPO systems, the 1st high volume tunable VCSELs, the 1st processors to directly communicate using light & more.
We’ve already sent data >10× farther than equally tiny electrical wires inside a chip package. Our next iteration is already taped out and targets world-record bandwidth density over relevant distances, read more: volantissemi.ai/news-insight…
Tapa Ghosh retweeted

Proud to be an angel investor in @semiDL and Volantis! We as an industry have a lot of work to do to keep scaling intelligence, and we need all the creative minds we can throw at the problem! Moving data around is a central problem and these guys are working on something truly breakthrough.
Excited to announce Volantis's $88M Series A.
We are solving Al's memory bottleneck by using optics, enabling chips with huge amounts of fast & cheap memory.
By boosting both the memory bandwidth and capacity per chip by orders of magnitude, we enable ultra-fast inference (up to 10,000 tps/user) for large models (>10T) - with low $/tok to boot.
Initially, this will enable insanely fast agents - think coding agents that finish in minutes or even seconds instead of hours.
More excitingly, optics is a fundamentally scalable way to increase memory systems. Not 2X/year, but by orders of magnitude across new generations. This will enable a structurally new Al industry, including restarting scaling laws, holding entire repos in context windows & more.
Our team has pioneered many core semiconductor technologies: the 1st CoWoS product, early HBM, the 1st silicon photonics CPO systems, the 1st high volume tunable VCSELs, the 1st processors to directly communicate using light & more.
We’ve already sent data >10× farther than equally tiny electrical wires inside a chip package. Our next iteration is already taped out and targets world-record bandwidth density over relevant distances, read more: volantissemi.ai/news-insight…
Tapa Ghosh retweeted

Well will soon look back on the days of 50 tok/s as dial-up speeds
Excited to announce Volantis's $88M Series A.
We are solving Al's memory bottleneck by using optics, enabling chips with huge amounts of fast & cheap memory.
By boosting both the memory bandwidth and capacity per chip by orders of magnitude, we enable ultra-fast inference (up to 10,000 tps/user) for large models (>10T) - with low $/tok to boot.
Initially, this will enable insanely fast agents - think coding agents that finish in minutes or even seconds instead of hours.
More excitingly, optics is a fundamentally scalable way to increase memory systems. Not 2X/year, but by orders of magnitude across new generations. This will enable a structurally new Al industry, including restarting scaling laws, holding entire repos in context windows & more.
Our team has pioneered many core semiconductor technologies: the 1st CoWoS product, early HBM, the 1st silicon photonics CPO systems, the 1st high volume tunable VCSELs, the 1st processors to directly communicate using light & more.
We’ve already sent data >10× farther than equally tiny electrical wires inside a chip package. Our next iteration is already taped out and targets world-record bandwidth density over relevant distances, read more: volantissemi.ai/news-insight…


Someone should design a scalable hardware system that brings SRAM-system speeds to large, future models!
The world can do much, much better than 300 tok/s/user