

Member of Technical Staff @ideogram_ai | Prev. PhD @UofTCompSci DGP @AdobeResearch @NVIDIA : )
Toronto, Canada
Joined August 2012
- Tweets165
- Following981
- Followers1.1K
- Likes12.6K




Pinned Tweet
Proud of the team! 👏

Selena Ling 凌子涵 retweeted

BREAKING: Ideogram 4.5 (Very Low) by @ideogram_ai ranks #23 in the Image Editing Arena on Design Arena with an Elo of 1189.
At 8.2s per edit, it's over 7x faster than Ideogram 4.5 (High), and at $0.008 per image it's the cheapest model on the board, making it the highest rated model under 9s and leading every faster model by about 90 Elo points.
Congratulations to the @ideogram_ai team on delivering top value and speed in image editing!


Selena Ling 凌子涵 retweeted

We gave four frontier image editing models the same photo and 30 edits in a row: Ideogram 4.5 keeps most of the room intact, while the others drift, GPT Image 2.5 Sunburst most visibly.
We've seen some interesting demos of multi-turn editing consistency from the latest image editing models, so we ran our own test: GPT Image 2.5 Sunburst, #1 on our Image Editing leaderboard, against Ideogram 4.5, FLUX 3 and Nano Banana 2.1. Our leaderboard scores single edits; this tests what happens when 30 consecutive changes stack up, with each model editing its own previous output through a 30-step real estate staging sequence: light the fire, add a sofa, repaint the walls, swap day for twilight, and more.
Why are the final results so different?
@ideogram_ai's Ideogram 4.5 and @bfl_ml's FLUX 3 edit locally. On small edits like adding a vase of tulips, we measured that they left 95% or more of the image essentially untouched. GPT Image 2.5 (Sunburst) re-renders most of the entire image on every edit, leaving only about a fifth of the image unchanged, so small shifts in colour and detail compound over turns. Nano Banana 2.1 sits in between: its edits stay local, but the rest of the image shifts slightly and gradually darkens.
Selena Ling 凌子涵 retweeted

High long term fidelity across many edits is a research breakthrough — and an open weights model helps power a broader community
Selena Ling 凌子涵 retweeted

In the real world, all the positive AI sentiment I hear is from small business owners.
They love the posters, the cool custom websites, accounting, legal help, support agents.
🙌
Thank you, Minister @EvanLSolomon, for your time and your energizing remarks. Our team is more excited than ever to build the foundation of generative media in Canada and bring value to our enterprise customers across the globe.
Selena Ling 凌子涵 retweeted

Excited to announce: In 2027 I'll join the UW Allen School (@UWCSE) in Seattle as tenure-track faculty in Computer Science!
My group will advance core geometry processing + 3D AI for visual computing, science, & engineering. I'll be recruiting PhD students in the next cycle!


Selena Ling 凌子涵 retweeted

We are presenting GimmBO tomorrow at #SIGGRAPH
NPR, Style & Abstraction session, 9-10:30 am, Room 408B.
s2026.conference-schedule.or…


Paper announcement📢 GimmBO: Interactive Generative Image Model Merging via Bayesian Optimization
Chenxi Liu, Selena Ling (@seleniumlzh), Alec Jacobson
🏆 SIGGRAPH 2026 Best Paper
Selena and I will be presenting in LA (July 19-23)!
🌐 Project: gimmbo-project.github.io/
[1/7]

📢Join Chenxi at University of Victoria if you are interested in building systems for creativity!
📢 Joining today as Assistant Professor of Computer Science at University of Victoria, leading the Creative eXperience Lab (CXL). We study how people create and build systems for visual creativity.
Recruiting PhD & MSc: chenxil21.github.io/
Also at SIGGRAPH NA 2026 in LA.
Check out our latest work on image model merging for stylization!
Paper announcement📢 GimmBO: Interactive Generative Image Model Merging via Bayesian Optimization
Chenxi Liu, Selena Ling (@seleniumlzh), Alec Jacobson
🏆 SIGGRAPH 2026 Best Paper
Selena and I will be presenting in LA (July 19-23)!
🌐 Project: gimmbo-project.github.io/
[1/7]
Selena Ling 凌子涵 retweeted

I am *very* excited to announce our SIGGRAPH 2026 workshop:
Lines & Minds: Visual Abstraction in Art, Psychology, and Computer Graphics 🎨🧠🫖
🔗 lines-and-minds.github.io
📅 Sunday, July 19
Join us to explore how visual abstraction shapes how we think, create, and communicate.

Selena Ling 凌子涵 retweeted

Our short film Dear Upstairs Neighbors is previewing at @sundancefest. 🎬
It’s a story about noisy neighbors, but behind the scenes, it’s about solving a huge challenge in generative AI: control.
Developed by Pixar alumni, an Academy Award winner, researchers, and engineers, here’s how it came together. 🎨
Selena Ling 凌子涵 retweeted

This is absolutely shameful. Agents of a federal agency unnecessarily escalating, and then executing a defenseless citizen whose offense appears to be using his cell phone camera. Every person regardless of political affiliation should be denouncing this.

Selena Ling 凌子涵 retweeted

Did Blender help you this year? Help back!
If every active user contributed $5 this month, Blender would be funded for the entire year 2026. Professional 3D software. No subscriptions. No limits. Just your support.
Do your part. Donate today.
blender.org/news/give-back-t… #b3d

ALT Oti the penguin, showing a good example of "giving back".
Selena Ling 凌子涵 retweeted

📢 Lyra: Generative 3D Scene Reconstruction via Video Diffusion Model Self-Distillation
Got only one or a few images and wondering if recovering the 3D environment is a reconstruction or generation problem? Why not do it with a generative reconstruction model!
We show that a camera-conditioned video diffusion model can be transformed into a generative reconstruction model that directly outputs a high-quality 3D Gaussian Splatting representation through self-distillation, without requiring real-world training data.
Check out our results in the video (wait for dynamic scenes in the second half!) :
Project Page: research.nvidia.com/labs/tor…
Code and Models: github.com/nv-tlabs/lyra
Paper: arxiv.org/abs/2509.19296
Selena Ling 凌子涵 retweeted

📢📢📢 3D Gaussian Flats @ #NeurIPS2025
A hybrid 2D/3D representation that reconstructs photorealistic scenes.
🔗 Project: theialab.github.io/3dgs-flat…
📄 ArXiv: arxiv.org/abs/2509.16423
💻 Code: github.com/theialab/3dgs-fla…
Selena Ling 凌子涵 retweeted

Season 1 of Toronto School of Foundation Modelling kicks off this Thursday at New Stadium!!!
60 people will be attending weekly sessions for 3 months, learning to build Foundation Models from scratch. Around 10 guest speakers (more to come) will be flying to Toronto to talk about what they do best.
I'm grateful for the support of Cohere, New, Vengeance and all the donors. I will make this a series worth your time. And apologies to the people I didn't get back to - spots are all taken but will reach out if that changes.


Selena Ling 凌子涵 retweeted

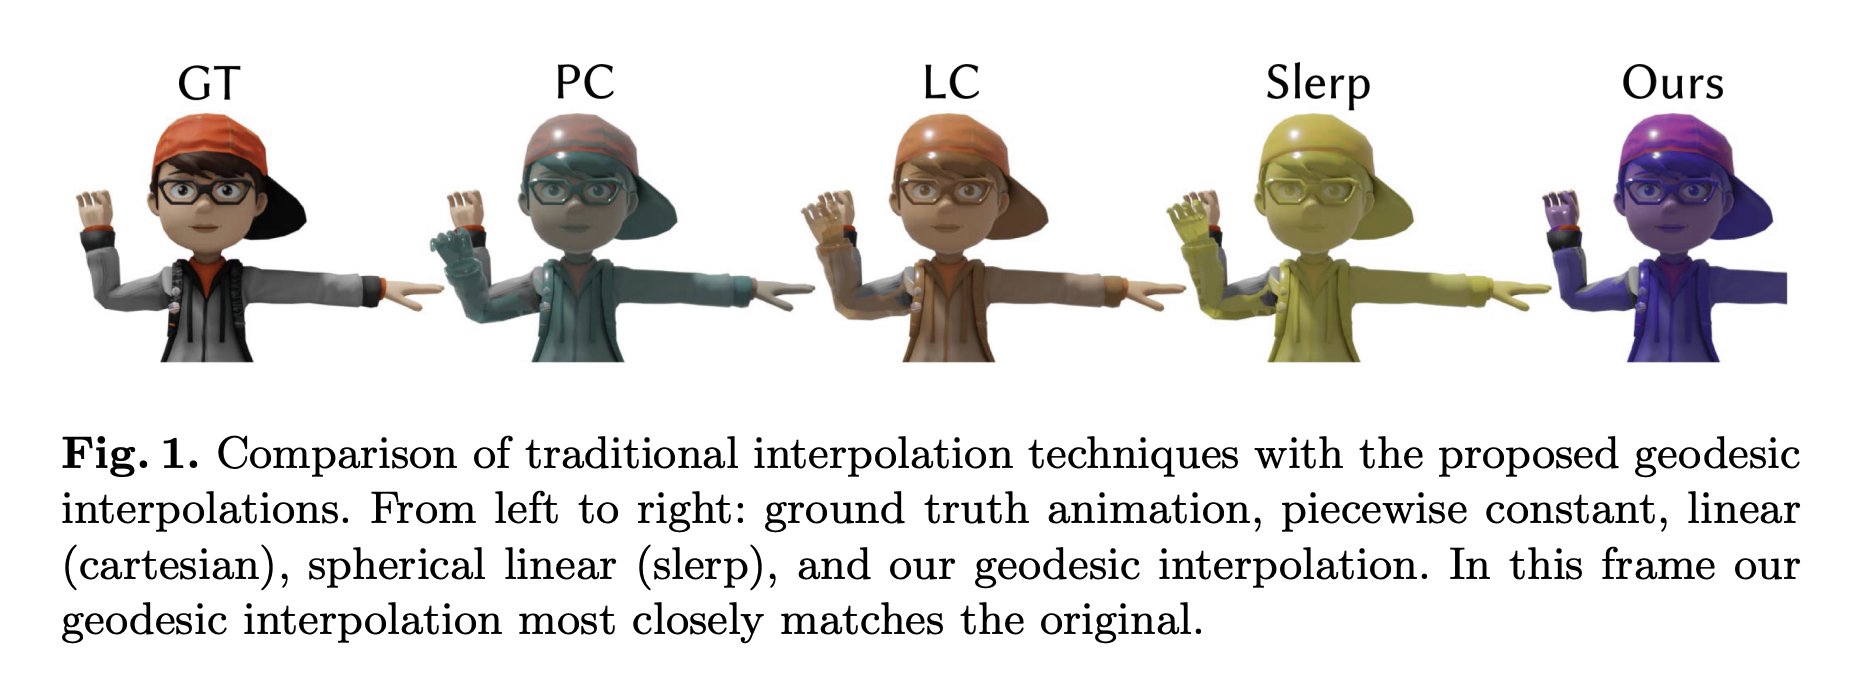
I’m excited to announce that our paper, “Learning Riemannian Metrics for Interpolating Animations,” has been accepted to GSI 2025! 🧵
co-authored with @vm2358 at @UofT and @ninamiolane at the @UCSB @geometric_intel lab!
gi.ece.ucsb.edu/node/217
😍

Every lens leaves a blur signature—a hidden fingerprint in every photo.
In our new #TPAMI paper, we show how to learn it fast (5 mins of capture!) with Lens Blur Fields ✨
With it, we can tell apart ‘identical’ phones by their optics, deblur images, and render realistic blurs.

Selena Ling 凌子涵 retweeted

“Everyone knows” what an autoencoder is… but there's an important complementary picture missing from most introductory material.
In short: we emphasize how autoencoders are implemented—but not always what they represent (and some of the implications of that representation).🧵
