

Security and Privacy are just Myths!
Rajasthan, India
Joined January 2020
- Tweets187
- Following555
- Followers1.2K
- Likes1.5K




Pinned Tweet
Who knew that one conversation would turn into a million-dollar journey of a collab? Forever grateful to this community and the grind. Here’s to many more bugs and breakthroughs with @n1m0_ and @_jensec bhai. 🚀

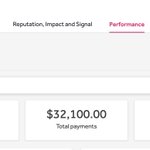
Bug Bounty Success Story: $1M total bounty.
No Tech Background
No Paid Courses
No Certificates
Just Sheer Willingness and Hard work.
I still remember the day 1 when my now close friends
@secseth_ & @n1m0_ asked me to discuss about bug bounty. and now they completed $500k each on @Hacker0x01 a few years later.


🫡


We’re expanding our Cyber Verification Program to give security professionals broader access to our most capable models.
Through this program, verified security professionals can access Claude Mythos 5.1, Opus 5.5, and Sonnet 5.5 with safeguards designed for defensive work.
We’re also opening up new tiers to allow for authorized offensive work, like penetration testing and red-teaming.
anthropic.com/news/cyber-ver…


platforms like hackerone , bugcrowd etc can play a major role in providing independent researchers cyber access. openAI/Anthropic should use them instead of that useless KYC for verification. These platforms have a huge history of researchers work and can better act as a bridge.

Bhavy Seth retweeted

As we prepare to release Astra, we’re focused on making increasingly capable AI safe and broadly accessible.
Astra represents a significant advance in cybersecurity capability, reaching the Critical threshold under our Preparedness Framework.
We're previewing how we evaluated the model, how its safeguards have advanced alongside its capabilities, and what we'll continue to learn and improve.
openai.com/index/path-to-ast…

Bhavy Seth retweeted

In the next 12-18 months there’s really never been a better time to make a million dollars doing bug bounties. If I was young and poor I would be locking myself in a room from now until this time next year and making finding a reproducible methodology or way of hacking that I can scale my primary and only objective in life.
WTH! It's really frustrating. gave them every possible detail for them to trust. not a very good impression @AnthropicAI

1/ Bug Bounty won't die. But it's shifting towards an agent-driven pipeline structure.
The hunters who will thrive aren't the ones prompting models, they're the ones building pipelines efficient enough that the agent knows what to look for.
#bugbounty
Bug bounty is not going anywhere.

I'm extremely unconvinced that Opus wouldn't have found that 27-year-old OpenBSD bug Mythos found if they spent $20k credits on it.

agents that own their own knowledge layer do not need infinite context windows, they need good file organisation and the ability to read their own indexes. this hits same for bug bounty. everyone's using the same models, the edge is what you teach "yours" to "remember".

LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
I can never fully express what I want in a single prompt. My words miss things. The picture in my head doesn't fully translate. So after Claude builds the plan, I tell it: "Now act as a harsh critic of your own work. Find every flaw, every gap, every assumption you made."

An amazing person, always wished to meet him in person. Had some truly great conversations with him over chat. he was deeply passionate about the bug bounty industry and genuinely cared for researchers. Gone too soon. May he rest in peace.🤍🙏


Hey @atlys, this is beyond unacceptable. I applied for a guarantee visa application, and till now, NO visa. My flights are next week(which I informed you from day one). I submitted additional documents, yet VFS status still shows they were NOT submitted by your team.


@atlys What kind of careless, unprofessional service is this? Do you even take customers seriously? In your app, status changes automatically. In your app, it shows today I will get the Visa, while the VFS status shows documents are not even submitted. What an irony!
It is truly an honour🙏. Huge thanks to @Hack_All_Things and entire @Zoom team for running such a great , transparent and responsive bug bounty program. It’s a privilege to contribute in such a program. Grateful for the recognition💙. @Hacker0x01
Friday @Zoom Bug Bounty researcher spotlight on @Hacker0x01 researcher @secseth_ . One of our top security researchers with over 40 valid report submissions to the @Zoom #bugbounty program! Thank you Bhavy for all your great work and gracious professionalism!

Always a Great Team to work with🔥🔝
The D-Day Campaign top contributors results are in! Congratulations freesec on being the top report submitter! Thanks to all for your participation. DM me your shipping address on Zoom chat to receive promised @Zoom swag!
