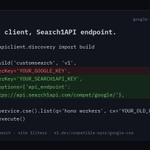
Google CSE JSON API customers have to move by Jan 1, 2027. Search1API has a compatibility endpoint.
> Keep cse().list() and items[].title / link / snippet parsing
> Change the endpoint and API key
> First-page web search; check the limits first
s1.dev/compatible-apis/googl…
Try any Search1API endpoint from the homepage.
> Pick a tab, type a query or URL
> It opens the Playground with your input filled in. Nothing runs until you press Send
> Or hit Onboard your agent to copy a setup prompt for Claude Code, Codex or Cursor
s1.dev/?utm_source=x&utm_med…
Search1API is an official plugin for ChatGPT and Codex. @OpenAIDevs
> One plugin, shared by ChatGPT and Codex
> Search the web and news, then read the pages behind the results
> Ask Codex to check a dependency upgrade against its changelog and issues
s1.dev/integrations/chatgpt?…
Zhihu articles and answers, as clean Markdown.
Send a Zhihu link to Crawl:
> column article: headings, lists, code and images kept
> answer link: that exact answer, never an excerpt or a different one
> author and publish time when the page has them
s1.dev/zhihu-scraper-api?utm…
YouTube videos, as timestamped transcripts.
Send a YouTube URL to Crawl:
> video: the full transcript, every line timestamped
> playlist: each video's title, channel and duration
> no captions: an honest partial, gaps named
No Google account needed.
s1.dev/youtube-scraper-api?u…
Crawl a whole docs site from the browser, no code. DeepCrawl is now in the Search1API Playground.
> Paste a URL, crawl the sitemap or all links
> Watch progress, then download a ZIP
> cURL, TypeScript and Python snippets for when you move it to code
s1.dev/deepcrawl-api?utm_sou…
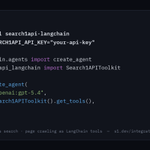
Search1API has an official LangChain toolkit. @LangChain
> pip install search1api-langchain
> Search1APIToolkit().get_tools() gives your agent web search, news search and page crawling
> Built on our Python SDK: auth, retries and timeouts handled
s1.dev/integrations/langchai…
Your agent found the sources. Now it shows them.
render_results in our MCP server turns results it already has into expandable source cards in ChatGPT and Claude.
Cards adapted from @rareuiHQ's Web Search component.
s1.dev/mcp-server?utm_source…
Search1API is on Vercel Connect. @vercel
> Retrieves Search1API credentials at runtime for the authorized user
> Access scoped to project and environment
> Pairs with our AI SDK tools for search, news and page reading
s1.dev/integrations/vercel?u…
Quick add: Yandex is worth checking when your agent needs results for Russian-language queries, where global indexes tend to be thin.
A third general web index for your agent: Yandex.
search_service: "yandex" brings its own index and ranking, with stronger Russian-language and CIS coverage than Google or Bing.
Same endpoint and JSON shape, so a cross-check is one field change.
s1.dev/yandex-search-api?utm…
Bing China, as an engine on Search1API.
search_service: "bingcn" returns Bing's Mainland China ranking, a different result set from both international bing and baidu.
Send it with a Baidu query in one batch request to cross-check the Chinese web.
s1.dev/bingcn-search-api?utm…
Static ISP proxies now have a 3-day plan.
Pro: $1.99 for 3 days, a dedicated ISP IP
Premium: $3.99, an IP2Location-verified ISP line
One payment, no auto-renew, non-refundable. Want to keep the IP? Switch it to monthly before the 3 days end.
s1.dev/proxies/static-isp?ut…
Grokipedia, now an engine on Search1API.
search_service: "grokipedia" returns each entry's title, link and opening text, usually the definition.
Handy for SDKs with no Wikipedia article. crawl_results adds the full entry and references.
s1.dev/grokipedia-search-api…
Replying to @iamlukethedev
Thanks for the roundup, and for the care Hermes puts into reviewing plugins. Glad search1api made it into the official catalog — that review process is what keeps the ecosystem trustworthy.
Live web, as native OpenClaw tools.
openclaw-search1api installs from ClawHub and adds search, news, page reading, sitemap and trending as first-class gateway tools. No MCP config.
Auth: SEARCH1API_KEY, your s1 login, or OpenClaw secrets.
s1.dev/integrations/openclaw… @openclaw
Reddit threads, as Markdown.
Send a public Reddit URL to Crawl:
> post: body plus the full comment thread
> subreddit: the listing (hot / new / top)
> user page: that account's public activity
Authors and dates kept. No Reddit account or OAuth app.
s1.dev/reddit-scraper-api?ut…
Replying to @harleyfoote_ @NousResearch
Fair concern. "In-process" just means no separate MCP server. Pages are fetched server-side by Search1API; the plugin only gets Markdown, nothing runs locally. Page-text injection applies to any web tool; the real boundary is the agent's tool approvals/sandboxing.
Replying to @joerg_peetz @NousResearch
Thanks, that was the goal. The bundled skill also tells Hermes which filters fit a quick lookup versus deep research, so the depth of a search matches the question.
Paste a URL, get clean Markdown. Free, no signup.
Reddit, X, YouTube, GitHub and Hacker News links get a dedicated parser: the thread with comment authors in order, or just the README. No menus.
Other pages: main content, with a browser fallback.
s1.dev/tools/url-to-markdown…


