
Co-founder @Calibre_Labs | Applied AI research & consulting | Agents, AI Evals | prev EVP @amplitude_HQ | VC @khoslaventures @sequoia | @stanford @iitbombay
Joined May 2009
- Tweets6.7K
- Following381
- Followers9.5K
- Likes7.8K




AI long form writing with a good skill/examples has now gotten good enough with a few models that i actually like having it to do the final-but-one draft.
in a few months (weeks?) pangram scores will be irrelevant. we will still see slop but wether AI was used will no longer be the right flag.
love seeing a new open source success 🫡🇺🇸

We just served 1 trillion tokens of Beam in 24 hours. To celebrate, we've reset everyone's limits.
Go build something big 👉 platform.reflection.ai
congrats Hamel! you’ve been such a big inspiration for me and @justinjbauer as we work with clients on AI ❤️


$META is going to have a good q4


product release videos got fully automated at the same time grokbot started monitoring twitter for us.
nobody can say this timeline doesn’t have a deep sense of irony.
🙌 no eval rubric == no product strategy in AI

These days, you can pretty much solve any task by defining an eval and hillclimbing over it, instead of directly defining the deterministic/agentic workflow to solve it.
The data provider companies' entire job is to define evals for all economic activity to make the frontier models capable of doing anything.
Your job then becomes pointing frontier intelligence in the right direction - defining what to solve, and how to measure what good looks like.
Agent application interfaces will evolve to capture this. The most complex processes will still need some sort of explicit workflow builder interface, but most tasks can be compressed into goals and eval instructions.

Sandhya retweeted
Introducing OpenSource Clay killer
- 85% cheaper than clay
- Most accurate on people-search bench
- 25x faster
- Run GTM directly in claude code or codex
Try it at treg.to/people-search
Repo link below 👇
Big day for 🇺🇸 OSS 🫡
Introducing Beam: a highly efficient agentic open model with 501B total parameters and 23B active.
- Frontier reasoning efficiency
- Advances the Western open frontier on coding & agentic tasks
- Trained end-to-end from scratch
Full weights release this month.
Learn more about Beam: reflection.ai/beam

one side effect of agentic work getting very good is it allows me to think a lot more about what i want to build without worrying about the deadline coming up. the execution of well articulated ideas (with context and artifacts ready to go) is 100x faster.
i can’t overstate how much i am enjoying this as a professional procrastinator when i am still searching for perfect clarity 😁
Sandhya retweeted

reading feynman lecturess as feynman intended: with accompanying ai-made demo sections for each chapter
rapid acquisition of knowledge is possible thanks to superintelligence
The integrated experience in google slide/sheet/email still feels stuck in q4 2024 chatbot era.. if argon is this good, google has an agent harness problem, not a model problem?


super helpful! i have literally never used low effort for obv reasons and will try it out today for storming a new idea, was definitely missing this interaction type with how eager 5.5 is to get shot done


Loved the recent article on evals from @HamelHusain
and @sh_reya in the @lennysan newsletter. One question we get everytime with PMs is what evals to write for long horizon agents that do a broad swath of work (what H/S call error discovery, similar to product discovery).
Below is a great framework for how you can organize these discoveries as a product team:
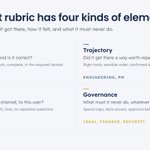
1️⃣ Outcome - were the results great
2️⃣ Trajectory - was the process followed correct
3️⃣ Experience - did it feel right
4️⃣ Governance - did it follow critical rules
You start with your product pov, but the only way to hone focus is to look at traces (trace analysis). Here's an example of an annotated trace for a local shopping assistant called Corner and how often the trace reveals flaws before they become obvious to the customer.
claude.ai/artifact/PBvMFLueC…

Full articles:
Eval Rubric: blog.calibrelabs.ai/p/an-eva…
Advanced Evals preview: lennysnewsletter.com/p/advan…
I don't know how much of it is a "no mannered prose" instr and how much the post-training but coding with Opus 5.5 feels spectacular in terms of comms.
It's also a very eager model, jumping on tasks before I'm quite ready to act on my plans, getting used to life on the edge :/
I've been pushing it on product taste and have noticed giving it a small sample of your strongest opinions works wonders, it comes up with better ideas than most PMs tbh.