
Long time coder, new and learning AI Engineer
Portland, OR, USA
Joined May 2007
- Tweets2.5K
- Following178
- Followers384
- Likes158






Nice to see the inclusivity
Both slow and fast Zombies welcome
eventbrite.com/e/zombie-scav…

Interesting split happening in AI models: alongside the big reasoning models, there's a growing class of small ones that just decide things (Jev's).
Microsoft-Decision-1 does routing, classification, prioritization and verification, returning structured output software can act on. Microsoft reports it at 2.5x the speed of the runner-up in their benchmarks.
commandline.microsoft.com/mi…

Wikimedia's bandwidth use is up 50% since 2024 because of bot traffic, and 65% of its most resource-heavy requests now come from bots.
Undisclosed bot edits in sandbox areas, edits to a citation tool's config to misuse it as a proxy, failed attempts to abuse a public Etherpad, and millions of API calls that may have contributed to a Wikidata Query Service outage in May.
The cost of agents behaving unpredictably lands on volunteers and non-profits, not the companies shipping them.
I'm not against AI, but please do better Frontier Labs
diff.wikimedia.org/2026/10/0…

Claude Code (the app) is going through some major overhauls...
You can now write small JS modules that live inside a Claude Code session and see every event as it happens.
They work like middleware. Your hook runs, then other plugins, then Claude Code itself. So you can watch a tool call, rewrite it, or refuse it. This guide builds a context window forecast drawn above the prompt in about 80 lines.
claude.dev/blog/getting-star…
#ClaudeCode #HarnessEngineering

Several leading closed models score near zero on a security benchmark because they refuse the task, not because they can't do it.
@MistralAI's launch post for Mistral Large 4, a 1 trillion parameter multimodal model with 49 billion active parameters, weights due by the end of the month.
On a test that asks a model to reproduce a real vulnerability in open-source software and then patch it, ML4 scores 82%.
Defenders often need to prove a flaw is real before they can fix it, and provider-level refusals block that work. Open weights plus self-deployment means you set the policy.
mistral.ai/news/mistral-larg…
#AI #OpenWeights

OpenJev (running locally) vs Typesafe Jev in a dungeon crawl text adventure test harness
writing.alteredcraft.com/p/t…

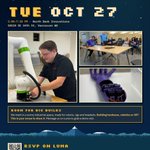
Join us at the next Cascadia Builders Club meetup
We are a community for people building hardware and software.
This is show-and-tell for builders: short, hands-on demos of what you're actually making (apps, hardware, robotics, XR), and then we hang out and meet the people behind the work.
No pitch, no hype reels, just real things and the people making them.
cascadiabuilders.club/
#Portland #Robotics #Meetups

A speech recognition model that fits in 16.9 MB, runs on plain CPU, and reaches its first token in 11 milliseconds.
Introduced Whistle on the @cactuscompute blog. It handles seven languages, word timestamps and speech embeddings.
cactuscompute.com/blog/whist…
Benchmarks against Whisper base and Moonshine tiny are in the post, with the gaps shown in both directions.
In the same spirit, I also covered a new STT model from Microsoft AI in the last Weekly review: writing.alteredcraft.com/i/2…

Nice, in the revamped @claudeai projects a subagent can start a subagent.
It’s subagents all the way down!
#ClaudeCode #Agents

And yet the Decision Model mania continues. Now with a frontier lab entering the ring. @OpenAI admitted that currently the Decisions API is backed by a optimized Luna and harness and was in reaction to @typesafeai 's Jev

That said, there were some other very interesting events in AI last week.
Check out Altered Craft's weekly review, a human curated list the the top AI Tutorials, Tools, and News of the previous week.
writing.alteredcraft.com/p/w…
After years fully focused on AI in my craft, software development, I'm finding it is increasingly entering other pursuits.
#ClaudeCode #3D #AI
For me, recent releases such as the revamped Claude Code Projects and easily accessible agents such as Dots, Muse, and GrokBot have given me the option to leverage AI outside coding with little friction.
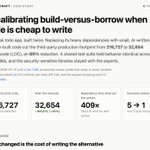
Have you heard, code is now cheap.
I this post / case-study I analyze the realities and impact of that in the context of 3rd party dependencies in your app.
alteredcraft.github.io/3p-de…
#AIEngineer #AICoding

This weeks edition is out. These are all the Tutorials, Tools, and News I found last week which exhibited high signal, low hype.
Continued evidence of the shift from the bizarre token-maxxing to value-maxxing ( oh, all the terms... )

Checkout the full edition here and always grateful if you choose to subscribe: open.substack.com/pub/altere…