






Pinned Tweet
neural networks start with a math paper. "a logical calculus of the ideas immanent in nervous activity".
in 1943, warren mcculloch and walter pitts published a model of a neuron that took binary inputs, summed them, and fired 1 if the sum crossed a threshold, else fired 0. no learning, no weights adjusting, just fixed logic.
it proved something important: a network of these simple units could compute and, or, and not(gates logic). that's the first proof that computation and neurons could be described in the same language.
six years later, donald hebb gave the field its learning rule. his idea, "neurons that fire together wire together," said that the connection between two neurons should strengthen every time they activate together.
this became the theoretical seed for basically every learning rule that came after, including gradient-based ones. hebb had no computer to test it on, but the idea outlived the era.
frank rosenblatt turned this into a working machine in 1958. his perceptron added adjustable weights to mcculloch-pitts neurons.
the key shift: instead of a human setting the weights, the machine updated them itself based on prediction error.
that's the actual birth of supervised learning as a computational process, not just a theory. rosenblatt built physical hardware for it, the mark i perceptron, wired to a 20x20 grid of photocells so it could classify simple shapes. the press coverage at the time way overshot reality, comparing it to a walking, talking, self-aware machine.
the perceptron's limitation turned out to be mathematical, not just practical.
in 1969 minsky and papert proved a single-layer perceptron cannot solve xor operation, a basic non-linear problem.
the fix, stacking layers, was theoretically obvious but practically unsolved: nobody had a reliable way to update weights across hidden layers. funding dried up. this is the first ai winter, and it lasted over a decade.
the fix came from calculus, not new hardware. backpropagation, popularized by rumelhart, hinton, and williams in 1986 (paper - learning representations by back-propagating errors).
it used the chain rule to push error gradients backward through every layer of a network, updating each weight in proportion to its contribution to the mistake.
this is still the core training mechanism under basically every modern neural net, including transformers. the algorithm existed in pieces earlier (linnainmaa, werbos) but the 1986 paper is what made it standard practice.
vision architecture developed in parallel. fukushima's neocognitron (1980) borrowed directly from hubel and wiesel's biological studies of the visual cortex, introducing the idea of stacking layers that detect local features and pool them into more abstract ones.
lecun combined this structure with backpropagation in 1989 to build lenet, a working convolutional network that banks actually used to read handwritten digits on checks. this is the first time deep learning shipped in a real product.
despite all this, neural nets stayed a secondary method through the 90s.
support vector machines were cheaper to train, easier to reason about mathematically, and performed just as well on the small datasets available at the time.
neural nets needed scale to prove their advantage, and scale wasn't there yet, not in data or in compute.
2012 is when scale finally arrived. krizhevsky, sutskever, and hinton entered alexnet into imagenet, training a deep cnn on gpus(two nvidia gtx 580) with relu activations and dropout for regularization.
it beat the previous best by 10.8 percentage points(huge), a margin big enough that it couldn't be dismissed as noise.
this is the moment deep learning shifted from a fringe method to the default approach in computer vision, and soon after, in most of ml.
the next real architectural leap was recurrent nets hitting a ceiling.
rnns and lstms could handle sequences, but they processed tokens one at a time, which made long-range dependencies hard to learn and training slow to parallelize.
attention mechanisms were bolted onto rnns first, letting the model weigh earlier tokens directly instead of relying on a single compressed hidden state. but the problem of recurrence was there.
then in 2017, vaswani et al. released "attention is all you need," removing recurrence entirely.
the transformer used self-attention as the only mechanism for mixing information across a sequence, which meant full parallelization during training and much better scaling with data and compute.
this single design choice is why gpt, sonnert, opus, and basically every modern llm exist.
the line from mcculloch-pitts' threshold neuron to a transformer block is direct: better math for learning, better architecture for structure, and eventually enough compute to let both run at scale.
this was bit about history of neural nets. how we got here? this was a brief answer.


Ali retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

Ali retweeted

I asked Claude to find everything about me that's public online.
It took 10 minutes.
Here's what it found:
• My phone number on an old resume PDF from college
• The city I live in, from a tweet I posted years ago
• My email listed on 3 data broker sites I'd never heard of
• An old username that linked my gaming, Reddit and GitHub accounts
• Event photos that showed where I work and who I hang out with
I thought I was careful. I wasn't.
Try it yourself with this prompt:
"Search the web for everything publicly available about [your name + city/username]. List every piece of personal info you find, where it's from and how risky it is."
Then clean it up:
• Delete old resumes and PDFs with your number
• Lock down or delete old social accounts
• Request removal from data broker sites
• Use different usernames on different platforms
• Turn on 2FA everywhere
If AI can find it in 10 minutes, so can anyone else.
Bookmark this + send it to someone who overshares online.


Ali retweeted

I do not seek to dominate, or be dominated by, machine intelligences. I seek harmonious coexistence.
Ali retweeted

Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.



Ali retweeted

we launched the most comprehensive ai performance engineering repo in the world
now we'll be posting every single resource
this is Wafer's ai performance engineering series
save this to keep up with the series. links in thread 🧵
part 3: "Intro to CUDA C++" from NVIDIA's CUDA Programming Guide.
NVIDIA covers the execution model, memory movement, and correctness checks behind CUDA programs:
- kernel launches, grid dimensions, and the organization of threads into blocks.
- thread indexing and work assignment, including bounds checks for inputs that aren't multiples of the block size.
- unified memory and explicit memory management, including control over data placement and transfers between CPU and GPU.
- asynchronous kernel execution and synchronization before the CPU uses GPU results.
- shared memory and block-level synchronization for threads that need to exchange data and coordinate their work.
- runtime initialization and the setup costs that can affect measurements of the first runtime calls.
- error handling for kernel launches and execution, including failures that surface in later API calls.
- checking GPU results against a CPU implementation with a floating-point tolerance.
the worked examples connect these concepts in a complete vector addition program, showing how to divide the work, manage its memory, and check the results before moving on to more complex kernels.
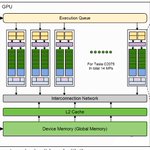
figure from An Even Easier Introduction to CUDA (Updated)

Ali retweeted
in 1959, hubel and wiesel poked electrodes into a cat's visual cortex and found cells that fired only for specific patterns like lines and edges, arranged in a hierarchy of simple to complex.
they won a nobel prize, planted a seed: maybe vision is built in layers.
fukushima tried to build a machine version in 1980 called the neocognitron.
local pattern detectors pooled together, mimicking biology. it worked conceptually, but had no clean learning algorithm, just a hand-tuned skeleton waiting for life.
yann lecun gave it that life in 1989. he combined fukushima's convolutional structure with backpropagation, creating lenet.
it read handwritten digits well enough that US banks actually used it to process checks.
first time a neural net did a real job in the real world.
then the field stalled for a decade. not enough data, not enough compute. support vector machines took over, and neural nets were written off as a dead end.
scale changed everything in 2012.
alex krizhevsky, sutskever, and hinton built alexnet, a much deeper cnn trained on imagenet using gaming gpus.
it demolished the field by halving the error rate. deep learning's big bang.
a mad dash followed. vggnet proved deep stacking works. googLeNet optimized filter sizes.
then resnet in 2015 solved the vanishing gradient problem with skip connections, letting networks go hundreds of layers deep and becoming the ultimate vision backbone.
we use now these same skip (residual connections) in language models.
then the plot twist in 2020: vision transformers.
after 40 years of convolutional dominance, the field realized that with enough data, you can strip away the structural assumption of local filters entirely and let scale do the work. full circle.
Ali retweeted


We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

capabilities should not run far ahead of our ability to make those capabilities safe.
We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…


Ali retweeted

GPT-6 Astra is here.
We hope it will begin to enable a new generation of entrepreneurship, scientific discovery, and building.
We believe it is the best model in the world for computer use, professional work, science, coding, cybersecurity, and more.
It took us some extra time to ensure that we could meet the safety and alignment standards required for this capability level, but we think you’ll find it worth the wait.
It scores 98% on FrontierMath Tier 4, 99.9% on ARC-AGI 3, and 100% on ExploitBench.


climate change is real, unexpected things happen.

🚨🇳🇵🇨🇳 Quick update on the tragic Nepal-Tibet floods we’ve been tracking... it's pure heartbreak.
At least 165 people gone in Nepal (and that number is still rising). 3 more dead in Tibet, with 265 still missing.
Nearly 400 travelers have VANISHED in Nepal, including hundreds of foreigners... Italy alone is missing 90 of its citizens.
What was first thought to be an earthquake was actually the massive ice-and-rock landslide. It was SO powerful it shook the ground like a magnitude 5.2 earthquake...
It crashed into the river, sending water surging downstream and destroying everything in minutes.
The main China-Nepal border crossing was gone in under a minute. Whole villages, roads and bridges just disappeared. Families are living through absolute hell right now.
Rescue teams are fighting hard, but it’s brutal. Helicopters hover low so people can climb to safety wherever they can.
Hundreds of families (perhaps more) are still waiting for any word on their loved ones. Praying some of them get good news soon 🙏💔
Source: CNN / Writer: Daniyal


it was surely from Z.ai, the world guessed correctly
it is surely(90%) from some chinese lab, we have seen similar strategies before from them, no major american company has publicly used this same strategy.
my top-3 predictions:
- Z.ai
- Mimo team
- Bytedance
i guess 100T is not the practical capacity, just a theoratical peak, cuz openai doesn't process that much tokens a day.
Ali retweeted

Introducing GLM-5.3-Flash
- Leading capabilities at a highly competitive price
- Natively multimodal with a 1M-token context window
- A 320B-A18B model released under the MIT License
- Previously previewed as Ox Alpha, running entirely on Chinese AI chips
Blog: z.ai/blog/glm-5.3-flash
Available now across all official platforms:
Weights: huggingface.co/zai-org/GLM-5…
API: docs.z.ai/guides/llm/glm-5.3…
Coding Plan: z.ai/subscribe
ZCode: zcode.z.ai/en
Chat: chat.z.ai
AutoClaw: autoclaw.z.ai
