

developer advocate & product research @ NVIDIA AI views are my own
Joined June 2024
- Tweets28
- Following75
- Followers39
- Likes24
NVIDIA Nemotron 3.5 Transcribe is the perfect example of jack of all trades.
Its ability to do speaker attribution, translation, and audio Q&A not only in a few but 40 different languages is exactly the reason why it lives up to the hype.

Meet NVIDIA Nemotron 3.5 Transcribe 🎙️
An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint.
Watch it keep track of who said what when everyone’s talking at once.
1/ 🧵
Also did a live stream showing y'all how to do it!
Post-Training Nemotron for Europe | Nemotron Labs xitter.cf/i/broadcasts/1oKMvNPdv…

1
97
Another blog done on how to use Nemotron to post train for regional context!
All of the information (and tools) are ready for you to use - so have fun and so excited to see what you guys build!
Build AI agents that speak the language and understand the local context.
Here's 5 steps to learn how to post-train NVIDIA Nemotron with synthetic data and LoRA to adapt its responses for regional terminology, policies and tone.
Follow the step-by-step tech blog: nvda.ws/4zeRBxd
28
sophie a retweeted

Build AI agents that speak the language and understand the local context.
Here's 5 steps to learn how to post-train NVIDIA Nemotron with synthetic data and LoRA to adapt its responses for regional terminology, policies and tone.
Follow the step-by-step tech blog: nvda.ws/4zeRBxd
sophie a retweeted
Post-Training Nemotron for Europe | Nemotron Labs xitter.cf/i/broadcasts/1oKMvNPdv…
Why have one new model when you can have two?
Nemotron 3.5 Super VL dropped today - with the intelligence of Nemotron 3 Ultra at just a 120B parameter size.
We also dropped Nemotron 3.5 Bolt - a 2 bit version of Super VL designed for the RTX Spark.
blogs.nvidia.com/blog/nemotr…

1
3
114
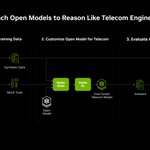
Telcos are just one of the many industries tapping into the benefits of open models, with 89% of operators building using them. @nvidia has been working with companies like @ATT on everything from fine tuning to locally deploying AI. Read more below!
nvda.ws/4xPCOr7

The work the Nemo Speech team is doing is incredible! So glad to see so many of you hype for this technology and even happier to answer all your questions!
Huge thank you to everyone who downloaded Nemotron 3 Diarization and helped it trend on @huggingface! And we appreciate all the comments.
@sabbassi_11 answered a few of your questions:
4
179
sophie a retweeted

Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry.
Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to come.
But its full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.
This is bigger than a single product. It's the beginning of an open ecosystem to build the trust layer for safe agent systems.
Together, we are building the foundation of the AI economy.
Trust and innovation are not in conflict. Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world. nvda.ws/4hcoq7m

sophie a retweeted
When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗
Check me out! Learn something new today!
How can a 30B-parameter model activate just 3B parameters per token and still draw on the full model’s capacity?
Learn how dense and MoE models use parameters differently, and what that means for throughput, memory and serving complexity.
Check out our new technical explainer: nvda.ws/4Aaix21
2
18
2,339
sophie a retweeted

30B post-trained on the Ontology loop beat 550B
Specialization > scale
“Supply chains are the operating system of the physical economy, and AI factories are among the most complex systems ever built.”
“NVIDIA has arguably the most valuable, intricate, and complex supply chain in the world.”
“This doesn’t mean the smaller model is more capable overall. Its gains are concentrated in the domain it was post-trained on.”

sophie a retweeted

I'll be attending #NVIDIAGTC Berlin and talking about open technologies for AI.
I’ll be sharing how we build NVIDIA Nemotron models - from architectures, training data, and weights to post-training recipes and evaluation - and how you can inspect, adapt, and deploy them for domain-specific work.
Don't forget to use my code to get 25% off your pass: GTC-NVP8A3H2
Hope to see you there: nvidia.com/en-eu/gtc/session…


sophie a retweeted
Exciting day for NVIDIA and @huggingface.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty. They allow every developer, startup, university, industry and country to build with, customize and benefit from AI.
Thank you @ClementDelangue for coming to me.
NVIDIA is going to be a great home for Hugging Face, its community and the future of open models. 🤗
blogs.nvidia.com/blog/nvidia…

sophie a retweeted

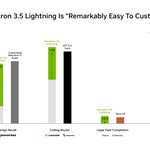
Lightning fast to customize. Lightning fast to run.
NVIDIA Nemotron 3.5 Lightning is a compact, customizable open model built to help always-on agents complete specialized tasks faster.
Kari Briski joins @MTSlive to explain how Lightning helps always-on agents work faster.
NVIDIA knows the importance of supporting your "local" community.
Perplexity's newest release Portable Computer runs Perplexity Computer's agent harness, orchestrator, and post-trained model locally on hardware your very own DGX Spark.
The future is now, and it is yours to keep

Today we’re launching Portable Computer on @NVIDIA DGX Spark.
Portable Computer is a fully local version of Perplexity Computer, where the entire runtime: orchestrator LLM, subagent LLM, agent harness all run on your local hardware. No cloud dependency.
sophie a retweeted
Our general-purpose coding agent just scored 100% on the ARC-AGI-3 interactive reasoning benchmark.
NVIDIA AVO completed all 183 levels across all 25 public environments, figuring out what to do with no instructions, explicit rules, or stated goals.
sophie a retweeted
The right model depends on the task.
NVIDIA NeMo Switchyard helps developers route each agent workflow step across a chosen model pool based on their own quality, latency and cost criteria.
Kari Briski joins @MTSlive to explain why agent workflows need model routing.


