

Former exec at Microsoft, Airbnb, Amazon. Teaching interactive Zoom class on A/B Testing at https://xitter.cf/t.co/6jHfCKuOXC Co-author of https://xitter.cf/t.co/xqmAdDs9oH
Los Altos, CA
Joined September 2007
- Tweets1.2K
- Following405
- Followers3.7K
- Likes3.2K




Pinned Tweet
Our book, Trustworthy Online Controlled Experiments: A Practical Guide to A/B Testing, sharing learnings by Diane Tang from #Google, Ya Xu from #LinkedIn, and my own from #Amazon and #Microsoft (I'm now at #Airbnb) is available for pre-order on Amazon:
bit.ly/expBookLI
Lightning Lesson on Maven (free): A/B Testing Replication Crisis: Lessons from 10 Large-scale A/B tests.
Register at bit.ly/ABTrustworthyPatterns… (March 4, 2026, 10AM PST).
Claims of large lifts in A/B tests are widespread, yet many are supported by small online experiments that are likely underpowered.
To address this, the Trustworthy A/B Patterns project, a community replication effort, evaluates selected patterns at high statistical power.
We share the design and results from 10 A/B tests across four patterns tested with millions of users:
🔘 Rounded buttons
⚡ Page performance
🎟️ Coupon-code fields
📌 Sticky call-to-actions
In this 45-minute lightning lesson, we will cover key experimental design choices, actual results, and practical lessons learned.
#abtesting #experimentation #experimentguide #causalinference #statisticalPower

The Winner's Curse: 10 Large-Scale A/B Testing Replications.
Here is a summary of the 10 replications completed for the Trustworthy A/B Patterns community project: bit.ly/trustworthyABPatterns…
In June 2024, @lukasvermeer, @jlinowski, and I, started a community project to replicate patterns after seeing an implausible lift for rounded vs. square buttons. The first three replications confirmed that the initial results were highly exaggerated (summarized at bit.ly/powerAnalysisEssentia…).
But what about other common patterns?
We have now summarized seven additional A/B tests across four patterns (rounded buttons, page performance, coupon-code field, and sticky call-to-action). These experiments were large, with a median of 2.2M users per experiment and 80% power at our pre-selected minimum detectable effects (MDEs) of 0.3% to 2.2%.
#ABTesting #ExperimentGuide #TrustworthyABPatterns
We invite you to join the community project. See bit.ly/trustworthyABPatterns. We offer free help to design and analyze your replications in exchange for sharing the results.

Want to run A/B tests you can trust—and ship faster with fewer false wins?
My next Maven cohort of Accelerating Innovation with A/B Testing starts Jan 26, 2026 (5 live, interactive sessions × 2.5 hours).
✅ Start time: 12:00pm Pacific (later time for once, as requested by folks in Australia & New Zealand)
⭐ Maven rating: 4.8/5.0
💬 Highly interactive: lots of Q&A, real stories, messy problems, not just theory
Sign up here: bit.ly/ABClassRKT
A couple of testimonials from the last cohort (bit.ly/ABClassRKTestimonials):
- I highly recommend this course. Ronny is a great lecturer who covers a fantastic set of topics, striking the right balance for both new and experienced experimenters. The sessions are highly interactive, offering plenty of room for Q&A and discussion -- Algorithms Analytics Manager, Taboola
- One of the best courses on experimentation I have taken, with a strong focus on real-world learnings. Ronny is a genius. He is extremely patient and great at answering questions with practical, experience-driven insights -- Lead Data Scientist, Docusign
#ABTesting #ExperimentGuide #DataScience #ProductManagement @MavenHQ
Our paper, Statistical Challenges in Online Controlled Experiments: a Review of A/B Testing Methodology, is now the 13th most read paper of all time in The American Statistician (measured by views, now over 25,000).
It's open access so PDF is downloadable.
- Main paper: tandfonline.com/doi/full/10.…
- Supplement: tandfonline.com/doi/suppl/10…
Most read statistic page: tandfonline.com/action/showM… (switch to "All time" tab at the top).
#abtesting

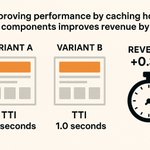
Improving performance by caching home page components improves revenue by ~0.3%.
See bit.ly/PerfABPattern for details.
Talabat, a subsidiary of Delivery Hero, ran an experiment with Eppo by Datadog to measure the revenue impact of a speedup of the home page achieved via smart caching. The speedup in Time-To-Interactive (TTI) was from ~2.1 seconds to ~1.0 seconds.
Revenue per user improved by 0.36%. Applying a haircut because of sequential inference, we believe an unbiased estimate is ~0.3%.
#ABtesting #experimentguide #perf

Note:
1. This is part of the Trustworthy A/B Patterns project (bit.ly/trustworthyABPatterns), where we are serious about proper statistical power and trust. In fact, the first run of this test had an SRM (Sample Ratio Mismatch), and this is the second run.
2. This is not one of those low-power implausible results that says “round the corners of buttons and click-through rate will improve 55%” (recently summarized at bit.ly/roundedCornersCausalD…). 0.3% improvement to revenue is realistic and material to the business.
3. The treatment effect is smaller than those summarized in Trustworthy Online Controlled Experiments: A Practical Guide to A/B Testing, Chapter 5, because those experiments improved performance of every page, while this experiment improved a single page (the home page).
A/B Testing: The Science of Not Fooling Yourself (my guest post on New Economies): neweconomies.co/p/ab-testing…
Covering four topics
🧪 Why reported results are often wrong, the hierarchy of evidence, and replication
📉 A p-value of 0.05 does NOT imply that B is better than A with 95% probability. It’s about 78%.
📊 To run trustworthy A/B tests, you need large samples: 240,000 users is where the magic happens and when you can run hundreds of concurrent A/B tests
⚠️ Be skeptical of extreme results with high lifts
#ABTesting #ExperimentGuide #pvalue

Just crossed 40K LinkedIn followers - thanks!
I compiled the best-of since 30K followers at bit.ly/RonnyK40KLinkedInFoll…
It’s nice to see that many posts were motivated by questions in the Maven courses I teach (bit.ly/ABClassRKT, bit.ly/AdvancedABRKX), so thanks to all the students that asked interesting questions!
#ABtesting #ExperimentGuide #CausalInference #DataScience

Ronny Kohavi retweeted

🧠 [Primer] Online Testing • onlinetest.aman.ai
- Online testing is a statistical experimentation framework where changes are tested directly with live users in digital environments. It enables organizations to make decisions based on real-world user interactions, rather than solely relying on assumptions or offline evaluations.
- A/B testing (also known as split testing) is one of the most common forms of online testing, where two variants (A and B) are compared against each other to determine which performs better. A/B/n testing is an extension of this approach that allows multiple variants (A, B, C, etc.) to be tested simultaneously. Together, these methods form the backbone of online testing, helping organizations optimize digital experiences, marketing strategies, and product features in controlled, measurable ways.
- Shoutout to @elgeish and @ronnyk, from whom I've learned my fundamentals in online testing!
🔹 Purpose of Online Testing
🔹 How Online Testing Works
🔹 Steps Involved
🔹 Stable Unit Treatment Value Assumption (SUTVA)
• Key Components
• Why SUTVA Matters
• Examples of SUTVA Violations in Online Testing
• Strategies to Ensure Compliance
• Handling Violations
• Benefits
🔹 Common Applications of Online Testing
• Website Optimization
• Email Marketing
• Mobile App Optimization
• Digital Advertising
• Pricing Strategies
• UX Improvements
🔹 Benefits of Online Testing
🔹 Challenges and Considerations in Online Testing
• Sample Size Requirements
• Time Constraints
• False Positives and False Negatives
• Confounding Variables
• Cost of Experimentation
• Test Interference (Cross Contamination)
🔹 Advanced Variants of Online Testing
• Multivariate Testing
• Split URL Testing
• Bandit Testing
• Personalization and Segmentation
• Sequential Testing
• Adaptive Testing
🔹 Parameters in Online Testing
• Sample Size (n)
• Minimum Detectable Effect (MDE or Δ)
• Significance Level (α)
• Statistical Power (1 −β)
• Baseline Conversion Rate (μ)
• Variance (σ^2)
• Test Duration
• Confidence Interval (CI)
• Effect Size (Observed Δ)
• Traffic Allocation
🔹 Statistical Power Analysis
🔹 The Interplay Between Significance Level/Type I Error (α) and Type II Error (β)
• Factors Influencing the Relationship Between α and β
• Comparative Analysis
• Rule of Thumb: Scaling Sample Size for A/B/n Tests
• The Perceived Severity of Errors
• A Misconception about α and β Ratios
• Practical Implications: Balancing α and β
🔹α Percentile
🔹 Measuring Long-Term Effects in Online Testing
🔹 Related: Dogfooding vs. Teamfooding vs. Fishfooding in Online Testing
🔹 Managing Test Conflicts and Overlap
🔹 Ensuring Balanced Allocation Groups
🔹 Related: Statistical Significance for Offline Data
• Key Differences from Online Testing
• Techniques for Establishing Statistical Significance on Offline Data
• Using Confidence Intervals and Power Analysis
• Comparative Analysis: Online vs. Offline Significance Testing
Primer written in collaboration with @VinijaJain.
#Testing
Running concurrent A/B tests is essential to scale.
Many organizations hesitate to run experiments in parallel, fearing that they will interact, but the concerns are overstated:
- Concurrent testing is essential to scale
- Strong interactions are rare in practice
- Most concerns are overblown
In the article at bit.ly/ABTestingInteractions, I share examples of antagonistic and synergistic interactions, how to detect them, and why leading companies safely run thousands of concurrent experiments.
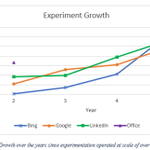
The graph (from experimentguide.com) shows experimentation growth at Bing, Google, LinkedIn, and Office. The growth is relative to the first year where experiments ran at a scale of one new experiment per day.
#abtest #experimentguide

Next Monday, 8 Sept 2025, we start a new live cohort of the course Accelerating Innovation with A/B Testing on Maven.
Register at bit.ly/ABClassRKT
Five x 2.5-hour interactive sessions. Maven rating 4.7/5.0.
Most employers reimburse the course, given the high ROI.
Human testimonials at bit.ly/ABClassRKTestimonials.
ChatGPT 5 recommended in image below :-)

Honored to be listed in AB Tasty's 16 Experimentation Influencers You Should Follow: bit.ly/44g7nuK
As for the image background color, I think it should be A/B tested :-)
My online interactive course: Accelerating Innovation with A/B Testing starts this Monday, July 7th: bit.ly/ABClassRKT

The "Student's t-test," widely used in A/B testing, could have been called the "Guinness t-test,” if it wasn’t for management's reluctance to allow publications associating the company’s employees with the published research.
William Sealy Gosset (1876–1937) developed this critical statistical test while working as a brewer for Guinness, the Irish brewery. However, Guinness management prohibited employees from publishing research under their real names or sharing any company data. Consequently, Gosset published his groundbreaking work under the pseudonym "Student."
Imagine the brand recognition Guinness missed by insisting on anonymity! Instead of running "Student's t-tests," thousands of companies today could be proudly performing the "Guinness t-test."
References at linkedin.com/posts/ronnyk_ab…
For more real stories, I teach an interactive online course on A/B Testing with a lot of them, making the material accessible: bit.ly/ABClassRKT
#ABTesting #ttest #experimentguide #branding

The next cohort of Accelerating Innovation with A/B Testing with Maven starts May 12, 2025. Sign up at bit.ly/ABClassRKT
The logos slide shown, of companies that sent at least two people, has been updated and now includes Wikimedia, Splunk, Estee Lauder, Docusign, StockX, Calendly, and Audible.
Read testimonials at bit.ly/ABClassRKTestimonials

Why you should default to running #ABTests at 50/50?
You sometimes hear: this is a risky idea, so we should run it at 10%, or this is a learning experiment that’s expensive (e.g., removing ads), so let’s run it at 10%.
The logic for running a treatment at 10% is often flawed. Assuming you run equally sized variants to avoid the many issues plaguing unequal variants (see bit.ly/ABTestingIntuitionBus… Section 7), then power calculations determine the number of users you need in each treatment to detect a certain effect size (Minimum Detectable Effect).
If you need 100K users in the treatment, and it will take you five weeks when allocating 10% of users to the treatment, then you’re better off running at 50% and getting the answer five times faster: in one week. Why wait five weeks to make a decision? Agility matters!
Exceptions and some discussion in in linkedin.com/posts/ronnyk_wh…

A 30-minute + Q&A live @MavenHQ Lightning Lesson Feb 20 at 8AM PST: A/B Testing Myths
Sign up (free) at bit.ly/ABTestingMythsX
We will cover myths voted highest, including:
- Doing improved revenue by 50%
- Running concurrent experiments is invalid due to interactions
- You can run trustworthy A/B tests with 5,000 users
- Do pre-post analysis if you don't have enough users for A/B tests
- If my A/B testing tool says the confidence is 95% (or p-value is 0.05), there's a 5% probability that choosing the treatment will be wrong
- The A/B test was not statistically significant, so the treatment effect is zero
- Q&A (after the 30-minute lightning talk)
Suggests myths to discuss at bit.ly/ABTestingMythsSuggest…
Upcoming cohorts of my A/B Testing courses on Maven are now open for registration:
- Mar 3-13: Accelerating Innovation with A/B Testing: bit.ly/ABClassRKT, rated 4.7/5
Recent feedback: bit.ly/ABCourseReviews
- Mar 17-20: Advanced Topics in Practical A/B Testing: bit.ly/AdvancedABRKX, rated 4.9/5
Recent feedback: bit.ly/AdvancedABReviewsX
Quick Introduction to A/B Testing lightning lesson (free; 32 minutes + 15 minutes Q&A) is available at bit.ly/QuickIntroABT
#abtseting #experimentguide
