
AI @ AMD
San Francisco, CA
Joined June 2009
- Tweets100
- Following300
- Followers794
- Likes316




Ramine Roane retweeted

🚀 @AMD MI355X just showed competitive performance to NVIDIA B300 on @Kimi_Moonshot K3 serving!
8× MI355X delivers 24.4% more throughput than HGX B300 (7,567 vs 6,083 tok/s/GPU) at 50 tok/s/user on @SemiAnalysis_ AgentX agentic coding benchmark, and 87.4% more tokens per dollar.
We cover the vLLM optimizations, AMD kernels, and hardware details that closed the gap, plus patterns for spotting bottlenecks so you can get more out of vLLM on your own GPUs.
Thanks @AMD @embeddedLLM @SemiAnalysis_
Full writeup: 🔗 vllm.ai/blog/2026-10-16-kimi…
Ramine Roane retweeted

ALERT🚨: AMD JUST LANDED SUPPORT FOR MEGAKERNEL DECODE IN UPSTREAM VLLM WELL BEFORE NVIDIA. This marks one of the first times that a major vLLM feature is only supported on ROCm and not on CUDA yet.
MegaKernels is a technique that is massively important for high-interactivity decoding by reducing the # of kernel launches by 10x.
This marks an❗️important milestone❗️for ROCm vLLM to land major ROCm-exclusive features. CUDA vLLM doesn't even have draft PRs for upstream vLLM megakernel support yet.

Ramine Roane retweeted

Decision 3.0 hype is real! it is the top performer in my little apple-harvesting test. It can actually play: read the scene, pick its own moves and collect apples without a pathfinding controller.
Input: a screenshot of its surroundings, game stats and a short memory of its last four moves. It chooses up/down/left/right each turn.
This run: 7 apples in 38 moves, zero damage 🔥

Introducing Decision 3.0: towards open multimodal foundation decision models ⚡
Open and state-of-the-art from 0.6B to 27B: #1 on both Jev Decision Index boards in our evaluation, on a new Pareto frontier.
HF collection 🤗: huggingface.co/collections/v…
#OpenSource #Jev #LLM
Ramine Roane retweeted

Introducing Decision 3.0: towards open multimodal foundation decision models ⚡
Open and state-of-the-art from 0.6B to 27B: #1 on both Jev Decision Index boards in our evaluation, on a new Pareto frontier.
HF collection 🤗: huggingface.co/collections/v…
#OpenSource #Jev #LLM


Ramine Roane retweeted
Ever since NVIDIA acquired SLURM/SchedMD, their support for non-NVIDIA chips has gotten worse, such that AMD created their own popular competitor called "spur" that is way better than SLURM in many ways.
Remember, NVIDIA claimed to keep SLURM hardware neutral when they acquired SchedMD, but so far that has not happened. Will the same thing happen to @huggingface after NVIDIA acquired them?
We shall see... we love Hugging Face and hope we are wrong, but NVIDIA historically has not been hardware neutral at all.

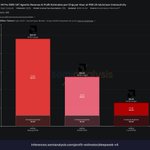
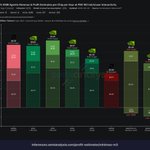
AMD MI355X posts the best margin on every model in SemiAnalysis InferenceX agentic profit estimates:
Kimi K3: 45.7% vs 43.8% (GB300)
GLM 5.3: 63.4% vs 63.2% (GB200)
MiniMax M3: 51.5% vs 48.4% (B300)
DeepSeek V4 Pro: 87.9% (no green data)
inferencex.semianalysis.com


#1 company contributing code to @vllm_project right now?
@AMD: 502 commits to core vLLM in 90 days. 13% of all org contributions, almost 4x Nvidia.
Also grateful to Red Hat, IBM, Embedded LLM & Inferact for building it with us.
Open source wins when hardware has a choice.


Ramine Roane retweeted

Look who showed up as another AMD Helios system enters the wild! 👋 @OpenAI
Last week, Vamsi Boppana and @udayruddarraju joined the team for a lab tour as we continue pushing the frontier of AI infrastructure, together.

2 ways to win on OpenRouter, serving GLM5.3/MI355X:
1. Speed: TileRT hits 469 tps/user on AgentX, ~45% higher interactivity v. GB300/FP4: amd.com/en/developer/resourc…
2. Profits: $11.18/GPU/hr at 67 tps (SemiAnalysis AgentX, 60% utilization) => $11.18*24*265*8 = $560k profit/node/year


Ramine Roane retweeted
MI355X IS UP TO 1.7X BETTER 💰️PERF PER DOLLAR 💰️THAN DGX B300. The AMD Mainland China UMBP team co-designed, in collaboration with Alibaba & the @sgl_project community, a new feature in SGLang that removes the duplicated KVCache contained between local L2 DRAM & distributed L3 DRAM, allowing for up to 2x more KVCache to be stored in DRAM. This feature is called UnifiedRadixCache external cache.
But importantly, this marks the trend of AMD increasingly being first-class co-designed for new features in widely used top production engines like SGLang.

Ramine Roane retweeted
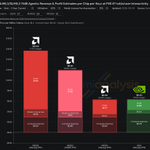
AMD ALERT🚨🚨: On Kimi K3 2.8T, AMD has even better profit margins per gigawatt compared to B300, GB200 NVL72, and B200. This is due to AMD's lower TCO and better performance, leading to better profit margins of 53.6% on Mi355X compared to 44.3% on GB200 NVL72. This is from our open-source Agentic Inference benchmark, AgentX.
Shoutout to @roaner & @EmadBarsoumPi 10x engineers for optimizing this 2.8T model!

Ramine Roane retweeted
On total tokens per $ TCO, a new AMD MI355x submission beats B300 at lower interactivity ranges on AgentX. Shoutout to vLLM, AMD, and LMCache engineers.

Ramine Roane retweeted

Kimi K3 running on AMD MI350X with SGLang. Amazing work to @AMD @sgl_project @Kimi_Moonshot this worked great out of the box!

Ramine Roane retweeted
With Kimi K3 Day-0 on vLLM: Open Frontier Intelligence for Everyone 🚀
At 2.8 trillion parameters, Moonshot AI's Kimi K3 is one of the most powerful open-weight models ever released. Starting today, you can serve it on vLLM the moment the weights are public.
What K3 brings:
🧠 2.8T-parameter Mixture-of-Experts (16 of 896 experts active per token)
📚 1M-token context window
🛠️ Native multimodal understanding, including vision
⚡ Kimi Delta Attention: a hybrid of linear and full attention that makes million-token context affordable
Huge thank you to @Kimi_Moonshot AI for the model release and partnership, @inferact for leading the vLLM optimizations, and to our partners at @nvidia, @AMD, and the broader vLLM community.
1/6

Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: huggingface.co/moonshotai/Ki…
Tech report: github.com/MoonshotAI/Kimi-K…
Tech blog: kimi.com/blog/kimi-k3

Ramine Roane retweeted

Agent workloads bring long contexts, bursty traffic, and frequent tool calls, creating new demands for AI serving.
Together with @AMD , we rebuilt the stack for Kimi K2.6 on AMD Instinct™ MI355X, with scheduler-aware multi-tier KV caching.
Up to 3.2× smaller p99 TTFT and 7.7% higher total-token throughput, with no accuracy tax.
Happy to see more Kimi running on AMD chips!
Tech blog: amd.com/en/developer/resourc…
