
PhD Student at Ommer Lab (Stable Diffusion) Working on video analysis and world understanding...
Munich
Joined July 2024
- Tweets81
- Following452
- Followers251
- Likes839





Nick Stracke ✈️ CoRL 26 retweeted

Directly predict the distribution over possible futures in one forward pass.
To find out how, come by our poster at #ECCV in #Malmö today.
Poster session 3 - Poster 101. See you at 10:30 am!

Nick Stracke ✈️ CoRL 26 retweeted
People often think of prediction as choosing a likely outcome. But that’s not how the world works!
Given partial information, the future is a distribution of possibilities. And more knowledge collapses the distribution.
We built a representation that models exactly that 🧵
Nick Stracke ✈️ CoRL 26 retweeted

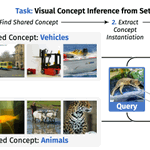
Most representation learning methods produce generic embeddings that try to preserve everything in an image.
We introduce VICIS: a way to use example sets to define a tailored embedding space for what matters.
This is useful whenever the desired visual signal is easier to show than to describe.
Code & weights available now 🧵👇

Nick Stracke ✈️ CoRL 26 retweeted

datasets .bot now supports filtering by dataset size!
There are 10 datasets with 1,000+ hours of data. Happy training 🏋🏽
shoutout @rmsnorm for the feature request

@vai_viswanathan, love datasets.bot/! Could you add an option to filter by dataset size, e.g., in hours of available video material? Thanks!

Nick Stracke ✈️ CoRL 26 retweeted

Now accepted to #ECCV2026 🎉

Nick Stracke ✈️ CoRL 26 retweeted
Another crazy CVPR 2026 world model result.
“Envisioning the Future” forecasts where points in a scene will move, step by step, from a single image. No dense video needed.
- 3,000x faster than video models, 10x fewer parameters, and 5x more accurate under a fixed compute budget.
- An autoregressive diffusion model rolls sparse point trajectories forward through short, predictable steps, modeling uncertainty as it grows.
- Why it matters: Rollouts get cheap enough to simulate thousands of futures and plan over them, hitting 78% billiard planning accuracy vs 16% for the best dense video baseline.

Nick Stracke ✈️ CoRL 26 retweeted

second runner up is a super cool paper from Björn Ommer’s group at LMU.
they first encode point trajectories into a latent using a VAE. then they learn to denoise future trajectories conditioned on past.
they do planning experiments on Libero by training a small decoder to convert denoised latents to robot action.
I joked that this is latent stable diffusion all over again by Björn but this time with point trajectories 😄

Nick Stracke ✈️ CoRL 26 retweeted

ZipMo hands a robot its plan by daydreaming how the scene should move.
No pixels, no rendering, no hour-long video to sit through.
10,000x faster than a top video model!
Just a fast read on where everything's headed, and the robot runs with it.
Give it a start frame and a goal in plain language.
It predicts how the arm and the objects around it should move to get there.
A thin policy head reads that motion plan and turns it into the next arm command.
The head never sees the task, only the predicted motion.
So all the reasoning lives in the motion model.
The head is pure inverse dynamics, motion in, action out.
On the LIBERO benchmark it replans on every new frame, and it beats the trajectory-based policy methods it lines up against: ATM, Tra-MoE, Amplify.
It pulls this off by never touching pixels.
It learns a compact motion space from tracked trajectories, then generates motion straight inside that space.
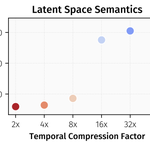
And stranger still, compressing that space 64x makes the motion sharper, not worse.
Congrats to the team, lovely work. @rmsnorm, @KoljaBauer, @StefanABaumann
Nick Stracke ✈️ CoRL 26 retweeted
You don't need a video model to predict motion. We'll talk about how to be 3000× faster at CVPR Poster 634, this morning at 10:45. Drop by and check it out!
You don't imagine the future by mentally rendering a movie. You trace how things move -- abstractly, sparsely, step by step.
We built a model that does exactly this. It predicts motion, not pixels -- and it's 3,000× faster than video world models.
Myriad, accepted at @CVPR 2026

Nick Stracke ✈️ CoRL 26 retweeted

⚠️ Standard first stages are not sufficient for safety-critical applications!
The most extreme weather events are often the hardest to decode.
One latent → many plausible reconstructions
Deterministic decoders hide that uncertainty.
Meet FREUD 🧵👇
Nick Stracke ✈️ CoRL 26 retweeted

Cool stuff
Nick Stracke ✈️ CoRL 26 retweeted
Stop predicting motion step-by-step. Model the whole motion in a compact representation for efficient planning.
📄 Paper: arxiv.org/abs/2604.11737
💻 Models: compvis.github.io/long-term-…
Joint work with @KoljaBauer, @StefanABaumann, @itsbautistam, Josh Susskind, and Björn Ommer.

Nick Stracke ✈️ CoRL 26 retweeted

Amazing work led by @rmsnorm @KoljaBauer and our collaborators at LMU, to be presented at @CVPR! Personally, I find this question of "what's the right level of abstraction for planning in physical space?" to be very intriguing. Pixels over time are very low SNR (ie. the argument behind JEPA) but motion/trajectories carries a lot on information while being extremely compressible. I believe there's a lot more to uncover from this direction. Very glad to be part of this one!
Nick Stracke ✈️ CoRL 26 retweeted

A massive step forward for AI video!
Nick Stracke ✈️ CoRL 26 retweeted

I have been saying
Nick Stracke ✈️ CoRL 26 retweeted
1️⃣xitter.cf/neerjathakkar/status/2…
Also, shoutout to two other recent works that explore how to use point tracks for world modeling.
👇...

What’s the right representation for a world model? 3D, pixels, or something else?
Excited to release our new paper “Forecasting Motion in the Wild” where we propose point tracks as tokens for generating complex non-rigid motion and behavior
From @GoogleDeepmind @Berkeley_AI @TTIC_Connect
Nick Stracke ✈️ CoRL 26 retweeted
Do we really need pixel generation to model motion? 🤔
We show how directly representing motion in a compact space enables efficient, scalable planning.
10,000× faster than video models, enabling planning and reasoning in open-world and robotics settings.
Check it out ⬇️
Nick Stracke ✈️ CoRL 26 retweeted
You don't imagine the future by mentally rendering a movie. You trace how things move -- abstractly, sparsely, step by step.
We built a model that does exactly this. It predicts motion, not pixels -- and it's 3,000× faster than video world models.
Myriad, accepted at @CVPR 2026

