





rishi retweeted

Traditional LLMs write one token at a time. Diffusion models don't.
At the London PyTorch Meetup I gave an intro to text diffusion and how DiffusionGemma gets ~4x faster text generation. If you know LLMs but diffusion is a black box, this one's for you!
youtu.be/3n5RN7i8h2Y

i guess the story that everyone in os compares to everyone in os once you are above 200B param count still holds true
rishi retweeted

As if we needed any more evidence that 2026 is the year of continuous diffusion for language🤭
(I recently wrote a blog post about my thoughts on this topic, in case you missed it: sander.ai/2026/08/24/continu…)


💫 Large Language Continuous Diffusion Models
Presenting Sigma, the first large-scale (3B/8B) continuous diffusion LM (dLM) trained with likelihood.
📈 Comparable with discrete dLMs and AR on math and coding
🎛️ Enables meaningful study of inference-time interventions
Jointly led with Wei Guo (@WeiGuo01), Jean-Marie Lemercier (@jm_lemercier), Simon Welker (@_cobalamin)
Team: @YongganFu @mmkamani7 Sajad Norouzi @julberner @tomasgeffner @karsten_kreis @YongxinChen1 @MoleiTaoMath @jwthickstun @PavloMolchanov Ante Jukic @ArashVahdat @MardaniMorteza
On first pass this is amazing progress for continuous diffusion lms
💫 Large Language Continuous Diffusion Models
Presenting Sigma, the first large-scale (3B/8B) continuous diffusion LM (dLM) trained with likelihood.
📈 Comparable with discrete dLMs and AR on math and coding
🎛️ Enables meaningful study of inference-time interventions
Jointly led with Wei Guo (@WeiGuo01), Jean-Marie Lemercier (@jm_lemercier), Simon Welker (@_cobalamin)
Team: @YongganFu @mmkamani7 Sajad Norouzi @julberner @tomasgeffner @karsten_kreis @YongxinChen1 @MoleiTaoMath @jwthickstun @PavloMolchanov Ante Jukic @ArashVahdat @MardaniMorteza
rishi retweeted

🔥Welcome 🔺Simplex Diffusion Models🔻!
Standard discrete diffusion models suffer from "information collapse" because they discard uncertainty at intermediate steps by sampling categorical tokens. (1/5)

rishi retweeted

Excited to share my new result on unbounded Holevo additivity gaps, a long-sought open question since Hastings’ seminal discovery on addivitiy violation.
We identify a sequence of channels where Holevo $\chi$ diminishes while classical capacity diverges. Surprisingly, the construction was hiding in plain sight: it simply takes a fresh look at earlier work by Benoît Collins et al. bridging random channel violations and free probability theory (, which is also a subject of my favorites, and more works coming soon, stay tuned!).
arxiv.org/abs/2609.18222

-the second instance of extremely scaled engram
-enc dec in this fashion has really good disagg properties, it seems as though they went in on optimizing for prefill efficiency with this arch, not sure if it will actually outperform not doing this type of enc dec
-this is one of the most impressive archs
I will have to think more on how much of this is needed under modern racks that we have available

Deepseek V4.1 Flash 552B total, 8/16B active with a new arch trained on 45T tokens, there are different active parameters for input/output tokens with the encoder/decoder arch, engram, new sparse attention, new mHC, native vision
very high benchmarks (beating K3), insane efficiency, and as always amazing tech report
this is probably the most novel arch i've seen in a while, pretty insane

rishi retweeted

This month, I reverse-engineered Jane Street's ASIC puzzle from its chip layout. I reconstructed the circuit, solved the hidden 11 x 11 Star Battle, recovered `(* TWO STARS *)` and found @JaneStreetGroup's spiral logo drawn into the metal

Additionally the throughput chart on the left of the original paper is incredibly misleading. The arbitrary choice of measuring throughput on a single h200 with much larger models in competition is unfair.
Additionally the toks/nfe are quite low, likely due to lack of training tokens in the diffusion conversion phase.


rishi retweeted

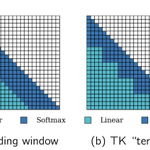
How can your abstract ignore years of research? It has been repeatedly proven that SWA is much worse than linear attention when trained from scratch. See app. A of arxiv.org/pdf/2509.24552 or any other recent linear attention paper's SWA baseline.
Is this just an honest mistake?
rishi retweeted

We're releasing Terminal-Bench-Science: a benchmark for evaluating AI agents on research workflows across scientific domains.
An ongoing Stanford-led community effort, built by the team behind Terminal-Bench together with scientific domain experts at research institutions worldwide. v0.1 has 70 tasks. Claude Opus 5 solves only ~30%.
1/n 👇
