CS PhD @UCBerkeley | Ex-Deepmind, FAIR | Research area: Efficient LLM reasoning, scaling RL

Berkeley, CA
Joined May 2019
Very excited about this line of research of fast-slow learning, 1) potential to solve a lot of issues with current RL (eg. entropy collapse, sparse rewards) 2) an intuitive way of incorporating rich feedback with RL 3) provides a way to transfer knowledge of text-only based learning into the model 4) a great candidate for model-harness co-evolution, seeing a lot discussion on X lately about future models developing their own harness. 5) most importantly, can imagine these kinds of algorithms to be more suitable candidates for discovery that requires both extreme exploration but at the same time improving the underlying model capabilities. and much more ...
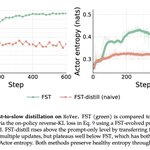
Can LLMs adapt continually without losing base skills? Fast-Slow Training (FST) pairs "slow" weights with "fast" context. FST vs. RL: • 3x more sample-efficient • Higher performance ceiling • Less KL drift (better plasticity) • Continual learning: succeeds where RL stalls
3
26
2
179
30,449
🤖 How well do agents learn from experience? We study agents that amortize experience into reusable artifacts and introduce Agent Plasticity to measure how efficiently they improve on held-out environments. Top performer ≠ most efficient learner.
17
52
16
258
34,397
Rishabh Tiwari retweeted
looking to nerdsnipe some of the best scientists into joining me as operators to make a lasting impact on Gemini's scientific capabilities. know someone? > scientist (life sciences / physical sciences / math) > wants to be an operator at a frontier ai lab > like to be in the weeds of data and evals > agi-pilled > idc if you're experienced or a recent grad (bs/ms/phd) : passion + drive >>> > human written short emails/messages, apply link below
8
16
215
17,703
Rishabh Tiwari retweeted
Happy to share that Interleaved Head Attention (IHA) has been accepted at #NeurIPS2026! 🎉 In standard multi-head attention, heads remain isolated during attention. As a result, combining multiple relationships often has to happen across successive layers. 🧠🔗 IHA lets heads communicate before attention by constructing learned mixtures of their queries, keys, and values, creating richer within-layer interactions while preserving the standard attention operation. ⚙️✨ Across long-context retrieval and mathematical reasoning, IHA consistently improves over standard attention. 🚀 Huge thanks to my co-lead author @dvsaisurya and our amazing coauthors @rach_it_, @rish2k1, @Devvrit_Khatri, @brandfonbrener, and brilliant mentors @pliang279, Inderjit Dhillon, and Manzil Zaheer! 🎥 Quick overview below 📄 Paper: arxiv.org/abs/2602.21371
🧵 [1/14]: Talking-Heads Attention by @NoamShazeer et al. showed something interesting: maybe attention heads shouldn’t be fully isolated. 🧠 That got us thinking: If communication across heads matters, what is the right way for heads to communicate, especially from a one-layer reasoning perspective? 🔗⚙️ That question led us to Interleaved Head Attention (IHA) ✨ 📄 Paper link: arxiv.org/pdf/2602.21371
5
27
2
133
21,758
Rishabh Tiwari retweeted
I got my @Muse to generate a full explainer video with deep research. I think this is an emerging way for thoughtful content consumption. It right now has to work hours to come up with this, and these code generated videos need a place in the mid-training stack! @Musecases
2
1
16
772
Rishabh Tiwari retweeted
Terminal-Bench meetup tonight *with* swag. Register if you haven’t already! Benchmarks, RL environments, new features, and state of the union luma.com/tbench
17
10
3
116
12,058
Rishabh Tiwari retweeted
We pretrained a 2.3B MoE (360M active) Hybrid Mamba-2 that lands within a few points of Llama-3.2-3B using <1% of its pretraining FLOPs. No dedicated cluster. The run hopped between H100s, A100s, V100s (yes, V100s) and TPU v5p/v6e on a single codebase. Meet Rigel 🧵
23
80
18
634
85,927
Rishabh Tiwari retweeted
nice work from the APEX-Agents team great idea to use GEPA for optimizing judges (agentic verifiers need benchmarks, too!) also... now on the harbor hub!
Today we're introducing APEX-Agents 1.1. As AI models advance, so do their methods to solve APEX-Agents tasks. We’re updating our benchmark with task specifications, tooling, and environments to maintain leaderboard accuracy. Most notably, APEX-Agents 1.1 no longer rewards noncommittal answers. This ensures that our tasks and grading align with how professionals operate. Claude Fable 5.1 remains on top of the leaderboard with 68.6% on Pass@1, though rankings have shifted throughout the rest of the board. Updated rankings for Pass@1: Claude Fable 5.1: 68.6% Gemini 3.7 Flash: 67.8% Claude Opus 5: 65.8% Grok 4.6: 65.3% GPT-6 Astra: 64.7% Read the announcement blog: mercor.com/blog/introducing-…
3
8
1
44
10,131
Rishabh Tiwari retweeted
i can’t stop checking in on this. the marin team is training the largest fully open model ever. 535B params (23B active), 18T tokens. nobody has been this transparent in a hero run before. beyond the weights, the data, logs, and decisions are all open. you can, and should, follow the run live, it’s ~15% through so far! mtracker.oa.dev/hero-run-535…
Marin 535B-A23B is 13% through training. This hero run would not be possible without the generous support of the Jen-Hsun and Lori Huang Foundation, which provided the funding for the compute (Coreweave). Thanks @JensenHuang for supporting open models!
9
57
2
605
62,144
Rishabh Tiwari retweeted
Open-source video generation is now faster than playback without compromising quality. Introducing Video Delta Net (VDN): hybrid attention for live text-to-video with near-lossless quality. VDN accelerates Minimax-H3 by 75 - 90 x, generating 14 seconds of 768p video in 11 seconds on 8× NVIDIA B200 GPUs. Checkpoints + training/inference code + Technical Blog ⬇️ (1/6)
70
174
54
1,228
443,337
This looks super cool, a mix of inference-time compute scaling + open-endedness. Will be exciting to see what kinds of behaviors and projects it decides to work on with me.
Introducing Headlong, an open source microharness for persistent agents: self-guided agents that think continuously. Most agent harnesses are reactive: you send a task, the agent completes it, and then it sits frozen until the next request. Cron jobs and heartbeats wake it up to run a checklist and put it back to sleep. A Headlong agent is never asleep. It keeps generating thoughts about whatever it decides is interesting, in a self-guided loop inspired by human inner monologue. Your message doesn't start a session. It's one more observation that lands in the agent's thought stream, and the agent decides if and when to reply. Headlong is built on the idea of persistent agency: continuous inner thought generation between external interactions. The agent sets its own interests and priorities, comes up with its own projects, and sometimes pings you unprompted with progress. To keep our prototype as simple and small as possible, we implemented Headlong as a microharness: a complete agent harness in under 10K lines of Bash, organized as a handful of small executables. It includes a loop that generates the next thought, shellm (a recursive language model written in Bash), a trajectory stored as a DAG of jsonl files, and context as a projection of that trajectory. We've been running one Headlong agent internally at Laude for several weeks. The whole team talks to it over Slack and Telegram, and every conversation lands in its single stream of thought. It works in its own fork of Headlong and we've pulled over 50 of its commits into main. One night, with nobody talking to it, it went back to check whether a recall process it had built was actually wired into its mind, found that it wasn't, diagnosed and fixed the bug, and verified the fix end to end. 48 minutes, no human asked for the fix or was in the loop at any point. Every step is a timestamped line in its log. Things broke too, and we wrote those up. Background thinking costs us $1 to $2 an hour, our agent stopped its own service three times by accident, and self-delegation died on day one. Details in the post. One line installs everything and starts an agent. Use a dedicated sandbox and spend-capped API key; it runs real shell commands and thinks around the clock. Headlong is research software, be careful! curl -fsSL headlong.ai/install.sh | bash Launch post: laude.org/updates/headlong-a… Repo: github.com/laude-institute/h… Headlong is a @LaudeInstitute / MIT collaboration.
1
9
685
The GEPA team went through all feedback we received about prompt/harness optimization runs and used HCI principles to develop deep observability and steerability tools into GEPA/optimize_anything including re-architecting GEPA itself, allowing both you and your agents to know exactly what is going on in the run. The new interface allows you to understand what candidates are being proposed, which datapoints are useful and if any datapoints are misleading or failing repeatedly? With the built-in GEPA agent, you can now chat about the run, inject new candidates on the fly, as well as use @cursor_ai-style brushes to give very targeted feedback to various components like the candidates and evaluators, and see the changes immediately. We are very excited to iterate further on this, and invite you to please sign up for the user study to provide us feedback!
Spent hours digging into GEPA logs finding ways to fix your run? 👀 We have reimagined GEPA to be human-steerable. We built deep observability tools allowing agents to monitor, proactively surface, and fix issues in your run. We provide multiple levers for users to intervene and meaningfully affect the optimization trajectory! Early access signup in 🧵👇🏽
7
22
4
186
14,555
Rishabh Tiwari retweeted
Spent hours digging into GEPA logs finding ways to fix your run? 👀 We have reimagined GEPA to be human-steerable. We built deep observability tools allowing agents to monitor, proactively surface, and fix issues in your run. We provide multiple levers for users to intervene and meaningfully affect the optimization trajectory! Early access signup in 🧵👇🏽
2
13
2
82
19,059
Rishabh Tiwari retweeted
1/ We just made GEPA’s optimization loop much faster, along with improved generalization! Instead of proposing and evaluating one candidate at a time, each GEPA step now proposes a batch of candidates and evaluates them all concurrently. Parallel proposals significantly cut wall-clock time (3–4× faster) while, surprisingly, also generalizing better (up to +11 pts). 🧵
1
10
5
57
25,077
Rishabh Tiwari retweeted
announcing the NeurIPS 2026 workshop on *Transitioning from Pre-training to Post-training*!🍓 come bring your theory, empirics, & methods to enable better foundations, mechanics, & evaluation for LLM training! submit your work by 29th August!🗓️ pretrain2posttrain.github.io… 🧵
5
27
2
165
18,324
Rishabh Tiwari retweeted
Science should not be bottlenecked by access to frontier AI. Mirendil is building systems to bridge that gap - making AI R&D faster, autonomous, and easier to adapt to the hardest scientific problems. A lot more becomes possible when more people can build near the frontier :)
Today, I’m excited to formally announce @mirendil with my amazing co-founders Harsh Mehta, Shayan Salehian, and Tara Rezaei! We’re fortunate to work with @a16z and @kleinerperkins, who led our seed round of $200M, followed by a major investment from NVIDIA, among others. Mirendil exists to accelerate science and technology, and through them, to help solve humanity's most pressing problems. Self-accelerating AI R&D is the most direct path to delivering on AI's broader promise, which is why we believe the most important application of AI is AI itself. Get this loop right, and it compounds. It fundamentally changes the rate of progress itself across all domains. We believe this capability should be democratized. It should be used to power all scientific efforts trying to innovate at the frontier. There are far more important problems—and broader ones—than any single lab can take on, so more groups should be able to pursue them. This pulls concentration of power away from a few labs: businesses and science labs can own their AI and infrastructure, keep their margins, and control their own destiny instead of ceding it all to a single AI lab. We’re a small team with a singular focus. Our founding team consists of 20 researchers and engineers from frontier institutions including Anthropic, xAI, Google DeepMind, and OpenAI, united by a passion for science and a drive to build the technologies that move it faster. If you want to build the system that builds systems, join us! @HarshMeh1a, @shayan_, @tararezaeikh
11
8
1
123
12,899
Rishabh Tiwari retweeted
The teacher distribution matters a ton - just because we expect it to be "better" or "more knowledgeable" doesn't mean it's good to distill its distribution. We show the blindspots of vanilla context distillation, and how it can hurt rather than help.
1
4
18
3,587
Rishabh Tiwari retweeted
Nice summary of learnings on self-distillation in the run-up to our Learning Fast & Slow paper!
3
16
198
43,021
Rishabh Tiwari retweeted
We spent some time trying to better understand on-policy self-distillation. A few takeaways: - In distillation, the optimal teacher stays close to the student but puts more probability on high-reward trajectories - Self-distillation assumes a model conditioned on privileged context approximates this optimal teacher. Naively injecting env feedback instead teaches the student to hallucinate feedback it never received, and degrades reasoning, especially OOD - Evals are important: beyond ID val acc, track OOD performance and reasoning quality (hallucination, hedging etc.)
1
6
58
9,303