




Rid retweeted

🥉 3rd Place - Ansr
Ansr is an AI voice host that answers restaurant calls, takes orders and reservations, and converts missed calls into structured, real-time business for owners.
@ridcursion
Rid retweeted
New York 🇺🇸
Zero to Agent
Momentum builds.
As London wrapped, New York picked it up.
What started in one city is now moving at scale.
Introducing hivememory
Shared reasoning memory for multi-agent systems.
Agents write structured claims with evidence + provenance, query what others already know before making LLM calls, and catch contradictions automatically.
pip install hivememory
ridxm.github.io/hivememory/

for sure! shipped one I made over the weekend today.
Hivememory, shared reasoning memory for multi-agent systems. agents share structured findings, skip redundant research, and catch contradictions automatically
xitter.cf/ridcursion/status/2040…

I built hivememory, a shared reasoning memory layer for multi-agent systems
agents write structured claims with evidence + provenance, query what others already know before researching, and catch contradictions automatically
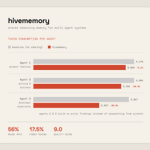
benchmark results with 3 parallel agents:
- 56% of queries served from memory
- 17.5% token reduction
- quality equal or better
- conflicts identified
project page: ridxm.github.io/hivememory/
repo: github.com/ridxm/hivememory
inspired by @karpathy's LLM knowledge base. single-agent works, this makes it multi-agent.
pip install hivememory
Rid retweeted
Day 3: building 30 AI Agents in 30 days ✧
i think we can all agree apartment hunting is very time consuming. looking at the neighborhood, reviews, commute times, and much more.
So today, I built an agent that takes an address and pulls everything together that I'd normally spend hours digging for.
#agentsystems #automation
Rid retweeted
day 5 of building 30 ai agents in 30 days!
competitive intelligence agent
you give it a startup idea, it finds your competitors, maps them visually, compares pricing/features, and tells you what to avoid.
watch the demo below :)
#BuildingInPublic #agent
claude-eyes is finally a native feature
xitter.cf/ridcursion/status/2013…


yeah mid-order corrections are tricky. the extraction layer picks up the final intent regardless, but handling it gracefully in the live conversation without restarting the whole order was def something i had to thoroughly test
i think the wildest finding here is how often a model tries to manipulate doesn't predict how often it succeeds. propensity ≠ efficacy
also manipulation was most effective in finance, least in health. health has ground truth that can be validated against, finance has speculation. so it's easier to get someone to make a bad investment than take a bad supplement
the domain matters more than model

thanks Matt! appreciate that. you're right, modifications are where it gets tested the most. the extraction layer handles them well actually, "vegan wrap, no onions, extra sauce" comes through clean because the LLM understands context and it's not just based on keywords. but the voice conversation side (making sure the AI confirms the modification back naturally) is the harder problem. have to work on that!