

Entrepreneur, Scientist. Likes: Semiconductor/VLSI, ML/AI/Data Sci+Eng, Healthtech.
Austin, TX
Joined July 2008
- Tweets1.3K
- Following301
- Followers122
- Likes167


Ravi Patel retweeted

Meet TYGER: a decision model for speech that opens the way to full-duplex voice agents.
It listens to the mic and your TTS at once, and every 80ms decides whether to speak, yield, or chime in with an “mm-hm”.
No need for VAD anymore.
Works with any LLM and TTS.
huggingface.co/nineninesix/t…


Ravi Patel retweeted

We are releasing Ultramarine 1 Flash, a frontier-class model built for knowledge work. It is open-source and achieves similar performance to Fable 5, while being 60x cheaper.
It was post-trained by a team of 5 for ~$300k all-in. Available on API now, with weights releasing in 2 weeks.
Ravi Patel retweeted

MUST WATCH: Brett McGurk, Biden's White House Middle East coordinator who negotiated hostage deals, lays out five important points about the hostage negotiations between Israel and Hamas.
0:00 The idea that Hamas was ready to release all the hostages right after October 7th is "complete bullshit." Hamas's core demand was every Palestinian prisoner and "we stay in power," and he has "no doubt" it planned to hold hostages for years.
1:31 The first deal collapsed when Hamas held back the young women and asked to "skip to the older men." Israel refused unanimously, because skipping them would have been "signing their death sentence."
3:30 Hamas "would sit on offers" and never accepted the deal Biden announced on May 31st, even with Netanyahu's yes, unanimous UN Security Council backing, and heavy prisoners (convicted murderers) on the table.
5:13 Biden told Netanyahu "I could cut you off," which McGurk opposed. The public pressure over Ramadan and Rafah "played back extremely negatively in the hostage talks," with Sinwar in Rafah watching.
7:05 After six hostages were murdered in a tunnel under Rafah, McGurk concluded: "We're not going to get a hostage deal until Yahya Sinwar is dead."
Source: Call Me Back - with Dan Senor


Ravi Patel retweeted

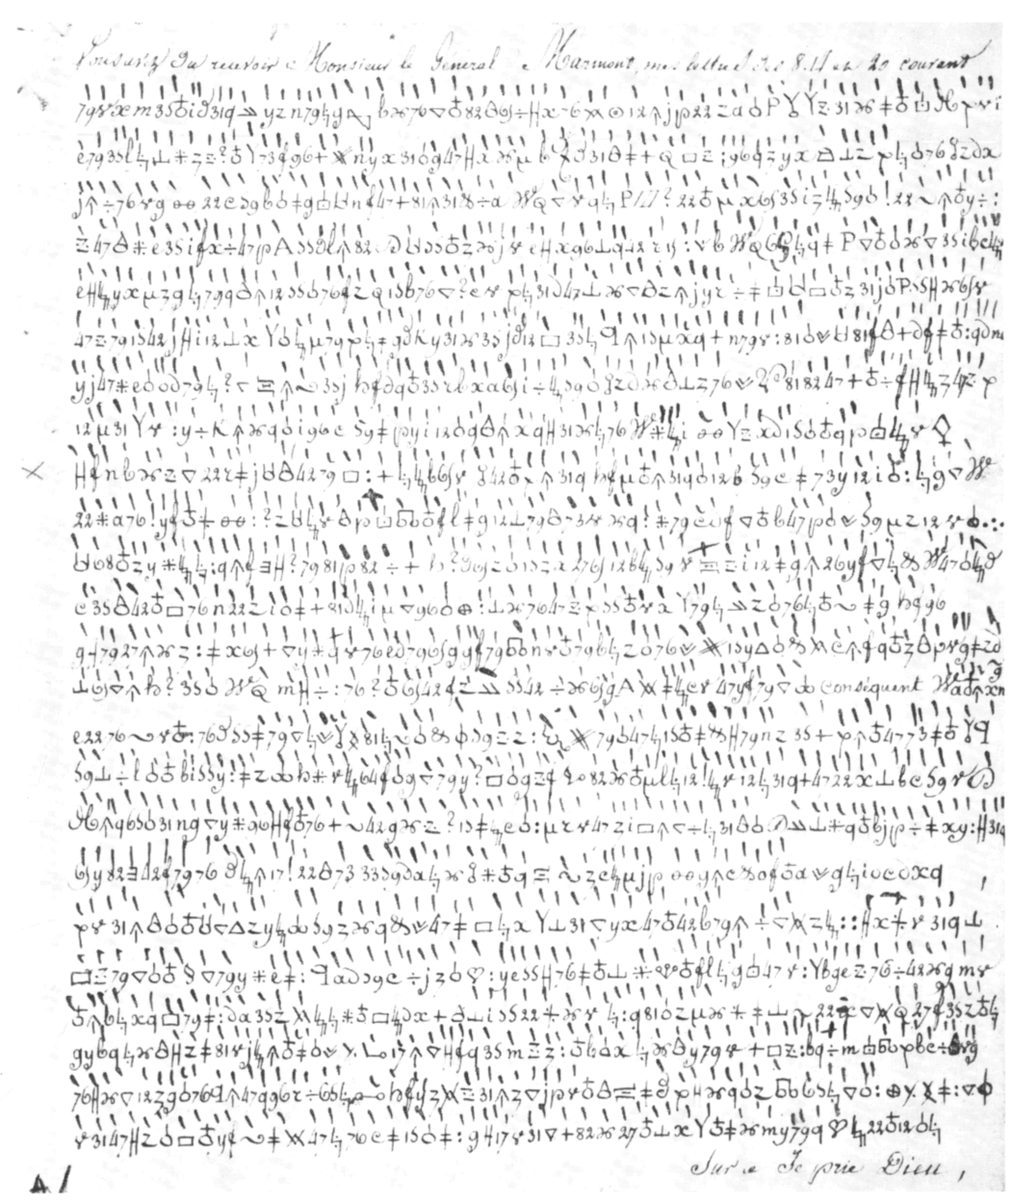
I used GPT-6 Astra to break an unsolved cipher to one of Napoleon's generals that had gone unread for 217 years.
What makes this impressive isn't actually the codebreaking, but that Astra completed the entire multi-modal workflow in ~6 hours from a single image and goal.
1/6🧵

Ravi Patel retweeted

Everything you want is on the other side of not giving a fuck, asking again, and taking another shot. Life gives you endless lottery tickets to try and you only need one win to change your life forever .
Ravi Patel retweeted
Nine times out of ten, solving for speed is the correct decision.
And the bigger the org, the more it will try and solve for “error free” and in so doing create the largest error of all - irrelevance.
Ravi Patel retweeted

Agree on full attention utilization, and that what we’re doing retains the qualities of engineering. One uber driver delivered me to an airport, and now two pilots are carrying a few hundred of us across a continent. 737 is a transportation amplifier, but requires a lot more rigor and checklists to use it right.

I think the "difficulty" of software engineering is essentially constant no matter what abstraction level you move to, because human cognition adapts to new tools until it can fully utilize itself.
Tools are only affordances, not a magic wand that makes work disappear.
Great software engineering was immensely challenging before. It is still immensely challenging now, despite very different workflows.
Ravi Patel retweeted

Hindu comedian hears Christians and Muslims talk about God and tries to add them to the list.
“What does He look like?”
“Does He have special powers?”
“How do you talk to Him if you can’t see Him?”
His attempt to make sense of monotheism is hilarious.

Ravi Patel retweeted

When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗
Ravi Patel retweeted

You can automatically turn your Jev queries into tiny task-specific classifiers that run 10-20x faster!
- Start with Jev, save the results
- Run npx jimothy train
- Get back a 15-45 MB model
- Run on the server or in the browser
- Fall back to Jev anytime
- Repeat
Demo: jimothy-r63s.vercel.app
GitHub: github.com/AndrewPrifer/jimo…
Ravi Patel retweeted

Another insane Jev use case!
Jev is making it dramatically cheaper to evaluate what actually happened inside an agent run.
And finally, someone open-sourced a self-improving memory layer that can put that signal to work across agent harnesses:
- Claude Code
- Codex
- Cursor
- OpenCode, and 20+ more
Beacon by @asymptotelabs continuously captures your agent history across harnesses and uses Jev to identify which runs are actually worth learning from.
It then turns the highest-signal workflows, corrections, and debugging patterns into reusable skills.
GitHub repo: github.com/Asymptote-Labs/ag…
(don’t forget to star it ⭐ )
Beacon preserves the complete session history. But preserving a run and learning from it are two different things.
Most coding-agent sessions contain routine exploration, failed commands, and fixes that only apply to one task. The trace can remain available for inspection without turning every detail into guidance for future agents.
Jev scores each run for evidence, reuse potential, and human correction signals. An application policy then decides whether to promote, review, or discard it.
The recording shows this in action.
Claude receives a coding task, modifies the implementation, and runs the tests. I then provide an edge-case correction, so Claude updates the code and adds regression coverage.
Beacon automatically captures the complete session. Jev evaluates whether the correction contains a reusable engineering lesson.
Once approved, that lesson becomes available to other coding agents working on the project.
Since it works across harnesses:
- Claude Code sessions can teach Codex.
- Cursor debugging can improve OpenCode.
So a problem solved by one agent should not need to be learned from scratch by another.
If you want to dive deeper into Jev, I also wrote a hands-on guide to building this Jev-style decision path with open models, entirely locally.
Read it below.

Ravi Patel retweeted

Impressive paper showing the impact of a good harness.
Improves Qwen3-8B from 41.2% to 91.8% on long-horizon robot tasks without any change to the model.
The gain comes from the harness.
GAVEL keeps an explicit graph world model holding object relations, action preconditions and effects, and probabilistic beliefs about where unobserved objects are.
Before the robot executes an LLM-generated action, the graph predicts what that action would do.
Violations get caught, and the ones whose fix follows directly from the world model get repaired without calling the model again.
Only errors that need semantic reasoning go back to the LLM.
On BEHAVIOR-1K across 500 multi-task instructions, success rises from 19.9% to 92.6%. Reasoning over the distribution of possible object locations also reorders the remaining subtasks and cuts travel distance about 5.4%.
Why does it matter?
Many long-horizon agent failures are state-tracking failures rather than reasoning failures, and a symbolic model sitting outside the LLM catches them cheaply.
Paper: academy.dair.ai/papers/gavel…
