

tech and investments @spacexai
100.100.100.100
Joined July 2020
- Tweets511
- Following178
- Followers108
- Likes518






Ai is going to kill consoles

PS5 is now 80% ported to PC. We might actually get GTA 6 on PC at launch week...

Readers added context they thought people might want to know
The 80% figure comes from the AnyPS5 project dashboard and reflects GPU shader instruction implementations (80.27%) and declared library functions (77.35%), not overall PS5 compatibility. The tool is in early development and only one 2D game is verified. github.com/boykopovar/Any…
My $NVDA DGX Spark cluster has appreciated in value.
The hardware hasn’t changed. The OSS community just keeps unlocking more of what it can do.
Software compounds. Never underestimate @JensenHuang.


All roads always lead to Kubernetes. The plebs use anything else

Most production inference services run on Kubernetes, where declarative configuration helps coordinate distributed services. Running one inference server in a Slurm job is easy; running a production-style topology across multiple containers and nodes is not.
NVIDIA’s open-source srt-slurm (github.com/NVIDIA/srt-slurm) provides a YAML-based orchestration layer for these deployments. It coordinates sbatch and srun, GPU placement, networking, readiness checks, and cleanup for systems involving prefill/decode disaggregation, multiple workers, Dynamo frontends, KV-cache-aware routers, and KV-cache offloading services.
It’s useful for quickly deploying representative inference systems for testing or benchmarking on GPU clusters that already run Slurm.
Great work to @0xishand and the rest of the @NVIDIAAI team on this!


raj singh retweeted

TSFlow is one of the coolest projects in the @Tailscale ecosystem
Love watching the bytes move across the network
Huge kudos to @rajsinghtech for building it 👏


Long $CRWV

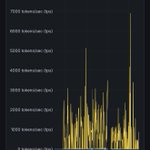
vLLM hit new peak bs=1 decode on Kimi-K3: 464 tok/s 🚀
Under a low-entropy reasoning workload, Kimi-K3 + DSpark on vLLM reaches 464 tok/s on batch size 1 with 4×4 GB300.
This benchmark is fully reproducible with public image: vllm/vllm-openai:kimi-k3 and @inferact's DSpark draft model linked in the thread.
1/3


Watch my agent trade on $HOOD
trades.rajsingh.info

The world is firing at all cylinders

This is a super exciting release - Claude Fable 5 is the same underlying model as Mythos but with added safeguards. The benchmarks are great and it's SOTA on everything by a margin but I'll add that *qualitatively* also, this is a major-version-bump-deserving step change forward (imo of the same order as Claude 4.5 was in November), peaking especially for long problem-solving sessions on very difficult problems. You can give it a lot more ambitious tasks than what you're used to, the model "gets it" and it will just go, and it's never felt this tempting to stop looking at the code at all (but don't do this in prod!). The model still has quirks that people will run into and the safeguards are configured to be a little too trigger happy for launch, which can hopefully be tuned over time.
I feel a lot of things changing as working software increasingly comes out on a tap. The Jevon's paradox kicks in and I feel my own demand for software growing substantially. You can ask for anything - explainers, visualizers, dashboards, bespoke single-use apps (e.g. a full wandb that is hyper-specific just for your project), you can 10X your test suite, auto-optimize code, run giant research projects with custom HTML for the results, anything! "Free your mind" (Matrix ref). Really looking forward to all the things people build!