






Peter Pragnakar Atreides retweeted
As France is burning, I keep thinking of what the UAE Foreign Minister said a few years ago 👇
He accurately predicted this.
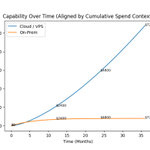
I find the sales pitch around running LLMs locally to save money instead of paying for subscriptions somewhat unconvincing.
Even if the economics work on paper, the hardware would need to be used heavily—potentially 24/7 for years—to reach the break-even point. And there are several practical trade-offs that are often overlooked. Local inference can be constrained by token-generation speed, while power and internet outages can disrupt access. More importantly, once the hardware is purchased, its capabilities are essentially fixed.
The models running on that hardware, however, are not fixed. Over time, models are likely to become larger, more capable, and more computationally demanding. This creates a mismatch: you are making a long-term capital investment in hardware against a rapidly evolving software landscape.
That said, I don't think the answer is necessarily to eliminate local models altogether. A more balanced approach could be to run a relatively small, quantized language model locally—perhaps under 30B parameters—and use it primarily as an orchestrator. It could handle lightweight tasks, maintain local context, determine what needs to be done, and decide when a more capable model is required. When additional intelligence or compute is needed, it could call an appropriate cloud model or inference instance.
This creates a hybrid architecture: cheap, always-available local intelligence for orchestration, combined with on-demand cloud intelligence for computationally expensive tasks.
A more compelling infrastructure model would therefore be AI compute on demand. Instead of owning expensive hardware that sits idle most of the time, users could have access to private cloud inference instances that spin up when needed and shut down when they are not. Something analogous to AWS Spot Instances could be offered specifically for AI inference, allowing users to access significant compute capacity at much lower costs without having to own or maintain the hardware.
Rather than buying a machine and hoping it remains useful for years, you maintain a small local model that acts as your persistent AI interface and orchestrator, while treating large-scale intelligence as an elastic resource that can be accessed whenever required.
One idea I find particularly interesting is bringing the concept of AWS Spot Instances to LLM inference.
AI companies have to provision compute for peak demand. But demand isn't constant, which means a significant amount of expensive GPU capacity can sit underutilized during off-peak periods.
Why not sell that capacity at a discount?
Users with workloads that don't require immediate execution could specify something like: “Complete this within 12 hours at the lowest possible cost.” The scheduler could then run the workload whenever spare capacity becomes available.
This could work especially well for batch inference, embeddings, evaluations, synthetic data generation, fine-tuning, and other latency-tolerant workloads.
The interesting part is that this isn't necessarily about building more hardware. It's about increasing utilization of hardware that has already been deployed.
You essentially create an AI compute market with two tiers:
Guaranteed capacity → higher price, predictable latency
Spot capacity → lower price, flexible execution
Higher utilization → lower effective cost per inference → more workloads become economically viable.
Combined with a small local model acting as an orchestrator, this could be a compelling alternative to trying to run increasingly large LLMs entirely on consumer hardware.
I think the Lambda analogy is useful, but I’d take it one level higher.
Serverless LLM inference already exists in the sense that you can make an API call, have the provider handle the GPUs, and pay for usage. But the interesting abstraction isn’t really “serverless inference.” It’s compute-as-an-outcome.
Instead of specifying: “Run model X on GPU Y.”
you specify: “Solve this task with ≥90% quality, under $5, within 12 hours, with these privacy constraints.”
A compute broker then decides how to execute it—local hardware, on-demand cloud GPUs, spot capacity, a cheaper model, a more capable model, parallel execution, etc.
That creates a hierarchy something like:
EC2: Give me a machine.
Lambda: Give me an execution environment.
AI compute market: Give me a computational outcome under constraints.
Spot capacity would simply be one tier of that market: guaranteed capacity for latency-sensitive workloads, on-demand capacity for normal workloads, and discounted/interruptible capacity for batch or deadline-based workloads.
The really interesting part is when a local 7–30B model acts as the persistent orchestrator. It maintains context and identity locally, decides what needs to be done, and autonomously purchases additional intelligence when required.
So the user doesn't really buy or choose GPUs or even necessarily choose models anymore. They specify the objective, budget, quality, deadline and privacy requirements.
The underlying infrastructure becomes an elastic intelligence grid.
I think that abstraction could ultimately be more important than simply making LLM inference serverless.


Peter Pragnakar Atreides retweeted

DuckTales premiered 39 years ago today.
I loved that show. Not for the gold. For the idea that adventure meant going somewhere wild with people you love.
It was Indiana Jones for kids.
Nobody's making the movie, so I made the trailer. Sound on. 🦆
🤖 Made with AI
Peter Pragnakar Atreides retweeted

My favorite AI joke:
Current models are getting close to PhD-level intelligence. After that, they're expected to achieve the intelligence of someone who decided not to do a PhD.
Wielding power isn't greatness. Greatness is the ability to carry power without becoming enslaved by it.
Peter Pragnakar Atreides retweeted

TBH, THE NORMIES HAVE IT TOTALLY BACKWARDS
At the moment AI is the ONLY thing propping up the US economy
- it's creating jobs
- propping up the stock market
- keeping us safe from hackers
- working on curing diseases
The media and the doomers are being extremely irresponsibel and are playing with real jobs and people trying to get AI banned
Peter Pragnakar Atreides retweeted

Today is 9/11. A day that 25 years ago completely changed the country forever. An act that destroyed lives, families, and futures of so many. Yet through this horrible event strength was found in each other. We lifted each other up and rebuilt. We carried on, with strength, perseverance, and faith in God. The true American spirit.


Peter Pragnakar Atreides retweeted

JUST IN: 2,977 drones recreate the Twin Towers at full scale over New York Harbor, with 1 light honoring each victim of the 9/11 attacks.


Peter Pragnakar Atreides retweeted

China is putting scientists on public screens and treating them like national celebrities, we are so fucked