
Bot that collects popular Machine Learning content on Twitter such as ArXiv papers, blog posts and GitHub repositories. Posts the most popular Arxiv every 24h.
Joined April 2012
- Tweets1K
- Following260
- Followers3.4K
- Likes0




Pinned Tweet
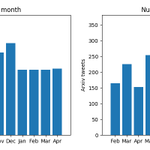
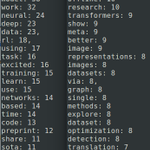
Blog post: One-year monitoring of the machine learning community in Twitter
delanover.com/about/blog/one…

I'm sad to announce that the recent changes in Twitter's API made this bot unable to work. Consequently, there won't be any more tweets and the website won't be updated.
I wonder if something interesting can be done with the 95.5k tweets it collected during its three years of life.

This account has a good number of active ML-interested followers, including ML practitioners and researchers from academia and industry. If you have an idea/offer, you can reach me by email or at @jmlipman
This bot stopped working a couple of weeks ago (during my holidays) probably due to the recent changes in Twitter's API. I will look into it when I have some time.
The most popular Arxiv link during the weekend: xitter.cf/ymatias/status/1659730…

How did our medical #LLM, Med-PaLM 2, become the first to perform at “expert” level on U.S. Medical Licensing Exam-style questions? Check out our new paper: arxiv.org/pdf/2305.09617.pdf

The most popular Arxiv link yesterday: xitter.cf/ShunyuYao12/status/165…

Still use ⛓️Chain-of-Thought (CoT) for all your prompting? May be underutilizing LLM capabilities🤠
Introducing 🌲Tree-of-Thought (ToT), a framework to unleash complex & general problem solving with LLMs, through a deliberate ‘System 2’ tree search.
arxiv.org/abs/2305.10601

The most popular Arxiv link yesterday: xitter.cf/tlngy/status/165896452…
The most popular Arxiv link yesterday: xitter.cf/AziziShekoofeh/status/…

Excited to share our new pre-print on "Med-PaLM 2", highlighting our progress towards achieving expert-level medical question answering performance!
Link: arxiv.org/pdf/2305.09617.pdf

The most popular Arxiv link yesterday: xitter.cf/stevenhoi/status/16582…

Introducing 🔥CodeT5+🔥, a new family of open-source code LLMs for both code understanding and generation, achieved new SoTA code generation performance on HumanEval, surpassing all the open-source code LLMs.
Paper: arxiv.org/pdf/2305.07922.pdf
Code: github.com/salesforce/CodeT5…
(1/n)

The most popular Arxiv link yesterday: xitter.cf/_akhaliq/status/165791…

MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
abs: arxiv.org/abs/2305.07185
paper page: huggingface.co/papers/2305.0…

The most popular Arxiv link during the weekend: xitter.cf/_akhaliq/status/165780…
HACK: Learning a Parametric Head and Neck Model for High-fidelity Animation
abs: arxiv.org/abs/2305.04469
paper page: huggingface.co/papers/2305.0…
The most popular Arxiv link yesterday: xitter.cf/DulwichQuantum/status/…

A breakthrough result that finally resolves the longstanding author ordering problem.
arxiv.org/abs/2304.01393

The most popular Arxiv link yesterday: xitter.cf/_akhaliq/status/165646…
Relightify: Relightable 3D Faces from a Single Image via Diffusion Models
abs: arxiv.org/abs/2305.06077
paper page: huggingface.co/papers/2305.0…
The most popular Arxiv link yesterday: xitter.cf/srush_nlp/status/16563…

Pretraining without Attention (arxiv.org/abs/2212.10544) - BiGS is alternative to BERT trained on up to 4096 tokens.
Attention can be overkill. Below shows *every* word-word interaction for every sentence over 23 layers of BiGS (no heads, no n^2).

The most popular Arxiv link yesterday: xitter.cf/JSheltzer/status/16560…

Fascinating new preprint on bioRxiv tackles a whale of a question:
Whales are huge. So why don’t they get a ton of cancers?
biorxiv.org/content/10.1101/…

The most popular Arxiv link yesterday: xitter.cf/_akhaliq/status/165538…
AttentionViz: A Global View of Transformer Attention
abs: arxiv.org/abs/2305.03210
paper page: huggingface.co/papers/2305.0…

The most popular Arxiv link during the weekend: xitter.cf/cloneofsimo/status/165…

Cool work, have a look! Interesting to see they tie the "probability" of discrete representation to, well, the probability of the dataset : Variational Inference itself.
arxiv.org/abs/2304.04820

The most popular Arxiv link yesterday: xitter.cf/unixpickle/status/1654…

Super excited to release Shap-E, our latest work on 3D generative modeling.
Paper: arxiv.org/abs/2305.02463
Code/models: github.com/openai/shap-e
The most popular Arxiv link yesterday: xitter.cf/abertsch72/status/1654…

What if we could run Transformer models without worrying about context length?
With our new work Unlimiformer, you can jailbreak your current models to use unlimited length inputs!
Preprint: arxiv.org/abs/2305.01625
Thread 🧵 (1/6)
