

geoinformatics; spatial data science; music; bit of jogging; https://xitter.cf/t.co/yWjjnapxya
Edinburgh, Scotland
Joined April 2011
- Tweets1.3K
- Following441
- Followers243
- Likes4.2K



philbartie 🇬🇬🇳🇿🏴 retweeted
Hugging Face is where much of the machine learning community publishes and finds its datasets, while DuckDB is the in-process analytical database that queries files like CSV and Parquet directly, with no server or warehouse to install or run. 🤗 🦆
Did you know that, since #DuckDB v0.10.3 (~May 2024), you can point a SELECT at a dataset on the Hugging Face Hub, using the DuckDB `hf://` protocol, and query it, without downloading it first?
This blog post covers how that integration works and the use cases it fits: duckdb.org/2026/09/25/huggin…

philbartie 🇬🇬🇳🇿🏴 retweeted

Think of Postgres permissioning a series of independent gates (authentication > database > schema > object > row):
1. can the role even connect? (pg_hba.conf)
2. can the role use this database? (CONNECT privilege)
3. can the role see this schema? (USAGE privilege)
4. can the role read/write this object? (SELECT/INSERT/UPDATE/DELETE privileges)
5. can the role see this row? (row-level security policies)
Postgres's permission system is complicated when implemented haphazardly. When implemented thoughtfully, most of the confusion disappears.
For a basic `SELECT`, a role needs USAGE on a schema and SELECT on a table.
philbartie 🇬🇬🇳🇿🏴 retweeted
Postgres assumes columns are independent. When they're not, the planner multiplies probabilities, which can estimate incorrectly.
For example, a city paired with a country
```sql
SELECT * FROM facilities WHERE city = 'Lyon' AND country = 'France';
```
Assuming the following:
```
P(country='France') = 0.0605
P(city='Lyon') = 0.000103
Estimated rows = 3,132,540 * 0.0605 * 0.000103 = 19
Actual rows = 5,816
```
It multiplied the probabilities as if city and country were unrelated. But `city = 'Lyon'` almost guarantees `country = 'France'`. The estimate is off by 300x.
Extended statistics
```sql
CREATE STATISTICS city_country_stats (dependencies) ON city, country FROM facilities;
ANALYZE facilities;
```
Now the planner knows the dependency exists and won't multiply blindly.
Three types of statistics
• `dependencies`: Column A determines Column B (i.e. city → country, zip → state)
• `ndistinct`: GROUP BY overestimates distinct combos (i.e. `GROUP BY category, subcategory`)
• `mcv`: Need exact frequencies for value pairs (i.e. `WHERE org = 'X' AND event = 'Y'`)
philbartie 🇬🇬🇳🇿🏴 retweeted

"We think that with AI we can replace all of our Jr developers in our company"
AWS CEO Matt Garman: "That's the dumbest thing I've ever heard"
The Map of Dreams : Why AI’s “World Models” might be the Geospatial Industry’s Ultimate Disruption edparsons.com/2026/04/the-ma… via @edparsons

philbartie 🇬🇬🇳🇿🏴 retweeted

🔉 Introducing SAM Audio, the first unified model that isolates any sound from complex audio mixtures using text, visual, or span prompts.
We’re sharing SAM Audio with the community, along with a perception encoder model, benchmarks and research papers, to empower others to explore new forms of expression and build applications that were previously out of reach.
🔗 Learn more: go.meta.me/568e5d
philbartie 🇬🇬🇳🇿🏴 retweeted

Have you ever wanted to meet me and/or @markcooperjones to ask us a question or raise a complaint?
Then come and see us on our MAP MEN BOOK book tour in October! 📕 🚌
20th Edinburgh
21st Leeds
22nd Manchester
23rd Bristol
24th London
mapmen.lnk.to/BOOKTOUR

Join @markcooperjones and @jayforeman – also known as The Map Men – the online sensation, on Monday 20th October at 7pm, as they bring us their debut book, all about the world’s worst maps, This Way Up. Book your tickets here: waterstones.com/events/an-ev…

philbartie 🇬🇬🇳🇿🏴 retweeted

Today, we're introducing AlphaEarth Foundations from @GoogleDeepMind , an AI model that functions like a virtual satellite which helps scientists make informed decisions on critical issues like food security, deforestation, and water resources. AlphaEarth Foundations provides a powerful new lens for understanding our planet by solving two major challenges: data overload and inconsistent information.
1️⃣ It combines information from dozens of sources to analyze the world's land and coastal waters in 10x10 meter squares, allowing for remarkable precision while tracking changes over time.
2️⃣ The system's key innovation is creating a highly compact summary for each square. These summaries require 16x less storage than those produced by other AI systems and enables scientists to create detailed, consistent maps of our planet, on-demand.
AlphaEarth Foundations represents a significant step forward in understanding the state and dynamics of our changing planet. 🌎🌎🌎
AGI2025 - GeoAI discussion - discussion included training data challenges, developing spatial models, using LLMs to extract geodata from unstructured text, and issues over what we mean by GeoAI (who is already using machine learning without perhaps knowing it?)...

philbartie 🇬🇬🇳🇿🏴 retweeted
Hey developers - you can create dynamic columns in Postgres to make your queries faster and avoid repetitive calculations. If you’re constantly calculating something like sales tax, totals, normalized addresses or numbers - generated columns can be a huge help.
If you want to store a table for total amount, which is a until price plus sales tax, that would look like this:
ALTER TABLE coffee_shop_sales
ADD COLUMN total_sale_amt numeric
GENERATED ALWAYS AS
((unit_price * (1 + sales_tax_pct / 100) * transaction_qty)) STORED;
Stored columns automatically stay up to date - so when source data is updated, the column is automatically recalculated and updated to reflect the new values based on the updated source data.
To normalize phone number that come in from the application in a variety of formats:
ALTER TABLE contacts
ADD COLUMN normalized_phone text
GENERATED ALWAYS AS (REGEXP_REPLACE(phone, '[^0-9]', '', 'g')) STORED;
Indexing - yes! You can also create an indexes on the generated column, which speeds up query execution when the column is used in filtering or ordering:
Benefits of generated columns
⚡ Performance: These can speed up queries with frequent calculations
✅ Data Integrity: Generated columns ensure the consistency of calculated data, avoiding manual mistakes when writing expressions in queries.
There are two types of generated columns:
Stored: The value of the generated column is physically stored with the table and calculated whenever the row is inserted or updated. This can improve performance because the computation does not need to be done at query time. These ADD COLUMN statements have STORED at the end.
Virtual: For these, the value of the generated column is calculated on-the-fly when the column is queried, but it is not stored physically. This is good for cases when you want some kind of repeated column logic but the stored value doesn't make sense - maybe space or other concerns. These ADD COLUMN calls have VIRTUAL at the end.
By using generated columns, you simplify complex expressions in your queries, reduce computation during query time, and potentially improve performance with indexing.
Worth 10mins.. Prof Geoffrey Hinton on AI Agents:
youtu.be/vxkBE23zDmQ?si=CssQ…
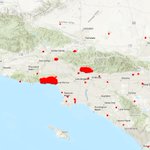
NASA FIRMS fire mapping from space... showing the Los Angeles fires.
firms.modaps.eosdis.nasa.gov…

philbartie 🇬🇬🇳🇿🏴 retweeted
Stanford has launched an incredible research AI tool.
It’s called STORM, and basically you enter a topic and it will search hundreds of websites to write an article about its major findings.
Available to everyone for free!




philbartie 🇬🇬🇳🇿🏴 retweeted
Data Engineers are making fortunes building data pipelines.
I can't think of anything more important than learning how to deal with data for the next 20 years.
Here are a few steps I'd recommend to people who want to learn one of the most in-demand skills in the market right now:
1. Build a strong foundation in programming (especially Python and Java)
2. Practice SQL and learn how to work with relational databases.
3. Become familiar with NoSQL databases and handling unstructured data.
4. Learn the basics of data structures (arrays, lists, trees, graphs) and algorithms (sorting, searching, etc.)
5. Become familiar with tools like Hadoop, Spark, Kafka, Airflow, Luigi, Prefect, and Kinesis.
6. Learn how to implement data pipelines and ETL
7. Gain experience with cloud computing (AWS, GCP, Azure.)
8. Learn containerization and orchestration (Docker and Kubernetes)
9. Become proficient with data warehousing (Snowflake, Redshift, BigQuery)
10. Understand CI/CD pipelines to automate testing, deployment, and integration.
The Data Engineering Nanodegree program in @Udacity is pure fire. It's a 2-month course that covers every one of the topics above.
You'll come out on the other side as a new person.
Everywhere I go, companies need to process data as fast as they produce it. It's hard to find people who know how to do this well, but companies are willing to pay exceptionally well for this.
If you want to start 2025 with a bang, this course is for you!
Link in the next post so I don't get throttled.
philbartie 🇬🇬🇳🇿🏴 retweeted

Mobile phones are everywhere, and conflicts are increasingly being recorded and shared online.
The OSR4Rights research group aims to strengthen the use of open-source research in human rights investigations.
They're 2024 #ImpactPrize finalists!🎉
More:orlo.uk/696tY
philbartie 🇬🇬🇳🇿🏴 retweeted

Hello, world! We are World Labs, a spatial intelligence company building Large World Models (LWMs) to perceive, generate, and interact with the 3D world. Read more: worldlabs.ai/about

philbartie 🇬🇬🇳🇿🏴 retweeted
.@drfeifei, aka The Godmother of AI, discusses her latest startup, World Labs, and why "Spatial" intelligence is a new foundational technology trib.al/jFtk6pF