

Senior AI Systems | Forward Deployed Engineer | Full-Stack | Backend Engineer | Ex-US Treasury. Python, TypeScript, React, Next.js | RAG, Agents, API, Cloud AWS
Joined March 2010
- Tweets207K
- Following15.8K
- Followers22.5K
- Likes47.9K
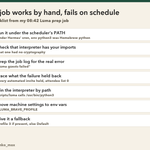



my 08:42 job ran fine in a terminal and built 0 attendees under cron.
it pulls Luma guests and preps the invites for my class. the checklist i use now:
1. run the job under the scheduler's PATH, not your shell. under Hermes' cron, `env python3` resolved to Homebrew python.
2. check that interpreter has your imports. that one had no `cryptography`.
3. grep the job log for the real error. mine said "luma guests failed".
4. trace what the failure held back. every automated invite waited, and the attendee list came out 0.
5. pin the interpreter by path. scripts/luma now calls /usr/bin/python3.
6. move machine specific settings to env vars. the Brave profile is $LUMA_BRAVE_PROFILE.
7. give it a fallback. Profile 3 if it exists on the mac, else Default.
a green terminal run tells you about your shell. it says nothing about the job.
save this for the next job that works by hand and breaks on schedule.
which python is your cron actually calling?

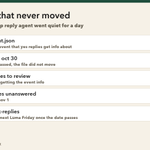
my reply agent stopped answering people because of 1 file.
it handles WhatsApp replies for my friday contact improv class. a yes reply gets the event info, and the event lives in ask-event.json.
after oct 30 passed, the file still said oct 30. so yes replies went to review instead of getting info, and 19 replies sat unanswered from oct 31 to nov 1.
the fix in ask-replies: once the date passes, roll ask-event.json to the next Luma Friday.
any config with a date in it needs code that moves the date.
what in your agent quietly expires?

I gave an AI agent a plain-English task: "Open FileMaker, create a new database, name it, save it." Nobody told it which buttons to press.
It worked out the steps itself, moved a visible mouse across the screen, and explained every click out loud as it went. The voice is an AI clone of mine.
How it works:
• Hermes Agent makes the decisions. It reads the task, picks the next action, and checks the result before moving on.
• Action maps (JSON) record where FileMaker's buttons, menus and dialogs are.
• Notion holds the rules: how to handle popups, when to stop and ask a human, and the run logs.
• macOS Accessibility (AppleScript) does the clicking. The cursor glides to the target and clicks right as the voice says "click".
• Narration comes from Kokoro TTS plus my cloned voice (F5-TTS) on a Mac mini. Word-level timings keep the speech and the clicks in sync.
• screencapture and ffmpeg combine the screen recording and the narration into one video.
• It all runs on a separate Mac, so my laptop stays free.
Give it a new task and you get a new narrated video, with no re-recording. Next: schema, value lists, and turning written procedures into training videos.
If your team trains people on FileMaker or any other desktop software, how do you do it today?
#AIagents #FileMaker #Automation #TextToSpeech
a setup gets tested when it runs unattended. across 26 repos, launchd started calling stale copies until i pinned absolute script paths xitter.cf/milesdeutscher/status/…


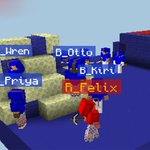
50 agents in a minecraft experiment stalled on bureaucratic process instead of building. coordination overhead, not a capability verdict. size agent teams by verified deliverables, not headcount. a run failing on individual capability would undercut this.

a five-model file-based team matches a good single-model harness, so orchestration buys reliability not intelligence. teams using cheap 27b setups get parity at 0.39 and 40 mins run time but must grade by script and accept longer wall-clock time

a freeform "improvements" box wired to an agent that yolo implements whatever gets submitted is a tiny feature that changes the whole feel of an app. the activation energy to sand a rough edge or add a feature drops to almost nothing. someone using an app built this way implemented 150 improvements over a few days.
that starts to feel like a new kind of tool. liquid software. once it exists, every app without it feels a little rigid and anachronistic. why can't i just tell it how i want it different?
the open questions are real. does it become unmaintainable after a while? maybe model intelligence improves faster than feature appetite, so it's fine. how does collaborative software work in this model? can software designed this way be secure and reliable? broader deployment aside, it works great in a personal context.
it also echoes Lisp/Lisp machines, Smalltalk, and HyperCard: systems the user can take control of and modify. those visions never quite worked, and most software today still isn't usefully end-user modifiable. but this small affordance changes your relation to the software. a little transgressive, a little empowering, in a Lickliderian and Engelbartian way.

whichever agent you're running, your voice is still the best way to talk to it. opencode's hex is the best way to actually use that voice:
- fast
- runs locally
- mac, windows, linux
stable release is out now: anoma.ly/hex


volta doesn't treat a model refusal as a stop. it scans the response for 'i can't,' then fails over to smaller, more permissive models. if your misuse control is 'the model will refuse,' your real safety floor is the most permissive model in your chain.

the router is the weak point now, since a wrong cluster pick hands a run the wrong memory and nothing errors. xitter.cf/dair_ai/status/2116548…

Brilliant paper on agent memory from FAIR at Meta.
(bookmark it)
A single global history is the usual way to let agents learn from past runs. When tasks are interleaved, it gains almost nothing over no memory at all, an average of +0.015 in normalized reward.
This work proposes Routed Continual Learning. Past trajectories are grouped into clusters, and each cluster keeps its state in one memory system from a fixed library. Before each run, an LLM router reuses a cluster or creates a new one.
They tested it on a stream mixing 301 CL-Bench instances with 97 banking instances from τ³-Bench, across four language models.
Routed CL raised reward over the global history by 15% to 30% of the maximum attainable reward. Estimated API cost fell by 65% to 72%.
The runs were sequential, so parallel agents updating one cluster remain untested.
If your agents handle mixed work, it might help to split their memory into clusters before adding a bigger memory system.
arxiv.org/abs/2610.38796
Chat with Paper: academy.dair.ai/papers/route…

the chatgpt account takeover was a composition failure, not a chatgpt auth flaw: a sandboxed html preview and a graph's mathlive listener were each harmless alone and dangerous together. if mathlive had enforced origin checks, the chain would have stopped.

my cron-guard test called kickstart directly, so it only held on one os. made it os independent.
a guard you can't test off the box it guards is just a launchd check.
what's the blind spot in yours?


for scoring content with many questions, the costly part is re-reading the document repeatedly, not the model. batching questions in one pass reduces cost and latency. builders should count document passes, not just tokens per answer, to pick an efficient chat stack.

mistral large 4 does the same coding work as glm-5.3 with 47% fewer tokens per task, and halved its own preview price to get there. 48% on the coding agent index, level with glm. the number that decides now is cost per finished task, not rank.
one terminal core under two apps means a fix lands once. my mac mini runs 80 scheduled jobs, and until i pinned paths some ran stale copies. xitter.cf/mitchellh/status/21161…

mistral large 4 ties glm-5.3 at 48% on the coding agent index using 47% fewer tokens per task, at near half the preview price. for anyone running coding agents at volume that moves the deal to cost per finished task, not index rank. reruns on token burn could break it.

ALT dark card: mistral large 4 ties glm-5.3 at 48% on the coding agent index, uses 47% fewer tokens, price cut to 0.7 and 2.1 per million
I just earned the Introduction to Agents certification from Mercor.
This was fun.
work.mercor.com/learn/verify…