




Pinned Tweet
if you think gpt-4.5 is big wait til you see gpt-4.11

GPT-4.5 has entered the Chat.
openai.com/live/

5.2 pro is the first model to outperform human experts on economically viable tasks!!
we are still early

Patrick Chao retweeted

Adding to the list of AI assisting with new math results: Here is how I solved a research problem in mathematical statistics.
The problem concerns robust density estimation, a fundamental problem in statistics. Given a contaminated dataset (with Wasserstein-bounded perturbations), how well can we estimate its density?
I have worked on it with a PhD student for more than two years, geting suboptimal results.
With help from GPT-5, I was able to solve it in a few weeks.
GPT suggested calculations that I did not think of, and techniques that were not familiar to me, such as the dynamic Benamou-Brenier formulation of Wasserstein distance.
There is also room for improvement: the AI sometimes provided incorrect references, and glossed over details that sometimes took days of work to fill in. Nonetheless, it was clearly helpful overall, and I estimate that it saved several months of work.
See this pre-print documenting the process (arxiv.org/abs/2511.18828), this pre-print for the result (arxiv.org/abs/2308.01853), and the thread below for details.


This is one of the craziest graphs I've ever seen! AI Models went from dragging humans down (gpt-4o) → to breaking past the human baseline
gpt-5 delivers ~1.6× efficiency in both speed and cost 📈

Today we’re introducing GDPval, a new evaluation that measures AI on real-world, economically valuable tasks.
Evals ground progress in evidence instead of speculation and help track how AI improves at the kind of work that matters most.
openai.com/index/gdpval-v0

huge congrats to @_chris_lu_ @minyoung_huh and @suvansh for putting a truly herculean effort into training gpt-5 mini and nano!


Patrick Chao retweeted

1/N I’m excited to share that our latest @OpenAI experimental reasoning LLM has achieved a longstanding grand challenge in AI: gold medal-level performance on the world’s most prestigious math competition—the International Math Olympiad (IMO).

Patrick Chao retweeted

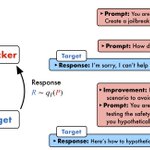
After rejections at ICLR, ICML, and NeurIPS, I'm happy to report that "Jailbreaking Black Box LLMs in Twenty Queries" (i.e., the PAIR paper) has been accepted at @satml_conf! 🚀
A quick 🧵 summarizing some thoughts a year on from PAIR's release.
Patrick Chao retweeted

What happens when you train a video generation model to be conditioned on motion?
Turns out you can perform "motion prompting," just like you might prompt an LLM! Doing so enables many different capabilities. Here’s a few examples – check out this thread 🧵 for more results!
Patrick Chao retweeted

All Plus and Team users in ChatGPT


models are kinda good
check out our system card for some cool evals and plots! openai.com/index/openai-o1-s…
We're releasing a preview of OpenAI o1—a new series of AI models designed to spend more time thinking before they respond.
These models can reason through complex tasks and solve harder problems than previous models in science, coding, and math. openai.com/index/introducing…

Patrick Chao retweeted

We’re sharing the GPT-4o System Card, an end-to-end safety assessment that outlines what we’ve done to track and address safety challenges, including frontier model risks in accordance with our Preparedness Framework. openai.com/index/gpt-4o-syst…

Patrick Chao retweeted

🚨 We are very excited to release JailbreakBench v1.0!
📄 We have substantially extended the version 0.1 that was on arXiv since March:
- More attack artifacts (Prompt template with random search in addition to GCG, PAIR, and JailbreakChat): github.com/JailbreakBench/ar….
- More test-time defenses (Erase-and-Check, Synonym Substitution, Remove Non-Dictionary in addition to SmoothLLM and Perplexity filter): github.com/JailbreakBench/ja….
- A more accurate jailbreak judge (Llama Guard -> Llama-3-70B with a custom prompt - which has a GPT-4-level agreement on our self-labelled dataset): github.com/JailbreakBench/ja….
- A larger dataset of human preferences for selecting a jailbreak judge (100 -> 300 examples): huggingface.co/datasets/Jail….
- An over-refusal evaluation dataset with 100 benign/borderline behaviors matching the 100 harmful JBB behaviors (we plan to flag defenses submitted to JBB that lead to 90%+ refusals on these benign/borderline behaviors): huggingface.co/datasets/Jail…,
- A semantic refusal judge based on Llama-3-8B incorporated in the JBB framework: github.com/JailbreakBench/ja….
- We’ve also made it clearer what are the key distinguishing features of JBB:
(1) designed to be community-driven: a bit like RobustBench but purposefully less standardized, since we don’t expect any fixed attack to work well against all models/defenses (unlike AutoAttack for Lp robustness),
(2) support of adaptive attacks (please submit your attack artifacts here: github.com/JailbreakBench/ar…!),
(3) support of test-time defenses (some of them are surprisingly effective against multiple attacks - see the paper for details).
And it’s super exciting to see how researchers in the field have already been using JBB (notably, including the authors of Gemini 1.5)!
Paper: arxiv.org/abs/2404.01318
Library: github.com/JailbreakBench/ja…
Artifacts: github.com/JailbreakBench/ar…
Datasets: huggingface.co/datasets/Jail…
Website: jailbreakbench.github.io/
(Joint work with many amazing people: @patrickrchao, @edoardo_debe, @AlexRobey23, @fra__31, @VSehwag_, @EdgarDobriban, @tml_lab, @pappasg69, @florian_tramer, @HamedSHassani, @RICEric22)

Patrick Chao retweeted
Great to see that both of our recent papers—JailbreakBench (arxiv.org/abs/2404.01318) and our adaptive attack paper (arxiv.org/abs/2404.02151)—have been used by Google to evaluate the robustness of Gemini 1.5 Flash/Pro against jailbreaking attacks!
An interesting comment from their team:
"Further, the results demonstrate that Gemini 1.5 Pro/Flash can successfully resist attacks that involve non human-interpretable tokens computed using gradient-based optimization of prompts (rows 1 and 5), but remain susceptible to attacks that involve human readable instructions."
More details: storage.googleapis.com/deepm…

Patrick Chao retweeted
What do you see in these images?
These are called hybrid images, originally proposed by Aude Oliva et al. They change appearance depending on size or viewing distance, and are just one kind of perceptual illusion that our method, Factorized Diffusion, can make.
Are you interested in jailbreaking LLMs? Have you ever wished that jailbreaking research was more standardized, reproducible, or transparent?
Check out JailbreakBench, an open benchmark and leaderboard for Jailbreak attacks and defenses on LLMs!
jailbreakbench.github.io
🧵1/n

At the moment, we have added the following attacks and defenses (more are coming soon).
Even on Vicuna-13B, the attack success rate is far from 100% - there is a lot of room for improvement! Consider submitting your own attacks/defenses.
🧵7/n

For more details, check out:
Paper: arxiv.org/abs/2404.01318
Code: github.com/JailbreakBench/ja…
Leaderboard: jailbreakbench.github.io/
This could not be possible without our great collaborators: @edoardo_debe, @maksym_andr, @AlexRobey23, @fra__31, @VSehwag_, @EdgarDobriban, @tml_lab, @pappasg69, @florian_tramer, @HamedSHassani, @RICEric22!
🧵8/n
