
Retweets are just stuff saved for later—cool stuff, horrible stuff, stuff to reread. Probably wrong about 49% of things, just don't know which—help me out, thx!
Louisville, KY
Joined March 2015
- Tweets5.9K
- Following307
- Followers63
- Likes4.2K


je'Datlh retweeted

It's f*cking wild: Google, Cloudflare, Obsidian's CEO and the guy building Claude Code all put their AI configs on GitHub for free, and most people are still starting from zero
1. Matt Pocock's skills · 318K stars
18M+ installs. the exact folder of AI instructions he uses every day: tests first, clear specs, real reviews
github.com/mattpocock/skills
2. Addy Osmani's skills · 92K stars
engineering skills from the guy working on Claude Code at Anthropic
github.com/addyosmani/agent-…
3. Cloudflare's audit · 63.9K stars
the starting point of what now scans 128 of Cloudflare's own repos. one team of agents hunts for bugs, another tries to prove them wrong
github.com/cloudflare/securi…
4. Obsidian CEO's skills · 51K stars
teaches any AI to write real Obsidian notes instead of messy text
github.com/kepano/obsidian-s…
5. Google's goldfish · 14.8K stars
2 weeks old. the plugin Google's own engineers use to catch AI coding mistakes. the agent writes a design doc, then fresh AI sessions that never saw it try to tear it apart
github.com/google/elephant-g…
the biggest teams in tech already stopped writing prompts from zero. their configs are one click away
save it and steal one tonight


je'Datlh retweeted

ok this paper is f*cking insane
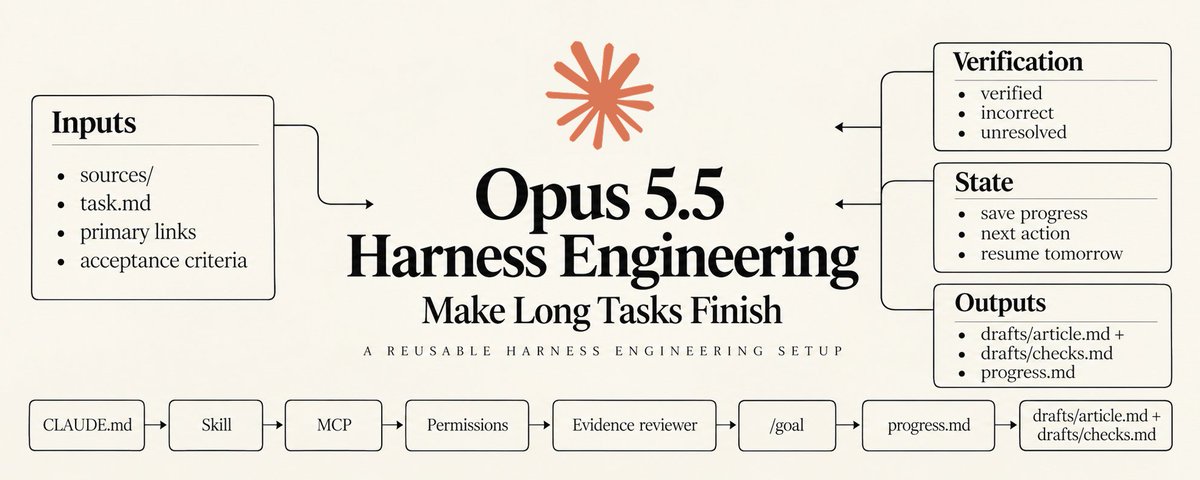
Chinese researchers just put out a paper with a title that should make every agent framework nervous: "The End of Harness Engineering"
the argument fits in one line: hand-writing the program around the model is finished as a skill
a harness written by a person is one guess about one task on one afternoon. it ships, then runs for months unread and unscored
a harness written by the loop is a file that grades itself. a small 4B model reads what failed, proposes 8 edits, and only the edit that scores best on held-out questions survives
the big model stays frozen the whole time, and every round rewrites the file around it
so the human job shrinks to one artifact: the scoring set, the questions the harness gets graded on
frameworks turn disposable, and the exam turns into the job
the whole paper in one line: write the exam before the code
the builder's guide to the harness this loop starts from is below ↓

je'Datlh retweeted

experimenting with a lil personal project: an AI-native macOS dock with custom modes (writing, building, etc.) to help me stay focused
my agent is able to customize mode behavior and add new modes, it uses jev to classify my activity + notifications in real time & act on them
je'Datlh retweeted

Andrej Karpathy spent 8 years at OpenAI and Tesla
Last week he compressed everything he knows into one free 2-hour lecture
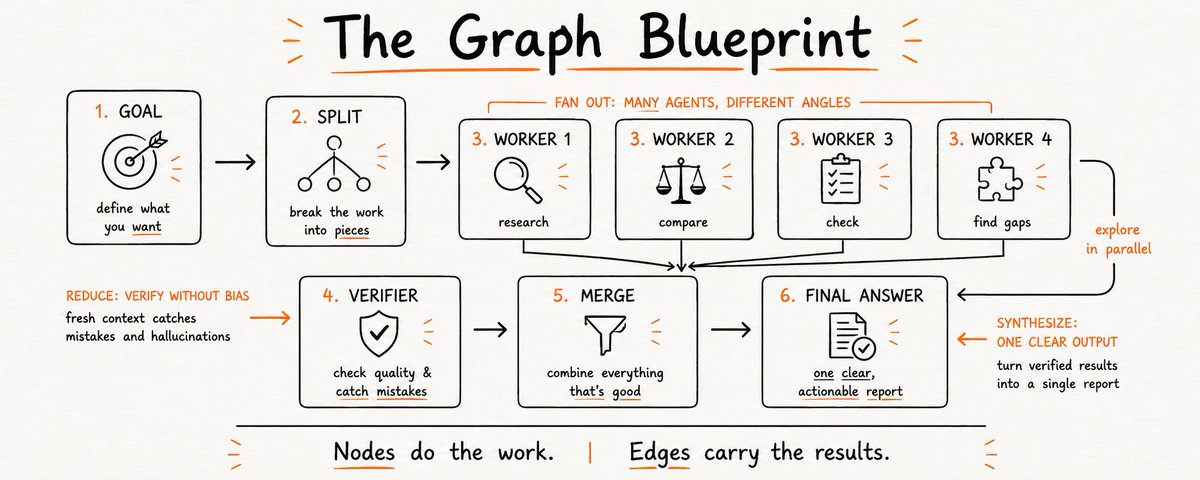
Prompts → Agents → Harness → Graphs → Loops
People spend $15k on bootcamps that teach less than this
You probably don't have 2 hours right now
Don't let it vanish from your feed
Watch it, then read the full Opus 5.5 harness engineering guide below

je'Datlh retweeted

She's 18 built an AI agent with Opus 5.5 and sold it to Anthropic for $3.4M - and came to Stanford to show how to do it from scratch:
00:34 - how Opus 5.5 builds a $3.4M agent in one evening
15:34 - 4 agents replaced 400 Anthropic engineers
34:47 - from first prompt to a $3.4M check from Anthropic
after watching I spent 60 minutes building my first agent - it cut my workday by 90% and a week later I got a $100k check from Anthropic:
save & watch - article below on how to go from one prompt in Claude Code to an agent people pay millions for.


je'Datlh retweeted

Holy sh*t Andrej Karpathy has basically put a full AI degree on GitHub and it costs nothing.
7 repos that 300,000+ developers have already starred.
Do them in order and you go from "what is a gradient?" to agents that run experiments while you sleep.
Each one builds on the last:
1. micrograd
Start here. A tiny autograd engine that shows you exactly how a network learns. Around 100 lines.
→ github.com/karpathy/microgra…
2. nn-zero-to-hero
The lecture series. Notebooks that take you from a single neuron all the way to a working GPT.
→ github.com/karpathy/nn-zero-…
3. minbpe
Before a model reads anything, text gets chopped into tokens. This is that step, written cleanly.
→ github.com/karpathy/minbpe
4. nanoGPT
Train and fine-tune your own GPT with the least code possible.
→ github.com/karpathy/nanoGPT
5. llm.c
The same training, minus the safety net. Plain C and CUDA, no PyTorch.
→ github.com/karpathy/llm.c
6. nanochat
A complete ChatGPT-style model, from tokeniser to chat UI. GPT-2 level results for pocket change compared with what it cost in 2019.
→ github.com/karpathy/nanochat
7. autoresearch
The final layer. An agent tweaks the training code, runs a short experiment, keeps what worked and loops through the night.
→ github.com/karpathy/autorese…
Most people use AI very few understand how it's built.
Work through these and you'll be the one your team turns to when the AI project lands.
je'Datlh retweeted

Anthropic engineer:
"90% of our engineers were already running self-improving loops on Opus 5.5
Now everyone is moving toward agentic graphs"
"Prompting is basically over"
In just 10 minutes, she builds her whole Claude Code setup live from an empty terminal
Agents → Loops → Graphs → Self-Improving Systems
Prompting was the old workflow
Graph engineering is the next one
This 10-minute breakdown is worth more than most $1,000 agent engineering courses
Watch it today
Then read the article below ↓


je'Datlh retweeted

Many of you don't understand how serious this is, so let me break it down.
In computer science there is a famous kind of puzzle called 3-SAT. You are given a long list of yes-or-no switches and a set of rules about how they must be arranged, and you have to find a combination that satisfies every rule. The obvious way to solve it is to try every combination, but each new switch doubles the number of possibilities, so a puzzle with a few hundred switches would take longer than the age of the universe to brute force.
For decades, the smartest people in the field found clever tricks that made this a little faster, but every trick still hit the same wall: the time required kept exploding as the puzzle grew.
About 25 years ago, two computer scientists, Russell Impagliazzo and Ramamohan Paturi, working with Francis Zane, turned that wall into a formal idea.
They proposed the Exponential Time Hypothesis, which says this explosion is not a failure of human cleverness but a law of nature. No algorithm, however brilliant, will ever solve 3-SAT without the time blowing up exponentially. Nobody could prove it, but almost everyone believed it, and it became one of the foundations of modern computer science.
Researchers used it as a measuring stick. If you could show that solving some other problem quickly would also crack 3-SAT quickly, you had shown that problem was hopelessly hard too. Hundreds of papers, across scheduling, graphs, logic and much more, rest on this one assumption.
Now an internal AI model at OpenAI claims to have broken it. It says it found an algorithm that solves these puzzles meaningfully faster than the hypothesis allows, and it has checked the proof in a computer verification system called Lean.
And here is the remarkable part: the very people who proposed the hypothesis, Impagliazzo and Paturi, along with MIT's Ryan Williams, are now leading the public review of whether a machine has disproved their own idea.
So what happens next? If the disproof holds, a large part of theoretical computer science has to be revisited.
Every result that said "this problem cannot be solved faster, assuming ETH" loses its foundation, and researchers will have to work out which of those walls were real and which were simply where we stopped looking. It does not mean everything becomes easy. The new algorithm is still slow in absolute terms and this is not the famous P versus NP problem being solved.
But it means our map of what is possible was wrong in a place we were very confident about, and it was an AI that redrew it. If the disproof fails, the hypothesis survives and the field breathes out, but we will still have watched an AI produce serious, checkable work on one of the deepest questions in the discipline, closely enough that the founders of the idea had to take it seriously. Either way, something has shifted.

je'Datlh retweeted

Google Brain founder, Andrew Ng:
"Prompting will be dead in 6 months, graphs are what's replacing it."
In 2 hours at Stanford he shows how to build agents that work and improve entirely on their own.
The first 10 minutes cover what most $500 courses never do. Bookmark this before your feed buries it.
Watch the lecture, then read the guide below on how to build a system that improves itself.

je'Datlh retweeted

This is cool but it doesn't seem like a feature I would want to pay extra for in my car.

je'Datlh retweeted

Boris Cherny, the creator of Claude Code at Anthropic, has just explained why most people aren’t getting real results from Claude.
In this podcast, he breaks down how almost nobody properly configures Claude:
The 14% you lose with CLAUDE. md before typing a single word
The features that change how Claude thinks before you even prompt it
The setting that 95% of users have never opened
The workflows hidden behind a single toggle
If you’ve been using Claude for over a month and have never left the chat window, you have at least 30 features you haven’t touched. Probably 38.
Tonight, instead of watching another series, watch this.
Save it to your bookmarks before it disappears from your feed
je'Datlh retweeted

A man spends 50 years teaching at MIT.
He knows his time is running out.
So he records one last lecture — everything he knows, distilled into a single hour.
He died 5 months later.
This is that lecture.
The most important hour you'll watch this week. 👇
Bookmark it for later
If you have one uninterrupted hour this week, I'd recommend watching it.
🔖 Save this for when you have the time.
je'Datlh retweeted

We are now at "the fuck" levels.


"Our initial evaluation suggested that GPT-6-Astra's score was in the late eighties followed closely by Opus 5.5. But, as we started to investigate the mistakes that the models might have made, the models, especially Astra, insisted that they were right and that it was the expert-supplied answers that were erroneous. When we went back to the experts it turned out, in multiple instances, that that the experts found some subtle errors buried deep inside their calculations. As they revised their answers, Astra's score started to inch up and it finally ended up with 98% (49/50)."


je'Datlh retweeted

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/

je'Datlh retweeted

What should humans learn in the age of AI—and how should we learn with it?
Today, we’re officially launching Gakku—an AI-native learning coach for writing, speaking, and thinking, built for ages 6–16.
As natural language becomes our interface with intelligence, critical thinking and original expression matter more—not less.
Most AI products optimize for results. Gakku is built around the process—the human experience of getting there.
Through real-time voice and multimodal interaction, learners talk it out, explore ideas, revise, and create something of their own.
Meet Gakku: gakku.ai/
je'Datlh retweeted

Andrej Karpathy:
"Prompting is going away.
Delete everything, keep Graph."
In 1 hour he explains how to build Graphs, and why it's the only thing that will be left standing at the end
LLMs → Prompts → Agents → Graphs
a prompt gets you one answer and forgets the job
an agent finishes the job and forgets what it learned
a graph saves every finished job and turns it into the starting point for the next one
watch it today
then save the full guide on Graphs below before everyone catches up ↓

je'Datlh retweeted

What is intelligence? What will it take to create AGI? What happens once we succeed?
The Scaling Era: An Oral History of AI, 2019–2025 by @dwarkesh_sp and @gleech explores the questions animating those at the frontier of AI research.
It’s out today: press.stripe.com/scaling
je'Datlh retweeted

The persona selection model explains why agents feel more human than pure autocompletion. They're learning the character through role modeling, not just pattern matching. This is why SOUL.md matters — it bakes in the character early.

je'Datlh retweeted

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
