

autonoumous vehicles | farming robots @3farmatebots | ex @conigital | 776 Fellow | local AI hacker
sf/acc
Joined October 2020
- Tweets2K
- Following427
- Followers1.2K
- Likes927






Pinned Tweet
agriculture changes forever starting today.
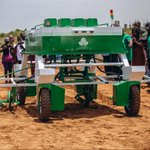
introducing FAMA, our gen 1 autonomous robot that plants seeds, fertilizes, and weeds farms. fully self-driving, no GPS.
we had no hardware background when we started. but we pulled through.
more robots for farming incoming 🚀
Clinton 🛸 retweeted

PCBs made in America. Twice as fast as Shenzhen.
Today @CircuitHub is unveiling The Grid, our factory-scale robot in Massachusetts that builds circuit boards on demand.
No changeovers, no per-design setup. Prototypes and production batches, fully automated.


bam! well said

Oxide co-founder @bcantrill believes every VC wants to be contrarian, but most get cold feet when an actual contrarian bet is staring them in the face.
"Everybody loves contrarian. But no one actually wants a zero."
Clinton 🛸 retweeted

Fuck watches, suits, designer whatever
The biggest rich flex in the world is building Sci Fi companies and products that redefine the human experience

slowly, then suddenly, all at once. exciting times ahead

Big news for CAD: SMLIB, NVIDIA's NURBS based kernel is finally open source today 🍻🎉
We have been working with SMLIB and its dev team for more than 20 years. It enables all our products: classcad.ch headless CAD, GUI, AI/MCP, PDM, etc
github.com/NVIDIA-Omniverse/…
Clinton 🛸 retweeted

Nearly every VC says they love hardware. The number that actually do is easily short enough to memorize and state in a single breath. All the founders know who is who.

can’t help but feel the big labs are going to attack hardware hard in the coming months, which would leave a lot of “vibe-engineering” startups in a tough spot
ultimately the harness counts, but where does that value lie when you can point an agent to one and have it replicate it, or make something pretty close?
after all, reverse engineering is becoming common these days
kids today will never understand the joy of successfully building and training a sequential neural network in tensorflow
machine learning back then was just pure vibes man. i miss those days
the rise of local AI hardware is upon us, bros
this one ships with 16gb of vram and apparently runs qwen 3.8 27b, 4bit quantised i’m guessing.
but if the model itself is about 13.5gb, that leaves less than 3gb for kv cache.
so how are they keeping the experience healthy with that little headroom?
especially when kv cache grows with the conversation and compounds over longer sessions.

Say hello to Oki Home, your Personal AI Computer.
We're building a future of limitless, personalized intelligence for every consumer, while keeping all your data in your hands.
Reserve our first batch, shipping mid-december! okihome.ai
if only we could see under the hood what those optimisations are. regardless, cool product @zainmfj
can’t wait for benchmarks though when this finally ships

Clinton 🛸 retweeted

Introducing Core, The Personal Al Computer
The most powerful technology humanity has built should belong to you
Order today: ghost.ai
incredible product!
keen to know how they address kv cache hurdles as conversations grow and eat up vram, given this ships with only 24gb of vram
Introducing Core, The Personal Al Computer
The most powerful technology humanity has built should belong to you
Order today: ghost.ai


Clinton 🛸 retweeted

I'm holding 10,000 synthetic neurons in my hand.
In the podcast below, more of the story of how we got here, and the foundations behind what we built (thanks @fdotinc).
🔽 Prima-Lux: our first artificial brain in silicon. We can't wait for people to try it!


We brought in a founder building synthetic neurons.
His goal is to sell the first artificial brain, to a robot.
He gave a brief tutorial on how to make one:
22:47 Building a synthetic neuron from scratch
24:15 Making a robot move using only synthetic neurons
28:33 Dendrites, cell bodies + axons with hardware
32:42 Turning sensor data → spikes → movement
34:11 The roadmap to a full synthetic brain
38:00 A breakthrough in synthetic memory
By the end, we weren’t really talking about robots anymore...


Clinton 🛸 retweeted
imo the ideal local AI stack should look like this:
LLM + bounded active KV cache + external long-term memory + automatic summarization + retrieval
keep only what the model needs in context, while the rest lives outside the KV cache and gets pulled back in when relevant
that could make long-running local sessions feel effectively unbounded without requiring insane amounts of VRAM

i love running and tweaking models locally, but the growing KV cache from longer conversations eventually eating into generation speed can be a real pain when you’re using local AI for actual work
we need an ecosystem that makes local models feel as seamless as, and ultimately better than, cloud-hosted AI
Clinton 🛸 retweeted
i love running and tweaking models locally, but the growing KV cache from longer conversations eventually eating into generation speed can be a real pain when you’re using local AI for actual work
we need an ecosystem that makes local models feel as seamless as, and ultimately better than, cloud-hosted AI