

Turning onchain data into growth insights | Pet projects: outputlayer/rwa_cli and @PredGraph | DMs open
16.04
Joined August 2019
- Tweets751
- Following1.7K
- Followers1.4K
- Likes2.5K



Outputlayer retweeted

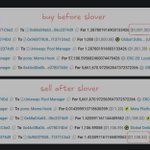
FINALLY found the "@FOMO MEV ATTACKER" 🚨
this is the guy destroying your FOMO entries:
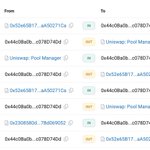
0x44c0ba0b734d4b7705fcd07ddae9fbbc078d74dd
They frontrun FOMO buyers actively...
A new victim every minute!!!
they switch addresses every other day. current one:
0xb49deec1a52eea46f3a6a158f8f9b155809b8c44
@seyong your users are being affected by these sandwich attacks every minute. FIX THIS ASAP.


Hey @fomo, @seyong and @RelayProtocol, check your team or partners: someone is front-running your users (sandwich attack) on the Robinhood chain, likely using private order info.
Wallet: 0x44c0ba0b734d4b7705fcd07ddae9fbbc078d74dd
Contract (since Sep 24): 0x68a04a63fd1d8eabf167ef48ed0a0ef06c2374d9
Solver affected: 0xccc88a9d1b4ed6b0eaba998850414b24f1c315be
Impact on your users: ~$14k+ in the first day
Sandwich attacks: 328
Typical lead over your solver: 1–4 blocks
Solver volume hit: ~$412k

Outputlayer retweeted

Finally got around to reading this. Great stuff.
As a person that got stuck in morpho markets one too many times, maybe this trick can be used to track borrowers and once they pay back their loans we can insta withdraw right after them in the same block (is this called backrun?).
Or perhaps if a lender withdraws a bit too much from the pool (but not completely), we can still make it out partially depending on risk/comfort levels.
Front running a whale, market decimating withdraw, is a bit more complex (mempool monitoring and gas war I think. Not sure how private mempool complicates this).
I guess this use case is more plebian than monitoring the mempool. I don't think I have the resource to pull that off.
Outputlayer retweeted

Wow, this tweet went very viral!
I wanted share a possibly slightly improved version of the tweet in an "idea file". The idea of the idea file is that in this era of LLM agents, there is less of a point/need of sharing the specific code/app, you just share the idea, then the other person's agent customizes & builds it for your specific needs.
So here's the idea in a gist format: gist.github.com/karpathy/442…
You can give this to your agent and it can build you your own LLM wiki and guide you on how to use it etc. It's intentionally kept a little bit abstract/vague because there are so many directions to take this in. And ofc, people can adjust the idea or contribute their own in the Discussion which is cool.


LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
Outputlayer retweeted

Wow, @outputlayer absolutely crushed it with this Boros dashboard!
Everything you need in one place: OI, volume, DAU, fees and more 👏🏻

Presenting the dashboard I developed over the past months for the @pendle_fi team on the @boros_fi project.
It covers the key metrics and provides structured breakdowns of the market, users, and fees.
Everything is organized for direct analysis!

Outputlayer retweeted
@boros_fi is currently generating around $2k in fees daily from 485 open positions + users who are trading

Presenting the dashboard I developed over the past months for the @pendle_fi team on the @boros_fi project.
It covers the key metrics and provides structured breakdowns of the market, users, and fees.
Everything is organized for direct analysis!
Outputlayer retweeted

Boros → Explosive Growth in ETH Volume and OI
In just the first 7 days of October ETH Notional Open Interest and trading volume on @boros_fi have surged dramatically → From $100K to $5M per day
Deposits have now exceeded $5M, marking a strong early adoption trend.
Currently, Boros is only available on @arbitrum
Just like Pendle V2 before it, every major innovation in Pendle’s ecosystem has consistently launched on Arbitrum first → From fixed yield to trading of funding-rates
Boros appears to be following the same growth trajectory as @pendle_fi V2
More chain → More Volume → More Yield

Outputlayer retweeted

Building great @Dune dashboards can be rewarding, in many ways. Well done @outputlayer!

15,000 RESOLV → @outputlayer
The most comprehensive Resolv dashboard: 70+ visuals tracking USR, stUSR, RLP flows, integrations, and liquidity.
Already used by thousands, it has become a main source for real-time data into protocol performance.
dune.com/outputlayer/resolv

Outputlayer retweeted

3/ Sep 3: @OndoFinance launched Global Markets (GM) → 100+ U.S. stocks + ETFs onchain via Directive Tokenization:
• Direct broker-dealer, no wrappers/SPVs
• TVL ~$48.5M (56% ETFs / 44% stocks)
On Sep 4: @galaxyhq directly tokenized GLXY on @solana with @superstatefunds

ALT https://dune.com/ondo/ondo-global-markets
Outputlayer retweeted
3/ @Terminal_fi has attracted $163M in pre-Converge deposits (mostly USDe, WETH, WBTC) and now ranks second after @etherealdex. With >30K users, it highlights surging excitement for @convergeonchain, and @ethena’s growing dominance ($8.5B+ USDe).

ALT https://dune.com/outputlayer/terminalfi
Outputlayer retweeted

The top users at @nodeguardians never cease to amaze me.
@outputlayer just put together an impressive Dune dashboard breaking down the @Terminal_fi pre-deposit campaign!
My latest work on the pre-deposit stage of the @Terminal_fi covers:
- Inflows and outflows
- TVL broken down by asset
- Deposit charts by asset/token
- DeFi usage segmented by asset
- User profiles and their patterns
- User behavior analytics and more

Outputlayer retweeted
3/ The most common time and volume ranges for users farming points before their first withdrawal:

Outputlayer retweeted
2/ According to my data,@Terminal_fi managed to attract 45% new users. The remaining 55% also made deposits to @etherealdex and @strata_money

Outputlayer retweeted

Everyone thinks @Dune is just dashboards. But we are the onchain data backbone for institutions, governments and TradFi.
With @RippleXDev XRP Ledger now live, enterprise grade transparency is here.
Check the stats of this L1. Dashy by @outputlayer 👇
dune.com/outputlayer/xrpl-ov…

Outputlayer retweeted
1/ 🎉 XRP Ledger (XRPL) is now on Dune!
The iconic, fast, low-cost, and decentralized blockchain with 10+ years of uptime is now fully queryable.
Let's check it out!
dune.com/blog/xrp-ledger-is-…

Outputlayer retweeted

A lot of teams fly blind when it comes to real performance data.
You can’t properly steer protocol or product strategy without precise, on-the-money insights.
Came across Outputlayer via his @ResolvLabs work and now he has cooked up something special for @StargateFinance. The insights below just scratch the surface of the mega-dashboard he built.
If you want real onchain visibility, Output’s a @Dune wizard.
$61B in Total Volume Bridged
53M Transactions
4.4M Unique Wallets
The name of this giant is @StargateFinance
After @LayerZero_Core added their data to @Dune, I was finally able to dive deeper and see the true scale of this giant.

Outputlayer retweeted

weekend watch to address the FOMO youtu.be/7xTGNNLPyMI?si=JXFy…
Outputlayer retweeted
Perps Domination on Arbitrum 📈
Leading perpetual platforms:
• @GMX_IO (OG dex)
• @vertex_protocol (multi-chain)
• @gains_trade (memecoins: DOGE,DOGE,PEPE)
📊
• Avg. 200K–200K–1M weekly fees
• 3K+ monthly users
Dashboard by @outputlayer: dune.com/outputlayer/arbitru…

Outputlayer retweeted
1.5M+ Abstract Global Wallets (AGWs) created, 1.2M with at least 1 txn.
70+ ETH in fees, 2.3M+ badges minted (avg 6 per user).
Source: dune.com/outputlayer/abstrac…


