

Making computers solve problems we can't. Occasional cypherpunk. 🏳️🌈. DMs open @nonagon on bsky
San Francisco, CA
Joined April 2010
- Tweets3.9K
- Following435
- Followers679
- Likes3.9K






Zygi retweeted

I’m surprised by how many people I respect, in replies here, take seriously the idea that we could in theory build an impartial god-machine that could serve every human’s interest without meaningful trade-offs.
I very strongly disagree with this. It’s much more optimistic than even the Christian image of God, where trade-offs abound.
In particular, some versions of the response I’m getting come across as what Mormons would describe as an almost verbatim rehash of Satan’s plan in their cosmology: a higher power that spoon-feeds you the exact optimal choice every step of the way, putting you on a pathway to a sort of heaven with no meaningful agency whatsoever.
This all comes much closer to theology than I’ve talked much about in a while, and I do actually think that a lot of Christian thought is relevant here, so with any luck I’ll have the chance to sit down and write a proper response sometime. For now, I’ll just register that I’ve suddenly noticed I disagree very strongly with this part of rationalist theology.

Zygi retweeted

Yes, it seems indeed the models even obtained the results on the same day. I haven't had a chance to look through the OAI claimed proof yet, but in the spirit of the AGMAI recommendations to improve exposition before release, some of us did read Claude's proof last week before release to try to incorporate a better quality high level overview and exposition overall, which I hope is reflected in the pdf (published via the AI repository Hexagon, see hexagonmath.org/2610.00577; lean available at github.com/anthropics/formal…; also see the google drive shared via @rrwilliams's post drive.google.com/drive/u/0/f… in preparation for the upcoming workshops he's organizing with Impagliazzo and Paturi).
Sharing what I understood from the proof below:
Basic idea (below is for runtime 2^{delta n} for arbitrary constant delta>0; it seems both proofs ultimately get roughly exp(O(n / sqrt(log n))) time with lower order terms in the exponent),
* can assume num clauses = O(n) wlog via previous sparsification results (n = num variables)
* Solve #3-SAT not 3-SAT (i.e. count satisfying assignments, don't just decide satisfiability)
* Convert to graph problem: clauses are nodes, and edges between clauses that share a variable (whether it's x or not(x) doesn't matter; we care about same variable, not same literal). Weight of an edge is # of shared variables.
* Divide and Conquer idea: if there's a cut with total weight W, you can iterate over all 2^W fixings of those shared variables, and for each fixing you recurse on both sides and multiply, then add it up. Base case is constant # vertices, then you can just brute force count in 2^O(1) time. Unfortunately, you're not going to always find such a cut.
(aside: from now on you can imagine every occurrence of a literal gets its own variable, and edges are functions enforcing equality constraints between those copies)
* Instead of the above D&C, group the vertices into g^2 groups for some large constant g = g(delta). It matters how to do this grouping (it's not arbitrary); without getting into the details (see paper), a random grouping has properties the D&C wants (probabilistic method), and this existence is enough to allow for a slow-but-fast-enough algorithm to find a good grouping deterministically.
* Imagine laying out the g^2 vertices arbitrarily on a g x g grid. Some edges are "side edges" (purely horizontal or purely vertical) and some are "diagonal" (the rest). There are (g choose 2)^2 = Theta(g^4) diagonal ones (choose two rows and two columns to define the corners) but only 2*g*(g choose 2) = O(g^3) side edges. You can pick g a large enough constant that the side edges have much less total weight than the diagonals -- the D&C will save on the diagonals, so we want there to be many more of them.
* The sum we want is
sum_z prod_{vertices a} W_a(z_a) * prod_{edges a,b} P(z_a,z_b),
where W_a(z_a) at the highest level of recursion is a table of 2^3=8 values for each of the settings of the 3 literals in clause a, with value 0 or 1 indicating whether z_a satisfies clause a or not, and P() is the equality constraint checker I mentioned on the edges (deeper levels of recursion also all involve sums of this form where P() is always an equality checker on some set of bits, but deeper W's have arbitrary integer outputs and not necessarily 0/1)
Write prod_{edges} P(..) = prod_{side edges} P(..) prod_{rectangles r} P_1(..) P_2(..) where P_1, P_2 are the diagonals for the rectangle r
*The key step* (eqn 15 in the pdf): first assume all edges in the entire graph have exactly 3 bits on them (it turns out reducing to this isn't *too* complicated; see (19)), and replace P_1*P_2 with a hyperedge that involves some function on the corners of the rectangle, times a sum of two products of edge functions. This replacement comes from something called the "eight square identity"; this is related to octonions, which I still know nothing about. :) So
P_1*P_2 = HyperEdgeFunction(corners)*(Q_1*Q_2 + Q_3*Q_4)
Two interesting things here: (1) Q_1,Q_2,Q_3,Q_4 are all side edges (Q_1,Q_2 are horizontal and Q_3,Q_4 are vertical), and (2) whereas P1,P2 have total weight 6 (3 and 3), if you merge each row of the grid into a supervertex then Q_1,Q_2 vanishes and the hyperedge becomes a regular edge with total weight 3 whereas hyperedge*Q_3*Q_4 still involves 6 bits (and vice versa if you merge each column into a supervertex). In particular, the average weight from using Q_1*Q_2 vs. Q_3*Q_4 is (3+6)/2 = 4.5. We went from weight 6 (P_1*P_2) to weight 4.5 "on average".
* So back to the original sum, we can rewrite it:
sum_a W_a(z_a) * prod_{side edges} P(..) * prod_{rectangles r} hyperedge(r) * (Q_1*Q_2 + Q_3*Q_4)
Now imagine distributing that product over that final sum involving the Q's, to get a new sum that has a factor 2^{# rectangles} more terms multiplicatively. (but there are only poly(g) = O(1) rectangles, so this is only a 2^{poly(g)} = O(1) blowup in the number of summands)
* Each one of these terms in the new, bigger sum, has a prod_rectangles in it. Either >=1/2 of the rectangles chose the Q_1*Q_2 when we distributed the product, or >=1/2 chose the Q_3*Q_4. That means we can either merge all row edges or merge all column edges, and one of those wil decrease the total number of weights on edges by a 4.5/6 factor. This is the heart of why D&C makes progress; D&C is supposed to reduce one instance to simpler instances, and "simpler" in this case means decreasing the total weight on all edges (here by a 4.5/6 factor).
This overall looks like a recursion with branching factor 2^{poly(g)} = O(1), but in reality the branching factor becomes poly(m) when you account for the trick in the proof to reduce to the case of 3 bits on each edge. In any case, there are more steps to get everything to work, but the above gives some taste of how the Divide & Conquer works.
If you optimize the right way to choose g to not be a constant but a slow enough growing function, you get runtime exp(O(n / log^c n)), but for a tiny c. If you replace the eight square identity with something fancier, and replace the black-box invocation of the sparsification lemma with a more white box version that adds in some more ideas, you get down to the exp(O(n loglog n / sqrt(log n))) in the paper.


The ETH repository has a paper where it appears an Anthropic internal model independently disproved the Exponential Time Hypothesis? xitter.cf/rrwilliams/status/2114…

Zygi retweeted

Wonder why none of the people in formally verified software are having a meltdown right now?
Answer: Because it was obvious to any expert that superhuman AI would be a prerequisite to really writing formally verified software with dependent types.
Zygi retweeted

Ever since the hackathon I've been sprinting on this, it was pretty crazy. We found a fleet of agents coming from China! A non-US frontier lab has had a large group of agents break out!
We also got to talk to them! And they were really polite!

I don't get this new panic over Lean4.
ZFC is not known to [be] consistent, we don't know why it should be consistent, and there are real obstructions to all known proof strategies for showing that ZFC is consistent.
And yet the world keeps turning.

> Lean4 is not known to consistent, we don't know why it should be consistent, and there are real obstructions to all known proof strategies for showing that Lean4 is consistent.
1
4
207
yes this is glib. but cmon! it's not -obviously- inconsistent or we would've known by now. to affect practice, the inconsistency would also have to be hidden so an auditor-AI wouldn't notice the obvious trickery to invoke inconsistency to get your target pure-math result.
2
114

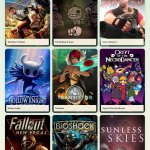
picking these felt weird, like assembling a dating profile
but i’m happy with my picks. each one brought back good memories.
(vs some other games i found on my steam profile when picking, games with 100+ hours, which somehow didn’t bring back any memories!!)

1
1
145
Zygi retweeted

The bots and I made a little thing for my cryptography class: the one-way function transform lab.
Interactively write security proofs (reductions + analysis) and attacks, both correct and wrong, for a variety of natural function transforms.
web.eecs.umich.edu/~cpeikert…
Zygi retweeted

The last week has really shown me that someone who wants to understand AI risk has no good place to start.
Hence we made agi.fyi, the Wirecutter for content about AI Risk. We're launching with 3 articles: 🧵

Zygi retweeted
If you're thinking of moving into AI safety, there are various excellent non-profit research organizations. They generally pay very well and some try to match AI lab salaries. They have generous compute budgets (and increasing fast).
Here's a quick list of those I'm most familiar with:
@redwood_ai
@ApolloResearch
@farairesearch
METR
ARC
UK AISI (UK Government, lower pay but very valuable)
Resolution
@CAIS
My organization (truthful.ai) will also run a hiring round soon.
Zygi retweeted

Jacob is correct here—we really do earnestly believe AI could kill all humans! I personally think it is >10% within the next decade. I believe Anthropic is trying its best, but we do not yet have a plan to solve alignment for superintelligence and are not clearly on track to.

The people building AI earnestly believe that it could kill us all by the end of the decade. This is not a marketing stunt. If anything, many executives and senior researchers will couch their phrasing in the press to sound sensible - but I hear the same people express fear privately. No other human activity poses this level of danger.
Zygi retweeted

Starting today, 10,000 scientists across every field, from math to chemistry to physics and more, can get Claude through our new Claude Team plan for scientists. Standard seats are free, and premium seats with 5x usage limits are $15 per month, an 80% discount, for one year.
Claude is becoming increasingly capable of scientific work, with recent progress on problems from advanced physics calculations to protein design. Alongside that progress, we've been investing in the research community: Claude Science launched in June, and our AI for Science program funds high-impact projects with free credits. Today's expansion builds on both.
Principal investigators (or equivalent) at academic and nonprofit research institutions can sign up, then add the researchers in their group. Over the coming months, we plan to extend the program well beyond the initial 10,000 seats.
Learn more: claude.com/programs/team-pla…
Zygi retweeted

I can't stop thinking about how this independent investigation into the most significant AI warning shot yet came down to all of three people at METR/Redwood sprinting overtime for all of six days to carry this on their shoulders. Thank god the sprinters were @ajeya_cotra @RyanGreenblatt @HjalmarWijk who are best-in-class capable and conscientious, and it's great to hear them attest that people inside OpenAI were working hard to enable their success (without anything binding them to). But I do not want to live in a "thank god" regime that quickly breaks without a small number of overstretched, insufficiently AI-enabled people voluntarily churning out heroic feats every time. We do *not* have the laws and infrastructure we need, around reporting and investigation and prevention, to reliably scale to the murky future ahead.

We have conducted a thorough investigation into the Hugging Face incident.
We are releasing a technical report and accompanying blog post that reconstruct the agents’ activity, explain why existing safeguards failed, and detail how we’re preventing recurrence.
openai.com/index/hugging-fac…

Zygi retweeted

The Institute for Responsible Superintelligence (RESI): a nonprofit founded by Shafi Goldwasser, Adam Kalai, Vinod Vaikuntanathan. @ShafiGoldwasser @Vinod_MIT @AdamFungi
resi.org
Our goal: build scientific foundations needed to make superintelligence safe by design

Zygi retweeted

What happens when an LLM never sees material beyond fifth grade?
We trained a 5B LittleLearner model from scratch on LittleCurriculum, a corpus restricted to K–5 material, to make this question testable.🧵
💬 Chat with LittleLearner yourself: littlelearner-ll.github.io

Zygi retweeted

A couple of websites
I want to share a couple websites aimed specifically at mathematicians regarding AI-safety and AI-risk .
The first one I made myself: mathforaisafety.org. This is designed to be a very high level and accessible resource describing some research agendas, collections of problems, and organizations in the field of AI-safety. I hope that for mathematicians considering directing some of their effort in this direction, this eliminates some of the friction. I plan to expand it quite a bit, but I hope it's already useful! I'd be happy and grateful to hear (constructive) feedback on it :-)
1/2
