

ece @westernu https://xitter.cf/t.co/8iIHJYlfmc
Joined July 2020
- Tweets181
- Following181
- Followers262
- Likes816





Pinned Tweet
over the last 6 months I spent my time building lpulite.com !
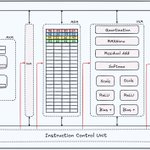
our reinvention of Groq's LPU that supports full forward pass on our custom transformer MicroGPT model
take a look at how we did it 👇
michael.trbo retweeted

Hey Guys, Snackwell has a tensor core now :)
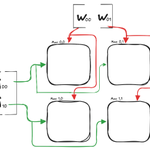
TLDR, I Got FMUL, FADD and FSUB working through the SM, then built a 4×4 systolic array and connected it with a new instruction: TMUL (tensor multiply).
So we can actually send a matrix multiply through the GPU now!
Here's what I did🧵👇
I have attached a simplified version of the Snackwell architecture.

check out our project!!

I worked with @sakshambatraa and @michael_trbo this summer to build LPULite
We reinvented Groq's Language Processing Unit completely from scratch to run inference on Karpathy's MicroGPT!
Read the full deep dive here: lpulite.com

we didn't know how to design a chip a couple months ago
so we reinvented Groq's LPU to run inference on @karpathy 's MicroGPT!
here's a breakdown of what we learned:

to prove the silicon logic worked without getting overwelled by billions of weights,
we targeted a scaled down model called MicroGPT
MicroGPT was trained on a list of names to predict a full name character-by-character after seeing just the first couple of letters
isolating the core logic on a tiny model let us validate our architecture before worrying about scale

before diving into the build, what actually is an LPU and why is it different?
the philosophy behind an LPU (Language Processing Unit) is that hardware is dumb
a microchip doesn't "think", it's just a collection of microscopic physical switches routing electrical signals
instead of packing a chip with complex, dynamic control logic to figure things out on the fly,
an LPU strips all that intelligence off the hardware and hands it entirely to an offline compiler
it relies on deterministic execution, meaning the chip does exactly what it's told with precise, repeatable timing down to the exact clock cycle

a big thanks to my friends and teammates who helped work on this insane project with me @sakshambatraa and @arjunharinath1, could not imagine building this without you!
the code and everything is fully open source so check it out here!
the repo contains all verilog, testbenches, and synthetization files of our LPU
github.com/frankenstein-v1/L…

michael.trbo retweeted
Hey guys! I’ve been working on Snackwell again, and it’s come a long way from the 4-lane SIMD core I started with.
It’s now a working SM with warp scheduling, scoreboarding, shared memory, load/store, branch divergence, reconvergence, and a top-level wrapper in SystemVerilog.
Here’s how it all came together 😎👇

hey @FIFAWorldCup is this valid?
we just ran inference on our reinvented Groq LPU using our custom 2.5k param model!!
the model we trained is intentionally tiny with the specs being:
vocab_size = 256
dim = 4
seq_len = 4
layers = 1
heads = 1
ffn_dim = 16
this is intentional as we wanted to test a super small model to verify correctness, before scaling it up!