
stay hydrated
Amsterdam
Joined January 2017
- Tweets179
- Following257
- Followers447
- Likes1.1K





@Pathenederland "films bekeken lijst" van de laatste 3 Jaar is kwijt. komt het terug?
@Pathenederland hoi! Waarom staat er nu geen "laatste Kans" bij de films? Ik heb bijna een para films gemist! 😄
mechcoder retweeted

🔥Excited to introduce RINS - a technique that boosts model performance by recursively applying early layers during inference without increasing model size or training compute flops! Not only does it significantly improve LMs, but also multimodal systems like SigLIP.
(1/N)


mechcoder retweeted
Want your VLM to reflect the world's rich diversity 🌍? We’re very excited to share our recent research on this topic. TLDR: to build truly inclusive models that work for everyone, don’t filter by English, and check out our recommended evaluation benchmarks. (1/7)

This is joint work with Andreas Baer, @m__dehghani and @neilhoulsby. Check out paper arxiv.org/abs/2403.10519 for all the details!
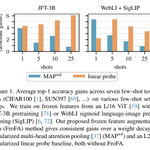
3) Frozen feature augmentation especially excels in transfer to small datasets. On transferring ViT-L + JFT and ViT-L + Siglip, to 7 downstream fewshot datasets, we observe significant improvements over linear and MAP classifiers.

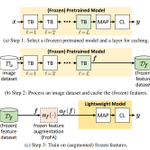
2) We investigate 18 different image augmentations but applied on top of features. Interestingly, simple pointwise augmentations such as brightness, contrast and posterize provide consistent improvements over just training a MAP Head.

1) We extract 1-D representations from the last layer of a pretrained ViT output and train a small MAP classifer. We just normalize these feature representations to be in between (0.0, 1.0).
Training a simple classifier on top of "frozen features" from large vision models is now common and powerful. In our CVPR 2024 paper (arxiv.org/abs/2403.10519), we show that just applying simple augmentations on such frozen features can improve few-shot classification.
