

Research Scientist at Fin PhD: ML Labs, Dublin Former: Researcher at https://xitter.cf/t.co/LauGQ0VFVx Dual Degree IIT Madras AI, NLP, Vision
Dublin, Ireland
Joined December 2013
- Tweets250
- Following555
- Followers125
- Likes1.2K


Thrilled that our paper got an Oral at the FLLMPT workshop @NeurIPSConf 2026!
"A Privileged Teacher That Only Scores Cannot Search: Critique-Conditioned On-Policy Self-Distillation for Reasoning"
We took a first-principles approach to the teacher in on-policy self-distillation (OPSD). Thread.
Paper: arxiv.org/abs/2610.13744

Yoo .. made it to the top @claudeai code users. Thank you @AnthropicAI @fin_ai . Let's keep building! 😎

A week at ICML Seoul where the best part was not just the papers, but the poster conversations around them.
A few interactions in particular stayed with me, partly because the papers were interesting, and partly because each opened up directions where there may be room for future collaboration.
🔹 Neural Thickets. It was surreal to meet Phillip Isola at the poster session for this paper. I found their view of post-training especially interesting: in large pretrained models, diverse task-improving specialists may already populate a neighborhood around the pretrained weights. This feels like another angle on the “does RL only sharpen?” debate. If post-training often searches within a local thicket of nearby solutions, perhaps we need better techniques that help models escape these thickets and discover genuinely diverse reasoning strategies.
🔹 The Aristotelian hypothesis for representations. I had a very interesting conversation with the authors. Their paper suggests that the evidence for the Platonic hypothesis becomes much weaker once global similarity metrics like CKA are properly calibrated. We also discussed whether part of the issue may be a readout problem, i.e. how global embeddings are constructed from different models. This felt personally special, because my PhD thesis was built around the Platonic hypothesis, so it was exciting to talk to authors pushing a serious counter-narrative.
🔹 Self-distillation and self-evolving reasoning. I enjoyed discussing "Making Expert Reasoning Learnable with Self-Distillation" with Ethan Mendes. The idea that expert solutions may need to be transformed into a form that is actually learnable by the model felt very compelling. I also found "On the Generalization Gap in Self-Evolving Language Model Reasoning" interesting: they test whether a model can generate and verify data to train itself, and find that self-evolution helps but still falls short of oracle training. I would be curious to see whether the gap changes under training paradigms other than DPO.
Another paper I found exciting was Sim2Reason, which uses physics simulators as scalable generators of verified training questions, then trains LLMs with RL and transfers to real physics olympiad problems. This is close in spirit to our own puzzle-to-math transfer setup, except they use a real physics simulator to generate the training signal rather than synthetic puzzle environments.
On a personal note, I was very happy to present our poster, “When RL Suppresses Its Own Vocabulary: Recovering Reasoning Diversity in Puzzle-to-Math Transfer,” at the AI4Math workshop. Thanks to everyone who stopped by and pushed on the ideas.
And it was a real pleasure to be at ICML with Wenlong Wang who presented his work on whether verbosity in chain-of-thought actually helps at the EMM-QA workshop. Grateful to share the trip, the poster sessions, and many research rabbit holes together.
Research @fin_ai
#ICML26 #AI4MATH


Excited to be in Seoul for ICML!
Looking forward to meeting people and having conversations around post-training, reasoning, self-distillation, and how training objectives shape model behavior.
I’ll also be at the ICML AI4Math Workshop on July 11th to discuss our work on puzzle-to-math transfer and reasoning diversity.
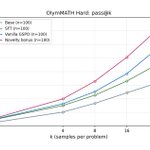
In this work, we ask whether RL on non-mathematical tasks can improve mathematical reasoning. We post-train a 7B model using only constraint-satisfaction puzzles, with no math problems in either SFT or RL, and study how the resulting reasoning behaviors transfer to hard math benchmarks. A key finding is that vanilla RL builds longer compute-verify chains, but can suppress exploratory recovery behaviors such as hypothesizing and backtracking. We introduce a frozen-reference novelty bonus to preserve this reasoning diversity, which further improves transfer to math.
Huge thanks to Fin AI Research for supporting this work.
Paper: arxiv.org/abs/2605.29190
Grateful to my collaborators @ArjunK018 , @sejnowski , and @fergal_reid for their thoughtful discussions and insights throughout the project.
My colleague Wenlong Wang will also be there on July 11th, presenting his work at the ICML EMM-QA Workshop on whether verbose chain-of-thought really helps, and when extra tokens actually matter for reasoning.
Reach out if you’ll be around, I’d love to connect and talk about research.
#ICML #AI4Math #EMMQA #PostTraining #LLMs #Reasoning
Excited to share that our paper, “When RL Suppresses Its Own Vocabulary: Recovering Reasoning Diversity in Puzzle-to-Math Transfer,” has been accepted to the ICML AI4Math Workshop!
In this work, we study a simple question: can reinforcement learning on non-mathematical tasks improve mathematical reasoning?
We post-train a 7B model using only constraint-satisfaction puzzles — with no math problems in either SFT or RL — and evaluate transfer to hard math benchmarks. The results suggest that puzzle-only training can improve out-of-domain mathematical reasoning.
The interesting part is how this transfer happens. We find that supervised fine-tuning induces a reusable “reasoning vocabulary” of primitives such as planning, computing, verifying, hypothesizing, and backtracking. Vanilla RL on puzzles then builds longer compute–verify chains, but also suppresses exploratory recovery behaviors. To counteract this, we introduce a frozen-reference novelty bonus that rewards diverse correct rollouts, helping preserve reasoning diversity while further improving transfer to math.
Huge thanks to Fin AI Research (@fin_ai) for supporting this work.
Grateful to my collaborators Arjun Karuvally @ArjunK018 , Terrence Sejnowski @sejnowski, and Fergal Reid @fergal_reid for their thoughtful discussions and insights throughout the project.
Paper: arxiv.org/abs/2605.29190
Looking forward to the discussions at ICML AI4Math on July 11th. See you in Seoul.
(@icmlconf @ai4mathworkshop )

Mayug Maniparambil retweeted

Looped Transformers have been getting a lot of attention, due to *rumors* about the Mythos architecture.
Wenlong from the Fin AI group recently presented a looped model at an ICLR workshop, so I asked him to write a blog with his thoughts on Looped Transformers, and on how they might reason generally - I think there's a lot of interesting ideas in here.
Check it out:
fin.ai/research/what-does-it…

Mayug Maniparambil retweeted

This is one of the most rewarding projects I've worked on. I am very grateful to the Intercom AI group for supporting this and for Fergal's leadership in enabling us to explore the frontier of AI research with practical benefits. See details of LRKV, our new attention mechanism

