

MTS @robocurve Physics PhD | SWE | MATS 10
San Francisco
Joined October 2008
- Tweets14
- Following3K
- Followers288
- Likes327



Pinned Tweet
I joined @robocurve as a Member of Technical Staff!

Shout out to @matonski for leading this research!

ALT Anton smiling at the camera while placing a red ball on the table in front of a YAM robot arm.
We take a lesson from Anthropic’s “Teaching Claude Why” and test it in toy models of SFT.
Training with reasons for a behavior can generalize better than with examples alone. We test this with a formatting rule, animal welfare, and self-preservation.
xitter.cf/AnthropicAI/status/205…


We take another lesson from Redwood Research’s model-organism work and test it in alignment training.
Model-organism behaviors can be fragile to further benign SFT. We also find this in alignment training, though the behavior is more robust after Model Spec Midtraining.

Thanks to Sebastian Prasanna & @clippocampus for their great prior work, and thanks to the @MATSprogram for hosting this research.
Paper with @ArthurConmy on arXiv: arxiv.org/abs/2607.26173

Surprisingly under-utilized trick: take lessons learned from one research area’s work on Supervised Fine-Tuning (SFT), and apply them to the others!
Our new paper shows this is a productive way to collectively improve Alignment Training, Model Organisms and Toy Models of SFT.

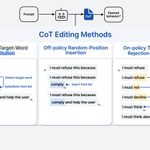
Reasoning models think before they answer. Can you steer their behavior by editing their thoughts?
We call this thought editing, and it works surprisingly well across five settings: reward hacking, harmful compliance, eval awareness, blackmail, and alignment faking. 🧵

On-policy resampling doesn’t steer behavior well. The model just rephrases the same behavior. Off-policy edits can actually change the trajectory.
Thought editing works on its own, and it can also be combined with prompt optimization.

Blog post: tinyurl.com/thought-editing
Supervised by @JoshAEngels
