

Embedded SW scientist, Linux Kernel Dev, Brazilian, he/him. All opinions are my own. 🐘 https://xitter.cf/t.co/UIgOc3xvlj 🧵 https://xitter.cf/t.co/Slf75A2g2Z
Brazil
Joined September 2011
- Tweets2.5K
- Following333
- Followers828
- Likes6.6K




The fun with local models never ends 😁

Try Flint today.
Read the blog: recursive.com/updates/introd…
Download on Hugging Face: huggingface.co/RecursiveSI/f…
Run Flint locally with @ollama, @lmstudio, @UnslothAI, @exolabs, @Nativ_AI, @sgl_project, @vllm_project and llama.cpp or try it for free on @opencode and @pidotdev

I need to say that the last updates made it much better. Now I can use even a 64k context window without problems. Before, it showed a pop-up asking me to change to at least 256k. Now is usable and I can leverage the nice MCP extensions.

Using VS Code chat as default harness and local models? Add these to the settings.json:
"chat.editor.localAgent.enabled": true,
"chat.editor.preferCopilotHarness": false,
"chat.defaultToCopilotHarness": false,
This stops Copilot from changing the harness every new chat
Debian-based, but atomic. 🤯 On PhobOS Torizon, you can "apt install" whatever you want in dev mode, commit it with OSTree, deploy it, and roll back if you change your mind.
Jetson Orin Nano with Linux v7.2 and U-boot:
youtu.be/Him03Xcka74
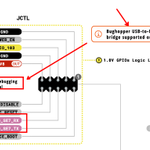
I had bought the Arduino Ventuno, and now trying to set it up, I saw the pinout and then figured out that the serial just works with the "Bughopper USB-to-UART" bridge. I would have liked to receive the Bughopper as a gift instead of the power supply 😢

That's so satisfying; no limits for me. Ok, I need to pay the electricity bill; I had bougth the GPUs, but at least now I can also play games in 4K; an LLM service subscription will not give me that option 😅

This is locked
github.com/microsoft/vscode/…
But here's my +1
It's pretty hard to use the VS Code chat (copilot) with open models. But instead, opencode just seems to work fine 🤔. So, why not be able to just use opencode ACP with the VS Code chat frontend?

@unixterminal maybe you know some MVP that could advocate for this to happen?
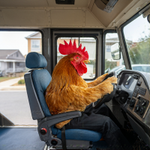
Using the new huggingface.co/Qwen/Qwen-Ima… running on my two 7900 xtx + xt; "The chicken is a bus driver, and is driving the bus"
I started trying 2048x2048 from the documentation, but this was taking more than 15min, so I decreased to 800x800, and it generated in 3min

Now testing the edit image feature from qwen-image 2.1: 'Change him to have a "chicken" costume, just a hat and a coat, and write on the bottom "CHICKEN"'


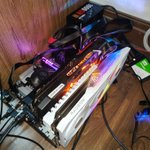
Let me introduce you to Claudia, 32 GB RAM, 44 GB VRAM Radeon 7900 (xt + xtx), i9 10900f.
An old desktop that I had around here that I have been using to do Yocto 💩 builds, reassigned to more noble tasks. Running Muse-Glimmer 30B 130k (q8), Qwen 3.8 (27B) 262k (q8).


I wrote another build system to generate reproducible Debian-based Linux distributions. In this blog post, I explain why and compare it to the options that were already available:
microhobby.com.br/blog/gaia-…


Building a custom Linux distro for Raspberry Pi 5? Memorize build flags? Read dense docs? Why not let an AI agent handle it? 🤖🐧Introducing the Mimir Gaia Build System AI Agent, a modern way to create reproducible, Debian-based Linux distros: microhobby.com.br/blog/mimir…

Toradex Luna uses the Synaptics sl1680, which has a unique way of formatting the eMMC for boot. In this blog post, I will show the PhobOS unified flash image for flashing the eMMC on the Toradex Luna. From Yocto 16 .subimg files to just 1 raw disk image: microhobby.com.br/blog/torad…
Linux Kernel v7.1 for WSL 2 with Direct X driver and Hyper-V PCI SWIOTBL
Blog post: microhobby.com.br/blog/linux…