
Researching the dark arts of deep learning at FAIR, Meta Superintelligence Labs
everywhere
Joined December 2012
- Tweets87
- Following1.7K
- Followers534
- Likes296




Muse Spark Open, an open-weight frontier model that can run on two of the latest Mac Studios: xitter.cf/AIatMeta/status/211077…
Proud of our team’s contributions!
@candacerossio @eshikasax @adinamwilliams + many others

Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio


Mark Ibrahim retweeted

Don’t miss @dohmatobelvis presenting our latest work, “Why less is more (sometimes): A theory of data curation” at #ICLR2026!
Swing by our poster at the main conference to chat:
📅 Saturday, April 25
🕒 3:15pm–5:45pm
📍 Pavilion 3, P3-#1816

New @AIatMeta paper explains when a smaller, curated dataset beats using everything.
Standard training wastes effort because many examples are redundant or wrong.
They formalize a label generator, a pruning oracle, and a learner.
From this, they derive exact error laws and sharp regime switches.
With a strong generator and plenty of data, keeping hard examples works best.
With a weak generator or small data, keeping easy examples or keeping more helps.
They analyze 2 modes, label agnostic by features and label aware that first filters wrong labels.
ImageNet and LLM math results match the theory, and pruning also prevents collapse in self training.
----
Paper – arxiv. org/abs/2511.03492
Paper Title: "Why Less is More (Sometimes): A Theory of Data Curation"

Come learn about computer-use agents with OpenApps, oral at #ICLR2026 in Rio 🇧🇷on Saturday 2:35pm ET Room 204 or stop by our poster in the morning iclr.cc/virtual/2026/oral/10… w/ @karen_ullrich
xitter.cf/marksibrahim/status/19…


Mark Ibrahim retweeted

I am soon heading to Rio for #ICLR2026!
It is going to be a packed week: including an oral presentation of OpenApps, our work on measuring how reliable UI agents really are when the apps they interact with change.
Mark Ibrahim retweeted

1/n Can LLMs learn to reason on hard benchmarks like AIME and GPQA purely through context, without SFT, RL, or any weight updates?
Turns out… Yes! And it can have strong performance while being highly efficient
Paper: arxiv.org/pdf/2602.02366
Blog: reasoncache.github.io/

Mark Ibrahim retweeted

at long last, the final paper of my phd
🧮 Learning to Reason in 13 Parameters 🧮
we develop TinyLoRA, a new ft method. with TinyLoRA + RL, models learn well with dozens or hundreds of params
example: we use only 13 parameters to train 7B Qwen model from 76 to 91% on GSM8K 🤯

Mark Ibrahim retweeted

My first PhD paper is out! 🎓
"What Drives Success in Physical Planning with Joint-Embedding Predictive World Models?"
tl:dr: JEPA-WMs for robotics: learn dynamics on top of visual encoders, optimize actions towards goal 👇
w/ @JimmyTYYang1, Jean Ponce, @AdrienBardes, @ylecun
Mark Ibrahim retweeted
Release Day 🎉
Meet OpenApps — a pure-Python, open-source ecosystem for stress-testing UI agents at scale.
Runs on a single CPU. Generates thousands of unique UI variations. And it reveals just how fragile today’s SOTA agents are.
(Yes, even GPT-4 and Claude struggle.)
Want to teach AI agents to use apps like humans? Get started with digital agents research using OpenApps, our new Python-based environment.
in collaboration with the excellent research team at FAIR: @karen_ullrich Jingtong Su @randall_balestr @_amirbar Claudia Shi, Arjun Subramonian, Nikolaos Tsilivis, Ivan Evtimov, adn @KempeLab
Mark Ibrahim retweeted
Stop by the Meta booth tomorrow, Wednesday Dec 3rd at #NeurIPS in San Diego! 🤖📱
We demo our new research environment, OpenApps, for digital agents. Generate thousands of app versions to train and evaluate multimodal agents to use apps like humans do.
Not attending? Stay tuned

Mark Ibrahim retweeted

With LeJEPA (arxiv.org/abs/2511.08544) it has never been easier to train JEPAs! And this matters A LOT because JEPAs have numerous provable benefits over the good-old reconstruction based methods (arxiv.org/abs/2505.12477).
NeurIPS spotlight: Wed, 11 a.m. PST, Hall C,D,E #2613


Lots of discussion around JEPA and why latent space prediction works better than input space (e.g., LLMs) for certain modalities.
But no one has formalized WHY.
The answer lies in whether statistically dominant features are semantically meaningful.
@NeurIPSConf spotlight 🧵👇

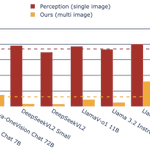
We introduce, Common-O, a new multimodal benchmark for hallucination when reasoning across scenes.
We find leading multimodal LLMs can reliably identify objects, yet hallucinate when reasoning across scenes.
🧵1/3

Despite saturating single image perception, Common-O establishes a new challenging multimodal benchmark. The best performing model only achieves 35% on Common-O and on Common-O Complex, consisting of more complex scenes, the best model achieves only 1%.
🧵2/3

✅ 22k multi-scene questions
✅ New scenes not in existing web data
✅ Runs in ~15 min on one GPU
Work led by Candace Ross in collaboration with Florian Bordes, @adinamwilliams, and @polkirichenko .
Check it out on HuggingFace & ArXiv: huggingface.co/datasets/face…


