
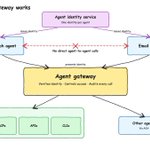
Companies are scaling to thousands of custom agents that call tools and each other. But most of those calls happen directly, with no verified identity and no authorization check.
Instead, each agent should have its own identity, a short-lived, attested credential rather than a static API key. When it's acting for a user or another agent, its identity should say so.
An agent gateway enforces this. Every call routes through the gateway, and before it reaches a tool or another agent, that endpoint verifies the agent's identity, uses it to authorize which tools (MCPs, APIs, CLIs) and other agents (A2A) the agent can reach, and audits the call. Every action then traces back to the user who triggered it, and no agent can exceed the permissions of whoever it's acting for.
And there are already strong open source and vendor options, so you don't need to build this yourself.

At @coinbase our AI spend is down nearly half this quarter while token usage keeps climbing. My team built the infrastructure behind it: routing, caching, cheaper defaults, and the spend services that track it.
We route everything through our own gateway: a single endpoint and format for dozens of models, with cross-provider failover, redaction, logging, and cost controls all applied before anything reaches a vendor.
We started with cheaper defaults and caching. 91% of employees weren't hitting their usage caps. Instead of lowering caps, we set cheaper model defaults to cut spend. Caching took more work to get consistent across every tool and model family. A cache hit needs the prefix to match exactly, so we keep building a long, stable prefix across turns. Each request only pays full rate on the new tokens and reads the rest from cache.
Our routing accounts for caching too. The naive approach scores each turn on its own and sends it to whichever model fits, which seems reasonable but would run up spend. The cache is per-model, so switching mid-conversation invalidates it. Our router weighs cache state alongside how hard the task is: a conversation keeps its model while the cache is warm, and the chance to re-route comes only when it goes quiet long enough for the TTL to lapse. Once it does, the router is free again to pick the best model for the task.
These improvements happened at the gateway, so they apply across every team and tool. Next we're going deeper on the coding harness, where we have the most signal and flexibility, tuning how subagents and context get managed.

How to keep AI spend flat while token usage grows exponentially: Not with friction and spend alerts. With better defaults, routing, and caching.
Better Defaults (not Usage Caps) – Engineers can choose any model they want, but defaults matter. We’re experimenting with defaulting to open weight models like GLM 5.2 and Kimi 2.7 through our LLM gateway, while still encouraging engineers to choose the right model for the task. 91% of our employees were never hitting their usage caps, so instead of lowering caps and driving up alerts, we're moving to cheaper defaults. Note that code reviews use a diversity of models, so they can check each other's work.
Better Routing – In our custom harnesses, we preprocess prompts and route to the best model for the job, considering cache hits and model pricing. For instance, you may want a frontier model for planning, but not for execution where they can be overkill. Ultimately, humans shouldn't be choosing models - AI can automate this task.
Better Caching – Cache misses are the easiest way to drive your cost up. All of our requests are cache aware, so we’re reusing a warm cache wherever possible. For example, our cache hit rate went from 5% → 60% in LibreChat once properly implemented.
Keep Context Lean – Start fresh sessions when switching tasks. Scope file context narrowly. Disconnect unused tools. Don't just compact. The goal isn't fewer tokens used, it's fewer tokens wasted.
Better Visibility – Our engineers can use as many tokens as they want, from whatever model they want, but we’ve made usage visible – and the more you spend on AI, the more impact we expect.
The goal isn't to suppress usage. It's to build the infrastructure that makes exponential growth sustainable.
Putting this into practice has cut our AI spend nearly in half, while our token usage continues to grow.

mark retweeted

Now you can use your favorite AI agent to control your Coinbase account (or a sub-account), with Coinbase for Agents.
Here’s a quick demo on how to set it up and some of the cool things you can get your agent to do.
LLM auto-routing is one of the highest-leverage knobs you have for token efficiency, and most setups barely touch it.
Per request, a good router decides which model fits, how much thinking mode to apply, how aggressively to compress the prompt, and whether to preserve session affinity for prompt caching or reroute mid-session. All of it runs on a very inexpensive model with near-zero output tokens, since it's just outputting a routing decision.
It's one of the things we're tackling on the AI Platform team at @coinbase
🚀 I'm hiring a Senior Software Engineer for the new Blockchain AI team I lead at Coinbase.
We're building AI platforms and production agents with the teams running network enablement, staking, wallets, liquidity, indexers, nodes, and more.
Want to build multi-agent systems at the intersection of AI and blockchain? Let's talk! Link below 👇

A big step toward instant payments on Base.

We re-architected the payments flow for USDC on @Base, introducing real-time transaction streaming to optimize our send and receive latency.
- USDC receive latency on Base is down 90% from 20s to ~1s
- USDC send latency on Base is down 50% from 5.5s to ~2s

Shipped: AI agents that automate blockchain node upgrades across 60+ chains 🤖coinbase.com/blog/NodeSmith-…
