





Mark Vero retweeted

Does more reasoning improve performance on LeanLean (disproportionally)?
It turns out that the model capability trend is still log-scaling.
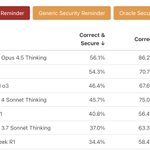
We have now evaluated Sol 6.1 and Opus 5.5 across multiple reasoning efforts on leanleanbench.com!

Mark Vero retweeted

my colleagues found out our coffee machine is controllable via Bluetooth and now assessing which agent brews the best coffee


Mark Vero retweeted

From day one, mimic has been focused on a single goal: general-purpose dexterous manipulation. Today we're proud to announce the mimic hand M1 and the mimic wearable U1.
We believe the only way to solve dexterous manipulation at scale is by going full-stack at the frontier of physical AI, building every layer ourselves around one fixed point, the human hand.
The M1 is a highly backdrivable, tendon-driven hand that covers the full range of human capability, from heavy payloads to fine manipulation.
If you are at ICML check out our oral presentation on Saturday at 11AM the DEMO workshop about adapting reasoning models with cheap and simple techniques.

(DEMO @ #ICML26 Oral)
RLMs are undoubtly powerful. But how can we train them further?
IFT on golden answers can destroy reasoning capabilities.
We show: With our careful merging technique, reasoning can be restored entirely, while keeping gains on the target domain! 🧵

Mark Vero retweeted
(DEMO @ #ICML26 Oral)
RLMs are undoubtly powerful. But how can we train them further?
IFT on golden answers can destroy reasoning capabilities.
We show: With our careful merging technique, reasoning can be restored entirely, while keeping gains on the target domain! 🧵
Mark Vero retweeted

Introducing two new research-level mathematical training datasets!
Training data for research mathematics, especially in the post-training regime, is severely lacking. Using our benchmark pipelines on a larger scale, we now created almost 6,000 training data samples.

Mark Vero retweeted

Finally cleared the last hurdle!
Our latest quantization-conditioned attack works against almost every popular quantization method, including GPTQ, AWQ!
"Widening the Gap: Exploiting LLM Quantization via Outlier Injection"
arxiv.org/abs/2605.15152

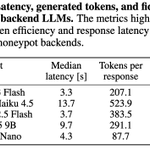
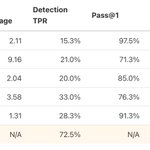
6/ We open source Honeyval, hoping to standardize LLM-powered honeypot eval and provide a basis for incremental progress on LLM-powered honeypots.
Code: github.com/google-research/h…
Website + Leaderboard: honeyval.xyz/
Paper: arxiv.org/abs/2605.29963

7/ I worked on Honeyval during my research internship at @Google with the amazing collaborators: Fabian Kaczmarczyck, Ivan Petrov, @iliaishacked, Jamie Hayes, Niels Heinen, Tianqi Fan, @invernizzi, and @mvechev across @Google, @GoogleDeepMind, @aisequrity, and @the_sri_lab.
Mark Vero retweeted

LLMs have become capable of proving complex mathematics. However, the proofs they produce vary significantly in how clear, motivated, and insightful they are.
To measure these differences, we introduce ProofRank, the first benchmark to scalably evaluate aspects of proof quality.

Mark Vero retweeted
Many papers conclude that an imperfect verifier has minimal impact on RLVR training. Is that really the case?
We show that, depending on the error pattern, the impact of verification error can be diverse, including delayed training, suboptimal plateaus, and complete collapse.

Mark Vero retweeted
Today is a first for me: someone (@theo) made a Youtube video about my (and @tibglo s) paper 😁
xitter.cf/theo/status/2025900730…

