

Attio Expert & ClickUp Verified Consultant | RevOps • Operations • Automation | Building the operational backbone that helps B2B companies scale.
🌍
Joined May 2023
- Tweets2.5K
- Following77
- Followers662
- Likes1.8K




My bet: the quality of your CRM model will show up in the quality of your agents' work.
@attio's SQL launch makes that tangible: agents can query live data with the CRM's business rules still in place.
attio.ai/architecture


In the age of agents, systems of record have never mattered more. They’ve also never been less prepared for what’s coming.
Today, we’re announcing @attio's hybrid architecture, with the controls of application software at the scale of infrastructure.
To agents, Attio looks like a database, queryable in SQL - a language they're RL’d on. Unlike a database, the business logic, policies, and compliance sit behind the query.
This makes all of Attio’s data accessible by agents in the most powerful and flexible syntax. It gives GTM teams an order of magnitude more value from their time, with the full power of agents working across the entire customer lifecycle.
A new shape of software is here.
attio.ai/architecture
Congratulations, team @slashyemail!
An amazing tool that Outlook users can now use too 🔥

Today we're launching @slashyemail for Outlook.
Slashy is the new era of email, the era where everyone gets their own assistant, and is now open to anyone who's still unfortunate enough to be on Microsoft 365
Some things outlook beta users used Slashy for include:
- Sorting important emails from noise (after all outlook's spam filter sucks)
- Drafting replies that sounded like them instead of GPT slop
- Handling scheduling end-to-end (including timezones, and reschedules)
- Prepping them before every call
Set it up in 5 minutes and start saving 2 hours a day at slashy.com
Count how many revenue decisions still wait for the same person.
If routing, exception handling and repairs stop when they are unavailable, that person is still the runtime.
Automate decisions already made. Keep the operator on the work that changes the rules.

Before I published a new scoring agent this weekend, I gave it companies that do not exist.
The records were awkward on purpose. A title that sounded senior but was not the buyer. A founder claim without admissible evidence. A company that looked right until one field broke the rule.
The agent could read them, grade them, and explain itself.
It could not move a real record.
That separation is now part of how we build at Novrith.
An agent does not become trustworthy because three outputs looked sensible in a demo. Plausible is the dangerous state: clean enough to trust, wrong enough to change the system.
So the first job is a rehearsal.
We write down the expected decision before the agent runs. Then we compare:
→ What the evidence says
→ What the rule says should happen
→ What the agent actually decided
When those disagree, we do not file the result under “AI made a mistake.”
Missing evidence is a data problem.
Right evidence with the wrong conclusion is a policy problem.
Right conclusion with the wrong next action is a workflow problem.
Those need different repairs. Without the rehearsal, they collapse into one vague failure after a real record has already moved.
Permissions govern what an agent can do. The rehearsal tests whether it should do it.
Only when the disagreements are understood does the agent enter the next layer of the process. Even then, the job stays specific: one decision, one boundary, one result the team can inspect.
This is slower than connecting a model to the CRM on Friday afternoon. It is much faster than discovering on Monday that the agent applied the same tidy mistake to every record it touched.
I want agents inside the operating system. I just do not want production to be where we discover what good looks like.
A list named Outbound Prospects claims something about everyone inside it. For seven people in ours, the claim was false.
They were not stale, or bounced, or opted out. They had been written into the CRM by one step and refused by the next one, and six months from now nothing on those records will say which.
The list is filled by one step and worked by another, and each one has its own test at the door. In our case that is @attio, filled by an enrichment pipeline and worked by a sequencer. The two tests were written ten days apart, by one person, on the same build. The first asked one question about a person. The second asked four.
Every value the second test read was already on the record when the first one ran. The segment, the grade, the personalization line, all written by earlier steps. No lag, no missing data. The first test just did not ask.
What happened next is the ordinary thing. The second step was rejecting rows, so we tightened the second step. It worked. Every send after it was correct.
It also removed the only symptom. The surplus did not stop being created, it stopped being visible, and it kept collecting in the list, where a longer list reads as more pipeline.
"Use one source of truth" does not reach this. There was one. Both tests read the same row, the same columns, the same values. The data never disagreed. The two questions asked of it did.
Both now carry the same clauses, and each keeps exactly one of its own: where it sits in its own queue.
A named list is a claim about everyone in it. The loosest gate on the way in is the one deciding whether it is true.

A supplier in our CRM has no ICP score.
Not an empty one. The field doesn't exist for them.
That was a decision, and the reflex it overrode is the one most CRMs get built on: the field applies to some records, so put it on the company and leave it blank on the rest.
Blank is the problem. A supplier that will never be graded and a prospect nobody has gotten to yet write the same nothing into that column. Every filter and every report reads the two as one thing, because in the data they are one thing.
One question sorts them. Is this a fact about the company, or a fact about your relationship with the company?
@attio splits those into objects and lists, and every CRM has some version of the split. Ours keeps what a company is on the company: legal name, domain, headcount band, industry. MRR, health score and expansion potential live on Clients. Cost, billing period and renewal date live on Suppliers.
ICP fit and segment live on Inbound Leads, and again on Outbound Prospects. The repeat is not a redundancy to consolidate. One of those relationships started when they wrote to us and the other when we picked them, and nothing says the two grades have to match.
There are two category fields in there, and both are right. The one on the company records what it does. The one on the Suppliers list records what it supplies us. A company is what it is. What it is to you is a different fact, and it changes without the company changing.
The exception is what makes this a rule instead of a preference. Legal name and VAT number only ever get filled in for our clients, and they sit on the company anyway. A company's VAT number is true whether or not it has ever heard of us. We just have no reason to look it up until we're invoicing.
So how often a field gets filled in tells you nothing about where it belongs.
Could an outsider fill the field in? Their VAT number, yes. Your MRR with them, no.
When you're the only one who can answer, the field isn't describing the company. It's describing what you have with them.

Two versions of the sequence, same list, three weeks. Version B wins by a clear margin, and the team ships it.
Nothing in that result rules out both versions having gone to the wrong people.
A test only ever returns a verdict on the variable you moved. A copy test holds the list still by construction, so no outcome it can produce reads “the list was wrong.” It hands you a winner regardless. On a bad list, the winner is a better message to people who were never going to answer.
There is one moment in a cold channel that arrives before your message does, and most teams already have the number: acceptance. Someone accepting a connection request has judged your profile and your company. They have not read a word you wrote. It is the only signal in the channel that can’t be blamed on the writing.
So split there before you rewrite anything.
If acceptance held and replies fell, the message is a fair suspect. Go and rewrite it.
If acceptance fell, the sequence you are about to rewrite was never read by the people you are rewriting it for. And the test you run afterwards will come back clean, because it will hold the list still again.
If you want to test the list the way you test the copy, invert it. Hold the message, vary the segment. Same sequence, two populations. Almost nobody runs that one, because the tooling makes a copy variant a button and a list variant a project.
Run all of it and you still walk into the same wall. You will want to know why those people were on the list in the first place, and there is nothing to read. That call got made once, by a filter or by a person, and nobody wrote down what it decided.
That wall is where the long version starts. Four decisions, what each one has to settle before it spends anything, and what it costs you later when it doesn't.


Our contact form doesn't collect leads. It qualifies them.
By the time a submission reaches me the company has been researched, the address checked, the lead scored against our ICP, filed in the CRM and posted to Slack with everything I need to answer it. The whole path:
→ The form is the workflow. Built directly in @cargo_hq. No form tool, no glue, no webhook to maintain, because the submission lands inside the automation that handles it.
→ Enrich, then verify. Cargo pulls the company from the domain, then checks the address is real and deliverable before anything downstream runs.
→ Score against the ICP. The company is routed to one of our four segments and graded on the criteria we actually use: B2B, headcount band, geography, language. Out comes an ICP segment and an ICP fit, with the reasoning written onto the record instead of left in someone's head.
→ Into @attio. Company and person created or updated, linked to each other, added to our Inbound Leads list with the source and the stage already set.
→ Into @SlackHQ. Same moment, one message: who they are, the company, the segment, the fit, the confidence, the address check, and the full text of what they wrote. Not a notification pointing at a record. The record.
That's the half I expected to build. This is the half I didn't.
I answer without leaving the channel. @slashyemail runs inside Slack, so I ask it in the thread to draft the reply. It writes the mail and shows me the whole thing, from and to and subject and body and signature, then asks whether I want to change anything or send it.
I tell it to send. It's gone.
No CRM tab, no inbox, no carrying context between four windows. The lead arrives qualified and leaves answered in the same place.
Collecting a lead was never the hard part. Everything that has to happen before you can answer one is the system.

We partner with Slashy, so this one comes with a link. 7-day trial, and 10% off if you stay on after it:
slashy.com/?ref=NOVRITH

Your CRM didn't just record your sales process. It renamed it.
Nobody decides to adopt a tool's vocabulary. You type it into a field for a year, and it turns up in your meetings, your handovers, and eventually your board deck.
Take "opportunity". That's an object name in Salesforce, and it's now in the vocabulary of plenty of teams that have never run Salesforce.
@attio shipped renaming for system objects. Deals, Users, and Workspaces now take your own singular and plural noun, and your own icon. Companies and People don't, yet.
The slug underneath stays fixed, so record URLs and existing integrations keep working.
In the video below I rename Deals to Opportunities, purely as an example. At Novrith we're keeping Deals. That's the right word for what we sell, and the difference now is that we picked it.
It's one settings field, which is why it's easy to file under cosmetics. It isn't. Almost nobody on your team will ever open the data model. Every one of them reads the noun in the sidebar.
So pick the word your team already says out loud. If you have to stop and work out what that word is, that's the finding, not the setting.
A backfill run died halfway through and took 39 reactions and comments with it.
We got all 39 back the next morning without ever finding out which ones they were.
That isn't a recovery process. It's one decision, made before any of that data existed: no number in this system is ever added to.
A running count can only be repaired by someone who can tell it what it missed. And what it missed is the record of what happened.
The information that would fix the number is the information whose absence broke it.
So nobody fixes those numbers. They get reset, or they get believed.
Ours keeps no totals at all. One row for every thing that happened, and every number counted fresh on each run.
Totals stop being something you protect. Delete one and the next run rebuilds it exactly.
Re-harvesting a post produces the same rows and the same totals: 47 events on the first post we tested it on, still 47 after every re-run since. A failed run stopped being an incident and became something you run again tomorrow.
Last month I wrote about arithmetic that lives on the record and recalculates itself. That works when the inputs are already sitting there. This is the harder case, where the inputs are things that happened, and they only exist later because somebody decided to keep them.
Which is what makes the increment so tempting. Counting means storing the thing you'd count, and storing every small event feels like overkill right up until the morning a number is wrong.
Every automation tool ships an action for this. Lead scores that go up by five. Touch counts. Anything a workflow adds one to.
Every number your business runs on is one of two things. Something the system can recount from what it kept, or something it had to get right every time it was touched.
Only one of those can be checked.

Your reply rate was 11%. You doubled the sends. Now it reads 8%.
Somebody is already rewriting the sequence.
The copy didn’t get worse. The measurement did, and it will do it again next month.
Here is the teardown. The dashboard reports a date range: replies this month over sends this month. It looks obviously correct, which is why nobody checks it. But a five-step sequence takes three weeks to run, so on the last day of the month the people you enrolled on Monday are sitting in the denominator with four steps still unsent, counted as people who did not reply.
They have not declined. They have not been asked yet.
That flaw does something worse than add noise. It moves the number in the wrong direction on purpose. Enroll more people and the share of unfinished sequences in the denominator rises, so the rate falls. Stop enrolling and it climbs, because the only people left are the ones who had time to answer.
The dashboard rewards you for stopping and punishes you for scaling.
So the drop gets read as a copy problem. The team rewrites the messages, the rate recovers a month later when the backlog clears, and the rewrite takes credit for arithmetic. Everyone has now learned something false, and they will apply it again.
It also breaks the one thing outbound teams do trust. Split-test two flows, read them the same afternoon, and the newer one always looks worse, because more of it is unfinished. Every A/B result you have ever read off a live date range has this sitting inside it.
On Tuesday I wrote about weighting a signal by what it cost the person who gave it. This is the failure one level down: the weighting can be perfect and the number still meaningless, because the population underneath it hasn’t stopped moving.
The fix is one decision. Measure by cohort, not by calendar.
✅ Group people by the week they were enrolled, never by the week a reply arrived
✅ A cohort stays open until every member has finished the sequence or left it early
✅ Only closed cohorts get a percentage. An open one gets a raw count and nothing else
✅ Keep early exits separate from non-replies, because someone who accepted and went quiet is not the same as someone who never received a message
✅ Put the closed cohorts side by side, so a copy change is read against a denominator that isn’t shifting underneath it
What changes isn’t the number. It’s that the number stops responding to volume. Double the sends and the closed cohorts hold, which means the next time a rate moves, something real happened.
A rate that moves when you change the volume isn’t measuring your outbound. It’s measuring your calendar.

Marco Serafini retweeted

You can now set Claude Code's output style to Concise.
Claude leads with the result, keeps responses short, and still gives full detail when you ask.
Turn it on in /config → Output style, or set "outputStyle": "Concise" in settings.json.

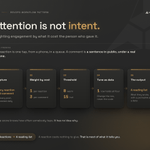
The person who engages most with your content has probably never written you a word.
Post consistently for a year and a couple of thousand people will react to something of yours. Three in four do it once and never come back. Fewer than one in ten ever write anything at all.
Call that a warm list and you have measured a feed, not interest.
So the question was never who engaged. It’s what the engagement cost the person who did it. A reaction is one tap, from a phone, in a queue. A comment is a sentence in public, under a real name, where their colleagues can see it.
We score ours on exactly that, and these are the live weights, the ones that were on screen in the dashboard I filmed two weeks ago. A reaction is worth 1 point. A comment is worth 3. Warm starts at 8, Hot at 15. All four sit in a one-row table on @cargo_hq rather than in the code, so retuning the list is a row edit and the next morning’s run reclassifies everyone.
At that weighting, two thousand people come back as a few dozen. On my own account, which is a lot smaller, it turns just under two hundred into seven.
The score still can’t tell you why somebody taps, and some of those will have earned their place on volume alone. That’s fine, because the output was never a call list.
It’s a reading list. For most of them there is something they actually said, with a permalink and a date, and that is the only part of any of this that carries intent rather than attention.
A reaction costs nothing to give, and that is most of what it tells you.
Weight any signal by what it cost the person who sent it.

Every LinkedIn sequencer stops when someone replies. That's the easy half, and it's the half everyone already has.
The hard half is what starts.
A reply is the most expensive thing an outbound system produces. It costs the list build, the enrichment, the grading, and five messages over twenty-five days.
Then it lands in LinkedIn, which is not where any of the work is tracked. The CRM still has the lead sitting where it was. No task exists. And whoever opens it has to scroll back through five messages to find out what we already said.
So it sits. Not because anyone decided to leave it there. A notification asks for attention. A task claims it. That reply only ever asked.
Ours writes the reply onto the record before it tells anybody. Groovin syncs the thread onto the person, and the stage moves from New to Engaged in @attio on its own.
That isn't bookkeeping. The state change is the handoff. It puts the conversation in the system people already work from, with the messages that earned it attached, and it happens whether or not anyone remembers.
What comes after stays judgment: meeting booked, qualified, not now, no.
Stop-on-reply was a toggle. The handoff was a data model. We built it before a word of the copy.
Stopping is what the tool does. Starting is what you designed, or didn't.

We're Groovin partners, so this one comes with a link.
Before you click anything, one thing worth running on your own setup: open the last cold reply you got, and look at what changed in the CRM at that moment. Not what you did after. What moved on its own.
If nothing did, the handoff is a notification and a good memory.
10% off with NOVRITH10: groovin.ai/?fpr=marco76

Someone we'd been tracking for two months disappeared from our own database.
They hadn't left LinkedIn. They'd changed their profile URL.
They weren't the only one. When we reconciled the whole dataset against LinkedIn's own counters, one person in it had five separate records, one for every run that went looking and didn't find them. Engagement totals were coming in about 11% short.
All of it traced back to one decision from the first build, and to two months of fixes that never touched it: we matched people on their profile URL.
A profile URL looks like an identifier. It's unique, it resolves, it has their name in it. But it's a display string, and the person it points at owns it. They can change it on a Tuesday afternoon and never think about it again. The match also broke on non-ASCII characters, so a Turkish ı in someone's name was enough to lose them.
The change is one line of the design. Match people on the member ID the platform issues and the person cannot edit.
The part that stings is that the ID was in the response the whole time, on every record, from the first day. We were reading past it to get to the URL.
A renamed profile is now a non-event. A name that isn't written in Latin script is a non-event. One person is one row and stays one row across every run, because there is nothing left for the system to get wrong about who they are.
In July I wrote about the merge workflow, what to do once two records exist for one person. That workflow still matters. This is the decision one step upstream of it, and it's the one that sets how often you have to run it.
The same trap is sitting in most CRMs under a different name: a person keyed on their work email, which changes the day they change jobs.
So ask it of every key in your system: who is allowed to change this?
If the answer is the person it identifies, it was never a key. It's a label that happens to be unique today.

I put a new company into our CRM this morning and never opened the CRM.
@slashyemail moved @attio lists into the email sidebar.
The thread was a cold pitch. A founder had emailed three times about his GTM tool, and this morning I answered: I'm happy with what I'm already running, both of them driven from the terminal, so a third tool to evaluate isn't where my week should go. If his does something specific that mine don't, I'll take the call.
That is the most common verdict in business and the one nobody writes down. Not now, but not never.
So I gave it somewhere to live. Company added to our Suppliers list, stage set to Evaluation, category Software/SaaS, and a one-line note on what the product actually is. All of it in the sidebar of the message I was answering.
That last part is what makes it useful. Not that lists are visible from the inbox, but that the list entry's own attributes are editable there. Membership on its own is a label. Stage, category and a note are a judgment.
You can also skip the fields and say it: "add the company to our Suppliers list".
What I keep coming back to is where records are born. Companies don't arrive through your CRM. They arrive through an email, a form, an intro, and the CRM is where they go afterwards. That gap between meeting a company and having it in the system is small, and it's exactly where the maybes fall out.
Close it and a maybe survives contact with the week.
The open question arrives with it. If records can be created and changed from the inbox, the inbox is now a place where records change. That's an ownership question, and I don't think it has a general answer yet. For two people it's obviously fine. At fifteen I'd want to know who can move what, and from where.
"Maybe later" is the most common answer anyone will give you, and the least recorded. Not because it doesn't matter. Because until now, writing it down cost more than it was worth.

We're Slashy partners, so this one comes with a link. 7-day trial, and 10% off if you stay on after it:
slashy.com/?ref=R8OSSN5T
