

Learning, Robotics, Controls & Open Source Enthusiast
San Francisco, CA
Joined October 2012
- Tweets104
- Following473
- Followers291
- Likes586





Manuel Yves Galliker retweeted

1/ General-purpose robotics is the rare technological frontier where the US / China started at roughly the same time and there's no clear winner yet.
To better understand the landscape, @zoeytang_1007, @intelchentwo, @vishnuman0 and I spent the last ~8 weeks creating a deep dive on humanoid robotics hardware and flew to China to see the supply chain firsthand.
Here's everything we've created + our takeaways about the components, humanoid comparisons, supply chains, and geopolitics👇
Manuel Yves Galliker retweeted

Introducing MARS, the first Personal AI Robot.
In technology, getting to the future we want starts with building it together.
This is why we designed Mars. Inspired by early PCs, Mars is a powerful, complete, extendable robot.
It runs BASIC, an open embodied AI agent we created for you to program with code, demonstrations, and prompts. This allows Mars to perform complex long-horizon tasks involving spatial memory, reasoning, manipulation and navigation.
Pre-orders open now
⬇️ Demos & details in the thread
Manuel Yves Galliker retweeted

this year alone, I've met hundreds of the world's elite AI researchers + engineers steering the future of intelligence, and they ultimately want to do it here, in the US 🇺🇸
If a visa or green card are holding you back, join us on 7/31 in SF and hear real stories from @MatternJustus, @manumerous, @theaievangelist, and me @lighthousehq_ on getting unblocked to pursue their ambitions
RSVP in thread
Manuel Yves Galliker retweeted
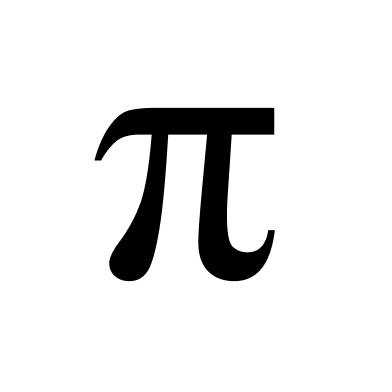
We got a robot to clean up homes that were never seen in its training data! Our new model, π-0.5, aims to tackle open-world generalization.
We took our robot into homes that were not in the training data and asked it to clean kitchens and bedrooms. More below⤵️
Manuel Yves Galliker retweeted
We are excited to share new experiments with AgiBot @AgiBot_zhiyuan on multi-task, multi-embodiment VLAs! With one model that can perform many tasks with both two-finger grippers and multi-fingered hands, we take another step toward one model for all robots and tasks.
Manuel Yves Galliker retweeted

It's All in the Hips
Can we learn anything from the evolution of hip kinematics in humanoid bots?
Is there a growing consensus of the optimal design?
Yes. And there is data to prove it.
First, a primer on Hip Kinematics
🧵


Manuel Yves Galliker retweeted

“Pretraining as we know it will end”
Robotics: Hold my 🍺 , new data coming
Source: Agibot
Manuel Yves Galliker retweeted

Can generative video models accurately model real world futures and contact physics?
At @1x_tech, we're working on world models as a scalable architecture to teach robots to solve tasks and evaluate themselves. We're announcing our World Model Sampling Challenge with $10,000 awarded to to the model which best predicts the next robot state from a history sequence.
In collaboration with @NVIDIARobotics, we're releasing a new 100 hour EVE robot dataset of navigation and manipulation encoded with the Cosmos Tokenizer. Cosmos compresses video sequences by 512x into a discrete, temporal representation optimized for world model learning.
Manuel Yves Galliker retweeted

The original RL algorithms, inspired by natural learning, were online and incremental—they were streaming in the sense that they learned from each increment of experience as it happened, then discarded it, never to be processed again. The streaming algorithms were simple and elegant, but the first big successes of RL in deep learning were not with streaming algorithms. Instead, methods such as DQN chopped the stream of experience into individual transitions, then stored and sampled them in arbitrary batches. Subsequent work followed, extended, and refined the batch approach into asynchronous and offline RL, while the streaming approach languished, unable to produce good results in popular deep learning domains.
Until now. Now researchers at the University of Alberta have shown that streaming RL algorithms can work just as well as DQN on Atari and Mujoco tasks (arxiv.org/pdf/2410.14606). How did they do it? Mostly just by getting signal normalization and step-size bounding right for the streaming case—otherwise they use standard streaming algorithms like TD(lambda) and Q(lambda). To me it looks like they were simply the first researchers knowledgeable of streaming RL algorithms to seriously address deep RL without being over-influenced by batch-oriented software and batch-oriented supervised-learning ways of thinking.

Would you believe that deep RL can work without replay buffers, target networks, or batch updates? Our recent work gets deep RL agents to learn from a continuous stream of data one sample at a time without storing any sample. Joint work with @Gautham529 and @rupammahmood.
Manuel Yves Galliker retweeted
hello, world model
1x.tech/discover/1x-world-mo…

Manuel Yves Galliker retweeted

Some reflection on what today's reasoning launch really means:
New Paradigm
I really hope people understand that this is a new paradigm: don't expect the same pace, schedule, or dynamics of pre-training era.
I believe the rate of improvement on evals with our reasoning models has been the fastest in OpenAI history.
It's going to be a wild year.
Generalization across Domain
o1 isn't just a strong math, coding, problem solving, etc. model but also the best model I've ever used for answering nuanced questions, teaching me new things, giving medical advice, or solving esoteric problems.
This shouldn't be taken for granted!
Safety by Reasoning
The fact that our reasoning models also improve on safety behavior and safety reasoning is very much non-trivial.
For years (a decade?) the boogeyman of the AI world was reinforcement learning agents which were incredibly adept at game playing but completely incapable of reasoning or understanding human values!
This is a strong point of evidence against this.
Scaling inference-time compute can compete with scaling training compute!
The fact that o1-mini is better than o1 on some evals is very very remarkable. The implications of this I'll leave as an exercise for the reader.
Multimodal Reasoning
It's kind of crazy that reasoning improves on multimodal evals as well! See MMMU and MathVista: these aren't small improvements.


Manuel Yves Galliker retweeted

Tomorrow, @1x_tech is going to release an exciting update on our AI and Autonomy efforts. To give a hint as to what we're about to reveal, here are some of the autonomy videos we've shared in the last 1+ years of scaling up our data engine.
Every video in this thread is autonomous, 1X speed
Manuel Yves Galliker retweeted
Proud to share that @1x_tech has closed our Series B.
We’re taking the next step toward our vision: Androids in every home, enhancing daily life. The team at 1X makes these milestones possible, and we can’t wait for you to bring an NEO home.
1x.tech/discover/1x-secures-…

Manuel Yves Galliker retweeted
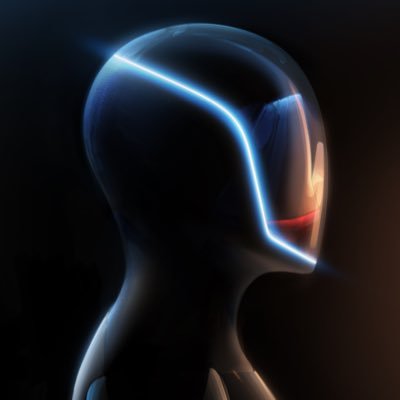
Multiple fully Tesla-made Bots now walking around & learning about the real world 🤖
Join the Tesla AI team → tesla.com/AI
Manuel Yves Galliker retweeted

Dive into Riemannian geometry on curved manifolds and investigate how the Riemannian method is applied to calculate the manifold's curvature across different scenarios. Gain insights by analyzing these cases using the #WolframWay. wolfr.am/1cCAhRkh0

ALT The image displays 3D graphics of a sphere and a cylinder. The sphere has three arrows of green, red and blue colors originating from the same point on the surface of the sphere. The red and green arrows are perpendicular to each other. Also, the red and blue arrows are perpendicular to each other. The green and blue arrows are pointing away at 180 degrees. The translation of three arrows on the surface of the sphere is indicated by dotted curves. On the cylinder's surface, there are three arrows: black, blue and red. The black and blue ones translate in a curved rectangle. The red one moves along the circular path on the cylinder's curvature.
Manuel Yves Galliker retweeted

Hot take?
Unmovable objects are pretty nice! if you need to move them anyway or don't want to propagate the unmovable property, you can wrap them in a unique_ptr.
Omitting move-assignment and constructor saves some work, and you can't "get it wrong".
cppcoach.godbolt.org/z/7847c…

Manuel Yves Galliker retweeted

Paper after paper from the Habitat folks is showing that fast, physics-free simulation + distributed PPO is a superbly scalable strategy. Amazing work.

Contemporary discussion (hype?) about LLMs and “pausing AGI development” seems oblivious of Moravec’s paradox.
We’ve hypothesized since the 80s — that the hardest problems in AI involve sensorimotor control, not abstract thought or reasoning.
It explains why AI is mastering games, dialogue, and scene generation. But robots are conspicuously missing from this revolution.
Today, we announce 2 major advancements on the embodied road to general intelligence: bit.ly/40pJU5M