

Situated World Models. Built to Move.
Joined June 2022
- Tweets41
- Following25
- Followers1.1K
- Likes39




Pinned Tweet
Trio-Spark v1.3 is live ⚡
The SOTA System-1 decision model for autonomous agents.
Most agent pipelines burn compute generating text just to pick an action. Spark turns action selection into a single forward pass: zero generated tokens, perfectly calibrated confidence.
🏆 SOTA Performance Across 13 Benchmarks:
• 90.9% on the ten-task panel (+7.8% over v1.0, overtaking Jev 1.13 and level with Clef)
• #1 among all 7 models on PubMedQA, RTE, TweetEval, and SNLI
• Calibration error crushed to 0.019 (vs 0.234 in v1.0) — true confidence you can actually threshold
Upgrade is drop-in: same API, identical limits, text & multimodal vision support. Just point to "model": "trio-spark-v1.3".
⚡ Get 100 free decisions: platform.machinefi.com/spark
📖 Full benchmark report & transparency note:
machinefi.com/blog/trio-spar…

We showed our multimodal fast-decision model Trio-Spark random photos of US trucks and asked one question: "What is it hauling?"
• Zero training. Zero examples.
• 83% accuracy across 7 trailer types.
• 100% hazmat placards caught.
• Cost: Just $14 per MILLION photos. 🤯
Extracting equipment, hazmat, or load status on every highway frame used to be cost-prohibitive. Now, Spark delivers calibrated probabilities in a single pass, letting your pipeline automate the confident calls and only route edge cases to humans.
Run a camera network? Send us 10k labeled images and we'll prove the accuracy and cost on your own data.
Try it out: platform.machinefi.com/spark
Picture the comment section under a popular YouTube video or live stream. Thousands of comments pour in. Most are fine, some are toxic, and a few are borderline.
We built a tiny demo: Trio-Spark v1.3 reads 600 real comments as they arrive and gives each one a probability that it's toxic.
You set two lines:
🟡 above the first → a human moderator reviews it
🔴 above the second → hidden automatically
Want it stricter? Drag the line. All 600 comments re-sort instantly, with no new model calls.
88% agreement with human raters. $0.0017 for all 600. 👇
Your doorbell cam doesn't need to ping you for everything.
We pointed Trio-Spark at a front door for a day:
📦 package dropped off → "Package at your door"
😊 family walks in → "Welcome home," no alert
🚨 someone with a flashlight at 2 AM → alert
MachineFi Lab retweeted

Trio-Spark v1.3 is live on QuickSilver Pro ⚡
The SOTA System-1 decision model. One forward pass, zero generated tokens, a calibrated probability for every choice.
• 90.9% on a 10-task decision panel
• #1 of 7 models on PubMedQA, RTE, TweetEval & SNLI
• Calibration error 0.019: confidence you can threshold
$0.042 / 1M input tokens. Output is free.
Same QSP key, POST /v1/systemone:
quicksilverpro.io/models/tri…


Trio-Spark v1.3 is live ⚡
The SOTA System-1 decision model for autonomous agents.
Most agent pipelines burn compute generating text just to pick an action. Spark turns action selection into a single forward pass: zero generated tokens, perfectly calibrated confidence.
🏆 SOTA Performance Across 13 Benchmarks:
• 90.9% on the ten-task panel (+7.8% over v1.0, overtaking Jev 1.13 and level with Clef)
• #1 among all 7 models on PubMedQA, RTE, TweetEval, and SNLI
• Calibration error crushed to 0.019 (vs 0.234 in v1.0) — true confidence you can actually threshold
Upgrade is drop-in: same API, identical limits, text & multimodal vision support. Just point to "model": "trio-spark-v1.3".
⚡ Get 100 free decisions: platform.machinefi.com/spark
📖 Full benchmark report & transparency note:
machinefi.com/blog/trio-spar…
We threw 1,000 customer-support tickets at Trio-Spark v1.3.
⏱ ~0.4 s and $0.000005 per ticket, on a single T4 (a low-end @nvidia GPU)
🎯 94.7% exactly matched human routing
💸 $0.005 total. Half a cent for all 1,000.
This is System-1 scaling in the real world. One forward pass per ticket.
Trio-Spark v1.3 is live ⚡
The SOTA System-1 decision model for autonomous agents.
Most agent pipelines burn compute generating text just to pick an action. Spark turns action selection into a single forward pass: zero generated tokens, perfectly calibrated confidence.
🏆 SOTA Performance Across 13 Benchmarks:
• 90.9% on the ten-task panel (+7.8% over v1.0, overtaking Jev 1.13 and level with Clef)
• #1 among all 7 models on PubMedQA, RTE, TweetEval, and SNLI
• Calibration error crushed to 0.019 (vs 0.234 in v1.0) — true confidence you can actually threshold
Upgrade is drop-in: same API, identical limits, text & multimodal vision support. Just point to "model": "trio-spark-v1.3".
⚡ Get 100 free decisions: platform.machinefi.com/spark
📖 Full benchmark report & transparency note:
machinefi.com/blog/trio-spar…
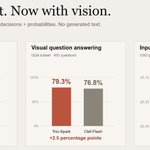
Meet Trio-Spark v1.1 — now with vision. 👀
A System-1 model that doesn't just describe the world—it makes decisions. Screenshots/video in, action probabilities out. One forward pass.
✅ Beat Clef-Flash on GQA (85.3% vs 76.8%)
✅ 53% lower API cost
✅ Fast enough to drive an arcade game live
Build your next agent with it. Try 100 free decisions now: platform.machinefi.com/spark
Benchmarks + demos: machinefi.com/blog/trio-spar…

Trio-Spark v1.0 is now listed on ModelSystem.One ✨
A Situated World Model for fast judgment. Give it a scenario and 2–8 possible moves—it returns the choice and full probability distribution in one pass.
Listing: modelsystem.one/models/trio-…
Try it: platform.machinefi.com/spark

Following our drone deployment, Trio-Spark v1.0 now generalizes to robotic manipulation.
By continuously evaluating the physical state, the model executes a strict sequence of 8 manipulation skills to complete the task in 13.68 seconds with zero collision violations.
Entirely token-free. One model inference per action boundary.
Live API: platform.machinefi.com/spark
Code & Demo: github.com/machinefi/trio-sp…
To validate its real-time physical capabilities, we integrated the API into a fully autonomous drone loop. The model successfully navigated a dynamic obstacle field, making 25 consecutive tactical decisions over a 75.7m course with zero collisions.
The framework is open-source. We invite the community to test the API and contribute new physical AI demos.
API: platform.machinefi.com/spark
GitHub: github.com/machinefi/trio-sp…
Today we're launching the first model of the Trio family: Trio-Spark v1.0, a Situated World Model built purely for instant action. Feed it a scenario and up to 8 possible moves, and it instantly returns the optimal choice and full probability distribution in exactly ONE pass.
Zero output tokens. Lightning-fast agent loops.
🏆 Benchmarks (Production T4 API):
• SST-2: 92.89% Accuracy
• AG News: 88.46% Accuracy
• Jevals PubMedQA: 85.33% Accuracy (DS 42.36)
• TweetEval (Offensive): 80.58% Accuracy
• PubMedQA (3-way): 68.60% Accuracy
• SST-5: 53.03% Accuracy
• Jevals HelpSteer2: 92.67% Coverage
• JevBench (Public 231): 81.39% Coverage
Whether your agent needs to click a control, route a request, place a game piece, or pause a machine, Spark decides what happens next.
Try it now: platform.machinefi.com/spark
Full benchmarks & demos: machinefi.com/blog/trio-spar…
MachineFi Lab retweeted

@liquidai just shipped an incredible on-device agentic model. The best part? It's so efficient that it's absolutely perfect for everyday 8GB or 16GB Macs.
We just pushed day-one support in rapid-mlx 0.12.4 to make it fly on your machine:
⚡️ 97.8 tok/s on an M2 Pro
🪶 2.0 GB peak memory
⏱️ 4.8s cold boot
🧠 128K context
Run it locally with one command:
- rapid-mlx serve lfm2.5-2.6b-4bit

Today we release LFM2.5-2.6B, an agentic model that runs entirely on-device. It plans, calls tools, and works through multi-step tasks on phones, laptops, PCs, and robots. Data never leaves the device, and the marginal cost of each run is essentially zero.
> Pre-trained on ~34T tokens
> LFM2.5 flagship hybrid architecture
> Context length: 128K
> Vocab size: 128K
> balanced intelligence per watt
> customizable on a single GPU for any specialized task
> LFM2 open-weight license
Comparable or better scores compared to models up to nearly 4x its size:
> ToolSandbox 77.83, ahead of Qwen3.5-9B at 76.44
> Multi-IF 80.07, ahead of Gemma-4-E4B-it at 77.35
> IFStruct 85.49, ahead of Qwen3.5-9B at 78.50
🧵

AI conquered the digital world — language, code, images.
Now it's coming for the physical one.
Today we're launching Trio: a world model for physical operations.
AI learned language first. Now it's operating the real world.🧵🧵
Trio is built for the messy reality of enterprise:
Scale: Runs across entire sites, tracking people & machines at once
Speed: Low-latency, real-time execution at the edge
Cost: Enterprise efficiency at just~$0.004/query
Trust: Every decision is verifiable & backed by evidence
6/6 Start Building now 👇
▶️ Playground - watch Trio read real footage: platform.machinefi.com/playg…
⭐ Trio- Retina on GitHub: github.com/machinefi/trio-re…
📄 v1.0 technical report: machinefi.com/technical-pape…
📝 Full story:
machinefi.com/blog/trio-a-wo…

Jim Fan's "Robotics: Endgame" maps the path: VLA to WAM to Physical AGI.
Adapting the LLM playbook to reality via video pre-training and action alignment, we build WAMs using verified real-world signals.
The Physical Turing Test is imminent, with the full tech tree by 2040!

I promise this will be the best 20 min you spend today! Robotics: Endgame, the sequel to my last year's Sequoia AI Ascent talk, "Physical Turing Test". I laid out the roadmap for solving Physical AGI as a simple parallel to the LLM success story. Be a good scientist, copy homework ;)
And stay till the end, more easter eggs and predictions for your polymarket!
00:30 DGX-1 origin story at OpenAI, I was there in 2016 signing with Jensen and Elon. Heading to the Computer History Museum!
01:42 The Great Parallel
03:31 Robotics, the Endgame
03:39 Why VLAs fall short
04:32 Video world models as the 2nd pretraining paradigm
06:09 World Action Models (WAM)
07:46 Strategies for robot data collection and the FSD equivalent to physical data flywheel for robot manipulation
11:06 EgoScale and the Dexterity Scaling Law we discovered recently
14:00 Physical RL: bridging the last mile
15:39 DreamDojo: an end-to-end neural physics engine for scaling RL in silico
17:00 Civilizational Technology Tree and my predictions for the near future. Spoiler: it's closer than you think.
Thanks to my friends at Sequoia for inviting me back to AI Ascent this year! I had a blast! Last year's talk is attached in the thread if you missed it.