





Pinned Tweet
After 8 months of building in stealth and testing our infrastructure on 10000+ hours of real-world data and hundreds of unique environments, we're bringing @fpv_labs into the open today.
FPV Labs started with the following bet - if human data proves to be the underlying factor that determines scaling laws in general-purpose robotics, it will trigger the largest economic transformation in human history, and the underlying infrastructure that captures that data will determine how fast we get there.
We will achieve this by building the full-stack infrastructure for capturing, processing, transferring, and evaluating human experience into spatial, temporal, and semantic knowledge for machines.
Despite all the research novelty behind ChatGPT, its success can be attributed to one foundational fact - the scaling law of transformers. We believe the same dynamics have made their way into robotics.
Recent studies showed task completion rates jumping from 30% to 70% when human demonstration data scaled from 1,000 to 20,000 hours, a log-linear trend that mirrors exactly what we saw in language and vision. Seeing these emergent signs of scaling law curves in robotics, we believe we are entering the era of general-purpose robotics policies, which makes the next few years the most exciting time in the history of this field.
But the library of physical interactions required to train general-purpose robot policies does not exist yet. Over the last 8 months, we've seen dozens of companies emerge in this space. We were really happy to see new companies pushing this space forward, but we also saw the same pattern repeat: every egocentric data company was making some tradeoffs between quality, scale, and diversity.
We have built FPV labs on the core principle that high-quality data is orders of magnitude more valuable than sheer volume. Case in point, self-driving cars collect thousands of hours of data per day, but only a small fraction of that data is actually useful for training better models. Several studies, like RT-2, have shown that as little as 1% of data improves as much as 25% on task success. The quality and diversity of data matter a lot more than scale, so there is clearly a power law curve in the downstream impact of data.
We've spent months obsessing over data quality by building our stack, discarding it, rebuilding it, and iterating until we found a formula that doesn't compromise downstream quality at scale.
We believe the downstream impact here is far more profound than most people realize. Workers globally are paid around $60 trillion per year in aggregate, and a lion's share of that compensation goes to physical labor - tasks that require navigating real spaces, manipulating real objects, and negotiating the infinite variability of the physical world.
Human-to-robot transfer will be one of the most important infrastructures that will shape our society in the near future, and if it works, the economic impact will dwarf every technology transition that came before it in an exponential manner and lead to the creation of goods and services we can’t imagine today.
Our mission is to lay the groundwork for us to transition into this future - the future of abundance. We are deeply grateful to our earliest believers, @paraschopra and @lossfunk, who played a critical role in shaping our thinking.

Abhishek Anand retweeted

For generations, we've pushed the limits of what flight can do.
Yet moving goods still comes with a compromise. The sea takes weeks and flying costs too much. Somewhere along the way, the world got comfortable with waiting.
Today, we announce Eureka, our first aircraft. It takes off and lands on water, and it's designed to turn "in a few weeks" into "on the evening flight."
Break the surface.
Abhishek Anand retweeted

Super proud and excited to finally present LiteMol-1. This is our first foundation model from LiteFold, pre-trained from scratch.
Today, LiteMol-1 can generate small molecules, peptides, cyclic peptides, depsipeptides, peptides with ncAAs, macrocycles, and PROTACs.
Across our peptide and small-molecule evaluations, the model shows competitive results. In several settings, we are on-par with or better than frontier structure-based models, at a fraction of the generation cost.
But the part I find most interesting is that this is a model for agents. We have seen ourselves how much compute, and how many tokens it can take to generate good binders using frontier structure-based models. Sometimes you need to generate tens of thousands of designs just to get a handful worth taking forward.
Now put this inside an AutoResearch loop. The agent has to continuously parse structures, inspect PDB/CIF files, compare candidates, run evaluations, modify the design, and repeat the whole thing again. It becomes extremely expensive very quickly.
Sequence space gives us a very different interface. LLMs are much more efficient at inspecting and manipulating compact molecular representations like SMILES than repeatedly operating over full structural files.
So LiteMol-1 becomes something like an infinite molecular canvas for the agent. For a given target and objective, the model can continuously propose what a biomolecule could look like. The agent can inspect those generations, take inspiration from them, preserve certain regions, edit others, optimize them, score them, and generate again.
Generate → inspect → evaluate → edit → generate again.
There is another problem I care a lot about. Most molecule design models today are heavily optimized around binding. But binding is only one part of whether something eventually becomes a therapeutic. What about ADME? Toxicity? Selectivity? Solubility? Membrane permeability? Synthesizability?
For this, we also built a Monte Carlo Tree Search-based multi-objective generation framework around LiteMol-1. Instead of combining everything into one score, the search keeps multiple strong candidates, each balancing the desired properties in a different way.
As our scoring functions and verifiers get better, the generation system gets better too. We can start steering molecules not just toward “binds well”, but toward a broader therapeutic design specification.
The bottleneck slowly moves from simply generating molecules to having sufficiently good verifiers and scoring functions to tell us what is actually worth generating. Check out our technical research blog post for all the details.
At LiteFold, our research is focused on engineering biomolecules and building systems that can carefully forecast their pre-clinical success.
To stay updated on our research, follow LiteFold.
Cheers!


Today, we are incredibly excited to present LiteMol-1, our very first foundation model from LiteFold.
Structure-based models like BoltzGen, O-Design, and RFdiffusion have become the de facto standard for designing biomolecules. However, they are expensive to run at scale. In many campaigns, we have to generate tens of thousands of designs and rigorously filter them down to a handful of top candidates.
More importantly, most molecule design systems are primarily optimized around binding. But what about everything else that makes a molecule a useful therapeutic: ADME, toxicity, drug-likeness, membrane permeability, synthesizability, selectivity, and more?
That’s where we introduce LiteMol-1, our first Multi-Molecule Foundation Diffusion Language Model, pre-trained from scratch. With a single set of weights, LiteMol-1 can conditionally generate small molecules, peptides, cyclic peptides, depsipeptides, peptides with ncAAs, macrocycles, and PROTACs.
You can generate molecules unconditionally or condition generation on a protein target sequence. You can in-paint molecules, preserve parts of an existing scaffold, generate non-canonical peptides, cyclize designs, and continuously edit and regenerate them.
We also introduce a Monte Carlo Tree Search framework for multi-objective molecular design. Instead of trying to make one molecule perfect at everything, the search keeps a set of promising molecules, each with different trade-offs across properties. This matters because molecular design is fundamentally not a single-objective optimization problem.
Finally, and probably the part we are most excited about: this is a model for Agents. LLMs are not particularly efficient interfaces for repeatedly reasoning over thousands of large PDB/CIF files inside an AutoResearch loop. Sequence space is different. SMILES and molecular sequences are compact, editable, and much easier for an agent to inspect, compare, modify, and reason over.
So we treat LiteMol-1 as an infinite molecular canvas.
The model generates possibilities. The agent takes inspiration from them, evaluates them, edits them, optimizes them, and generates again. The AutoResearch loop continues until it finds candidates that satisfy the given design objectives; while bringing in expensive structure prediction, docking, or simulation only when they are actually needed.
Our evaluations across peptide and small-molecule generation show that LiteMol-1 is competitive with, and in several settings on-par with or better than, frontier structure-based and sequence-based models, while operating at a fraction of the generation cost and time.
And this is only the first step. Check out our technical research blog post in the comments to learn more about LiteMol-1.


Abhishek Anand retweeted

I spent a lot of time with the ARKitScenes dataset; it's a great proxy for a bunch of downstream tasks and holds some ~5k casually collected iPhone reconstructions. I make the argument in the attached article that using this with Prompt Depth Anything, MogeV2, and Gaussian Splats leads to much better reconstructions for other downstream tasks and labels.
Here's one of the post-processed reconstructions I generated that contains the depth and normal maps for the ultrawide camera


Abhishek Anand retweeted

The next big egocentric dataset might not need a $10K headset.
Ego-OSCAR is an open-source head-mounted stereo-inertial capture system built for under $200, combining synchronized global-shutter stereo, a 6-axis IMU, onboard encoding, and real-time feedback. The goal is simple: make large-scale first-person data collection cheap enough to crowdsource.
Abhishek Anand retweeted
Opensource hardware is the way to go. Love to see it!

🚨 New Open Source Release
Today we are releasing Ego-OSCAR, an open-source head-mounted stereo-inertial capture device for egocentric data collection in the wild, together with a corresponding dataset of 550 hours captured across 100+ environments.
Egocentric data is still an active research problem, and we believe an open and accessible foundation will empower everyone to participate, experiment, build, and contribute to this space.
This continues our past efforts, where we open-sourced Stera, a full-stack capture and processing pipeline for RGB-D data. Ego-OSCAR builds on that lineage and offers a fully open-source stereo-inertial capture stack for anyone working on human-to-robot transfer.
We make three core contributions today with Ego-OSCAR:
1. An open-hardware capture device with full CAD, wiring, and assembly documentation, with a complete bill of materials under USD 200 and using commercially available components and 3D-printed parts.
2. An open-source capture pipeline (recording daemon, IMU sampler, time-sync tooling, watchdog firmware).
3. The Ego-OSCAR-550h dataset, approximately 550 hours of egocentric stereo video per camera with synchronized IMU, released to validate the device at deployment scale.
Everything is open-source, including the hardware designs, capture pipeline, firmware, and the downstream dataset.
Read the full blog at: fpvlabs.ai/essays/ego-oscar
The foundation for human-to-robot transfer must be open. @fpv_labs has open-sourced the full capture stack for a stereo inertial capture stack, along with 550 hours of data released on @huggingface. Let the data flow.
🚨 New Open Source Release
Today we are releasing Ego-OSCAR, an open-source head-mounted stereo-inertial capture device for egocentric data collection in the wild, together with a corresponding dataset of 550 hours captured across 100+ environments.
Egocentric data is still an active research problem, and we believe an open and accessible foundation will empower everyone to participate, experiment, build, and contribute to this space.
This continues our past efforts, where we open-sourced Stera, a full-stack capture and processing pipeline for RGB-D data. Ego-OSCAR builds on that lineage and offers a fully open-source stereo-inertial capture stack for anyone working on human-to-robot transfer.
We make three core contributions today with Ego-OSCAR:
1. An open-hardware capture device with full CAD, wiring, and assembly documentation, with a complete bill of materials under USD 200 and using commercially available components and 3D-printed parts.
2. An open-source capture pipeline (recording daemon, IMU sampler, time-sync tooling, watchdog firmware).
3. The Ego-OSCAR-550h dataset, approximately 550 hours of egocentric stereo video per camera with synchronized IMU, released to validate the device at deployment scale.
Everything is open-source, including the hardware designs, capture pipeline, firmware, and the downstream dataset.
Read the full blog at: fpvlabs.ai/essays/ego-oscar
Abhishek Anand retweeted

My @aiDotEngineer talk on lessons learnt from studying memory systems for a year:
> the evolution of chatgpt and claude memory over the years
> their architectural convergence
> why memory cannot be outsourced
> how memory is a function of compute
> continuous learning for individuals
> why we have a massive context problem
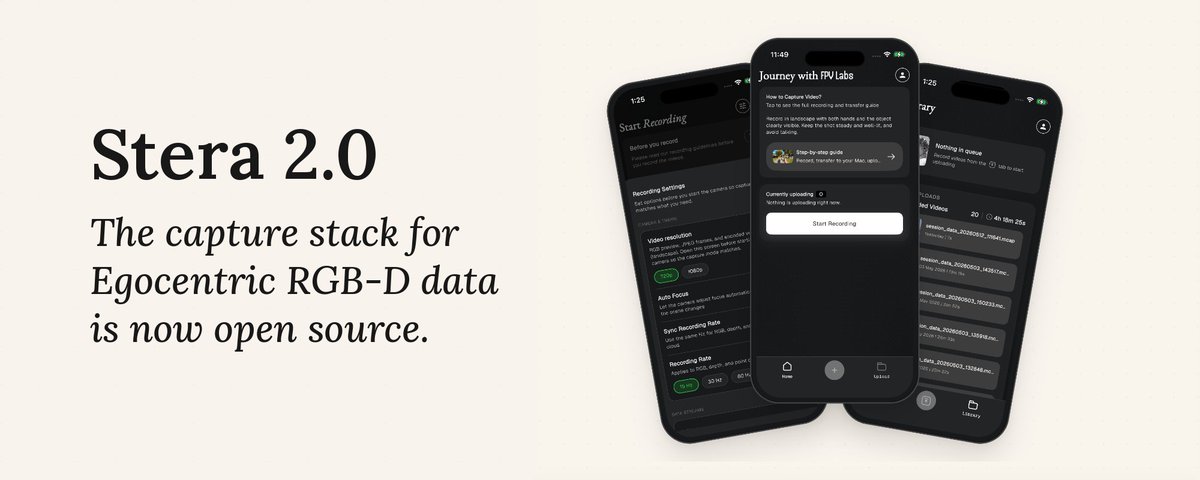
Excited to fully open source the entire Stera stack today. Stera 1.0 open-sourced the Stera SDK, which included the processing pipeline and evaluation.
Stera 2.0 now opens the capture stack, thereby closing the full loop and making the entire RGB-D stack available to anyone. Leveraging commodity devices capable of generating high-fidelity robotics data is the fastest way to solve the robotics data gap.
Abhishek Anand retweeted

Here’s some unsolicited advice to the government on what to do to help boost India’s sovereign model story.
1. Mandate domestic models for all non-critical functions
Government needs to be a guaranteed buyer for homegrown models. There are tons of applications that don’t require SOTA performance. (To be clear, for mission-critical use-cases, using anything other than SOTA would be a shortsighted decision)
China got ahead because of their domestic demand (Anthropic and OpenAI models don’t work there).
2. Release massive distillations of chain-of-thought of SOTA Chinese models on diverse prompts (and post-process to remove China bias)
Inference is easy and cheap. So the government should simply create a national public repository of SOTA reasoning chains in order to prevent each model creator doing it separately. Centralize and absorb the cost.
Thinking Machines (US company) did finetuning on Kimi 2.5 to bootstrap reasoning. Indian model companies would do the same, and government can help by footing the bill.
3. Procure diverse RL environments and release them publicly
Modern frontier models train on 100k+ RL environments having 10s of tasks each. These RL environments are driving most of the progress. Model companies pay billions of dollars for procuring them. Government should simply centralize and absorb this cost.
4. Give full travel sponsorship to Indian authors with A* conference accepts
If an Indian gets into NeurIPS, ICML, ICLR main conference, simply sponsor them to attend the conference to present their paper. It’s rounding error in govt’s budget as ~100 Indian papers get into such conferences (0.3-0.5% of papers are Indian primary authors), but would go a long way in establishing a culture of basic R&D which is required to go beyond the frontier in next 5-10 years.
The robotics community is sleeping on Vidur. Language density is the cheapest lever for extracting more signals from a demonstration dataset.
Vidur makes 3 core contributions -
1. An automatic dense annotation pipeline with state-of-the-art accuracy for dense action labels, including temporal action grounding, contact grounding, and spatial grounding
2. Empirical evidence of the accuracy with detailed evaluation across 2 diff benchmarks
3. Lowest processing cost per hour of data.
DM open if you want to partner with us!

Have seen @_raghuvamsi @Mankaran32 @pr0t0_01 and team pour their heart and soul into building these cute mobile companion robots over the last year - robotics and entertainment will soon see an inflection point through companion robots and virtual IPs that enter the physical world and live and grow with humans - @eyecandyrobots is one of the few teams globally that are really well positioned to make this happen!

🚨 Eyecandy Robotics (@eyecandyrobots), a Bengaluru-based startup, has unveiled a series of robot characters.
They plan to manufacture and sell their palm-sized tabletop robot, Piko, in 2027 at $200/unit.
Eyecandy will also develop a line of larger robots for theme parks.
Abhishek Anand retweeted

For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.
AI will transform every industry, power every company, and be built by every country.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.
The world needs both frontier closed models and frontier open models.
images.nvidia.com/pdf/Open-W…


Abhishek Anand retweeted

Vidur is out!!
Best in the world at turning raw video into dense, timestamped action labels. every metric, both benchmarks, against every frontier model we tested.
Abhishek Anand retweeted

Big milestone for robotics data pipelines🚀. Vidur tackles one of the field's toughest bottlenecks while achieving state-of-the-art performance across key benchmarks.
Check out the blog !!
@fpv_labs
#robotics #data
Abhishek Anand retweeted

@fpv_labs Vidur’s scoring SOTA on dense supervised action labels is genuinely so exciting for the millions of hours of raw ego video out there.
🚀
Excited to open up Vidur for robotics and data labs. Vidur achieves SOTA on WGO Bench and EgoExoLearn Bench and generates the highest-quality action labels at a fraction of the cost the market spends on action labels today.
Abhishek Anand retweeted

1/ A protein is a nanomachine - moving parts, does real work, changes shape to do its job. A gene editor is one of them: a molecular machine that hunts down a stretch of DNA and cuts it. We still borrow these machines from nature and tune them, because we don't understand them well enough to build our own. We started Mandrake to change that.
One of the sharpest teams from interactive entertainment now using game controllers to solve embodied ai - rooting for this team.

Today we're announcing our $320M Series A at a $2.3B valuation, led by @khoslaventures , with @generalcatalyst, @JeffBezos , @ericschmidt, @NicoRosberg, alongside leading researchers from frontier labs and academia.