

kwatra retweeted

Long-context inference is hitting a wall. 🛑
As context grows, Attention becomes the villain.
Why?
• Decode: Attention scales linearly (O(N)), while the rest of the model stays constant (O(1)).
• Prefill: Attention explodes quadratically(O(N²)).
Can we do better?(1/9)

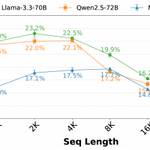
ALT Graph showing percentage of attention and other operations in total decode time.
kwatra retweeted

Evaluation of LLM serving systems is tricky because several factors influence performance (prefill length, decode length, parallelization) and there are multiple metrics we care about (throughput, ttft, tpot/tbt). We identify common pitfalls and a checklist to avoid them.

The bitter lesson of AI infra: The hardest part about building faster LLM inference systems is not designing the systems, but rather it is evaluating if the system is actually faster! 🤔
This graph from a recent top systems venue paper about long-context serving shows average normalized input token latency for a trace with both short and 100K+ token requests. System X looks like a clear win: lower normalized latency and higher request rates. But normalized metrics can obscure the actual user experience: at those rates, long inputs see >2hr delays to the first token!
Let’s do the math!🧮

kwatra retweeted

The bitter lesson of AI infra: The hardest part about building faster LLM inference systems is not designing the systems, but rather it is evaluating if the system is actually faster! 🤔
This graph from a recent top systems venue paper about long-context serving shows average normalized input token latency for a trace with both short and 100K+ token requests. System X looks like a clear win: lower normalized latency and higher request rates. But normalized metrics can obscure the actual user experience: at those rates, long inputs see >2hr delays to the first token!
Let’s do the math!🧮
kwatra retweeted

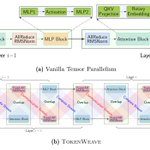
We have released the source code and benchmarks of TokenWeave. TokenWeave speeds up distributed LLM inference via compute–communication overlap and fused AllReduce, RMSNorm, and residual addition.
Code: github.com/microsoft/tokenwe…
Paper: arxiv.org/pdf/2505.11329
Try it out!


kwatra retweeted

🚨 Are LLM compression methods (𝘲𝘶𝘢𝘯𝘵𝘪𝘻𝘢𝘵𝘪𝘰𝘯, 𝘱𝘳𝘶𝘯𝘪𝘯𝘨, 𝘦𝘢𝘳𝘭𝘺 𝘦𝘹𝘪𝘵) too good to be true and are existing eval metrics sufficient? We've looked into it in our latest research at @MSFTResearch 🧵 (1/n)
arxiv.org/abs/2407.09141

kwatra retweeted
🚀 Introducing Metron: Redefining LLM Serving Benchmarks! 📊
Tired of misleading metrics for LLM performance? Our new paper introduces a holistic framework that captures what really matters - the user experience! 🧠💬
github.com/project-metron/me…
#LLM #AI #Benchmark

kwatra retweeted
Did you ever feel that @chatgpt is done generating your response and then suddenly a burst of tokens show up? This happens when the serving system is prioritizing someone else’s request before generating your response. But why? well to reduce cost. 🧵
kwatra retweeted
Ever wondered why @OpenAI charges 2x price for output tokens compared to input? Turns out that an output token can be up to 200x more compute time than an input token. Why? We explored this phenomenon during my internship at @MSFTResearch. 🧵