

Building RL post-training for GR00T2 @nvidia GEAR. RL-100, Uni-O4, BPPO
Joined October 2022
- Tweets285
- Following984
- Followers1.5K
- Likes593




Pinned Tweet
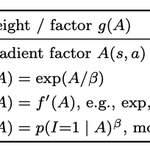
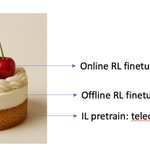
RL feels messy, but a two-axis view—data source (on/off/offline) × update schedule (one-step/multi-step/iterative)—brings order. I wrote a post unifying them with shared equations.
lei-kun.github.io/blogs/rl.h…
Robotic FMs (e.g., GEN-0, pi_0.5) grow via a data flywheel. Best fit: multi-step updates—conservative yet exploratory—then switch to iterative RL to surpass/align human ceilings.

Kun Lei retweeted

Invited speakers until 9:50 am — @kunlei15 gave a great talk on RL Post-Training for Real World Deployment!

Kun Lei retweeted
@Jesse_Y_Zhang kicking off the Roadmap to Sample Efficient Reinforcement Learning Workshop (#R2RL) at #CoRL2026!
We’re making RL work on real robots.
r2rl-workshop.github.io

GR00T 2 is here. Proud of Team Green! 💚

Introducing GR00T 2: our most advanced, open System One model for robotics. It runs entirely on your robot’s onboard compute, fully untethered, and you own every weight of it. GR00T 2 features:
1. Long-horizon tasks: dexterous manipulation and whole-body control chained over 20+ steps and 5+ minutes, such as performing chemistry lab experiments or assembling model airplanes end to end.
2. X-Adapt: adapting from easy data sources (human wearables and simulation) and deploying zero-shot to diverse real robots.
3. Unified Cognition: native integrations with frontier agents for advanced physical reasoning, robust error recovery, and safety monitoring.
It's an open-source buffet! We are releasing not only the model weights and X-Adapt recipes (coming December), but also our agentic framework, simulation engine, annotation engine, hardware design, and even training data (100K hours, that's ~11 yrs of experience), all available today!
Everything that moves will be autonomous. Anyone can become a roboticist.
Lock in, build with us!
Deep dive in thread:
6
460
Kun Lei retweeted

Meet GR00T 2, our new generation of world-action models (WAMs): it imagines how the physical world will unfold and generates the actions that get it there. One model runs on parallel grippers, dexterous hands, and humanoids.
research.nvidia.com/labs/gea…

Kun Lei retweeted

Reliable real-world manipulation requires policies that can improve from deployment experience.
Introducing PIVOT: Policy Improvement via Trust-Region Optimization from Deployment Experience — accepted to CoRL 2026.
PIVOT combines demonstrations, human corrections, and autonomous rollouts in an iterative post-training loop, producing consistent gains across precise, contact-rich bimanual tasks.
Kun Lei retweeted
We built a robotics data engine with Astra-level performance at 125x lower cost. And we are open-sourcing the weights today! Introducing Flora, a suite of open models to parse the physical world and turn raw footage into rich training signals.
Flora already powers our in-house data engine, labeling 200K hours of videos a day on 500 GPUs. We created it to scale the frontier for robot learning. Now you own the weights too.
Flora gives you:
- High-quality, timestamped captions to curate and filter human egocentric and robot data;
- Dense progress rewards for quality control and RL post-training;
- Rubrics scoring for real-world benchmarking
Try it today, links in thread:
Kun Lei retweeted

Some robots cannot be caged.
RoboAPI is live. Your robot can stop rehearsing.
One prompt. That's the whole API.
Run agentic research with it. Rebuild a physical workflow with it. Hand it a room it has never seen — and watch.
Zero-shot generalization used to be the goal. Now it's the floor.

Don't trust demos. Try it yourself.
Introducing RoboAPI, powered by Poke-Aurora, our world-action model.
Give compatible robots natural-language instructions through a simple API. No task-specific training.
More information: pokebot.com/ai
Kun Lei retweeted

A million hours of what?
If we’re scaling human demonstrations for robot learning, what should each hour contain?
We built S1, our skill capture glove, alongside our robot hand to record joint movements that map to robot targets, with touch and video on the same timeline.
I can see why teleoperation is often viewed as the upper bound. Personally, though, I wonder whether something like Dex-UMI could get even closer to the upper bound of dexterous manipulation, assuming the finger IK/retargeting is accurate enough.
Imagine threading a nut onto a screw in the dark. You can still do it because your fingers continuously sense contact and make tiny corrections to position and orientation in a closed loop. Those contact-driven micro-adjustments are naturally embedded in the human demonstration trajectory.
My intuition is that some of these fine-grained corrections may be filtered out during teleoperation because of retargeting, embodiment mismatch, latency, or limited feedback. In that sense, Dex-UMI may preserve more of the original human manipulation behavior, rather than only the intended robot motion.

Teleoperation is the upper bound of manipulation, as always.
And...
People do not really understand what it means when we talk about @SharpaRobotics's teleoperation SYSTEM here.
Hardware layer:
Body (very fast arm movements and whole-body coordination; guessing there's some new drive architecture here, like cable drive), hands (in-house, high-DoF, robust dexterous hands, among the best in the world), cameras (real-time streaming of high-res images with extremely low latency, you can tell).
Control layer:
Whole-body IK and such well-tuned end-effector tracking that you can barely perceive any latency. The control delay feels like 0 ms.
Data devices:
VR + an in-house exoskeleton. Sharpa built it in-house because no one else was delivering the quality they wanted.
Nothing fancy here. Just solid, grounded work. This is robotics.
wow

We’re trying something new at the R2RL Workshop at CoRL 2026. 🔗 r2rl-workshop.github.io/
No senior-speakers, no passive audience.
Key Q: What are the real bottlenecks in Sample-efficient, Real-World RL?
🧑🔬 No senior speakers. Students & scientists who actually deploy RL on robots.
🗳️ Crowdsourced problems. Audience proposes challenges, we all vote on what to focus on.
🧩Breakout sessions. Audience helps to propose and discuss solutions for top-voted problems.
🎤 Panel. The breakout discussions determine what we debate.
📝 Whitepaper: a community-constructed whitepaper summarizing the most urgent challenges for Real-World RL in the next year.
Submit your papers!
Attend to help us figure out what we should actually be solving next!
Submission deadline: September 30

2
12
1,919
Kun Lei retweeted

We’re trying something new at the R2RL Workshop at CoRL 2026. 🔗 r2rl-workshop.github.io/
No senior-speakers, no passive audience.
Key Q: What are the real bottlenecks in Sample-efficient, Real-World RL?
🧑🔬 No senior speakers. Students & scientists who actually deploy RL on robots.
🗳️ Crowdsourced problems. Audience proposes challenges, we all vote on what to focus on.
🧩Breakout sessions. Audience helps to propose and discuss solutions for top-voted problems.
🎤 Panel. The breakout discussions determine what we debate.
📝 Whitepaper: a community-constructed whitepaper summarizing the most urgent challenges for Real-World RL in the next year.
Submit your papers!
Attend to help us figure out what we should actually be solving next!
Submission deadline: September 30
Kun Lei retweeted
Thrilled to see RL-100 featured on the homepages of both Science and Science Robotics! 🎉
science.org/
science.org/journal/scirobot…


Thrilled to see RL-100 featured on the homepages of both Science and Science Robotics! 🎉
science.org/
science.org/journal/scirobot…
Kun Lei retweeted
A new approach combines imitation learning and reinforcement learning, facilitating robot manipulation tasks such as folding a towel even when facing obstacles or variations.
Learn more in Science #Robotics: scim.ag/4bAs2g4
Kun Lei retweeted

good job RL-100

A new approach combines imitation learning and reinforcement learning, facilitating robot manipulation tasks such as folding a towel even when facing obstacles or variations.
Learn more in Science #Robotics: scim.ag/4bAs2g4
RL-100 is now published in Science Robotics! The code is fully open-source at github.com/Lei-Kun/RL-100. Try training your first 💯 robot 🤖

A new approach combines imitation learning and reinforcement learning, facilitating robot manipulation tasks such as folding a towel even when facing obstacles or variations.
Learn more in Science #Robotics: scim.ag/4bAs2g4