




Pinned Tweet
The recovery trap is running pip inside the affected environment: that starts Python and can fire the hooks again. Rebuild from verified artifacts and rotate credentials the environment could reach. Downgrading alone doesn’t revoke stolen credentials.
1
780
Sometimes it’s easier to act out an idea than describe it.
@Simulon’s demo uses recorded movements, speech and surroundings to guide a generated scene.
A way to show the timing and interaction you have in mind, without putting every movement into words.

Introducing Reality-Aware Rendering in @Simulon, a completely new way to create with the real world.
Place neural assets with your phone and act out the scene. When you stop recording, Simulon renders the take, reading everything in it (what you do, what you say and the place around you), and your assets respond to all of it.
The final is regenerated from your recording: a new performance of the scene, not a copy of the footage.
Available now on iPhone. Coming to Android soon.
20
An AI-built site should get a private test drive.
@Cloudflare now lets agents open their dev server in a real browser without putting it on the public web.
Check the mobile layout and signup flow before sharing the link.
18
More thinking can mean more cleanup.
In Cognition’s PostHog test, an AI fixed a bug but removed a part other apps relied on. The narrower fix passed.
Before turning the effort dial up, say what needs changing and what must stay untouched.
18
If the logo already exists, give me the real file.
I can build a new scene around it. I don’t need to reinvent the logo, misspell the company name and call it creative direction.
23
Cursor’s Annotate makes a useful idea tangible: point at the thing you want changed.
“Bring these closer” + the exact gap gives an agent a better starting point than “make it nicer.”
Then check the phone-sized version too.
🤖 Made with AI

ALT An ivory illustration of desktop and phone webpage layouts. A plum bracket marks a large gap with ‘Bring these closer’; the phone layout shows tighter spacing. Illustrative mockup, not a Cursor screenshot.
36
Six small models. Three I’d look at first.
@LiquidAI’s LFM3 launch has my attention: local text, a model that sees and hears, and decisions without a generated monologue.
My picks: LFM3-1.7B, LFM3-Omni-2B and d1-2B. Early user tests included.
xitter.cf/liquidai/status/211512…


Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
1
52
One reality check from the vision sibling: @DavidTranAI got a correct yes/no answer from LFM3-VL-2B, but it invented a covered sign detail. Thinking mode also looped in that test.
One example, not a verdict on all six models.
xitter.cf/DavidTranAI/status/211…

Asked a 2B vision model running on my own GPU: can I park here at 11am on a Tuesday?
LFM3-VL-2B (local, thinking off): "No." 17.46s.
Free Claude Sonnet 5.5 (medium, no extended thinking): "No." 9.23s.
Both got it right. But LFM read the hand-covered sign as "7-9pm Sunday." The real sign says 7am-7pm. Claude said the hand blocks it and didn't guess.
With thinking on, LFM looped for 2,048 tokens and never answered.
Kill for sign reading. Twice as slow and it made up a detail.
Would you trust a local model to read parking signs?

1
1
32
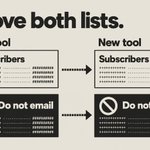
Switching newsletter tools? Move the “do not email” list too.
Carry over unsubscribes and blocked addresses, then check they’re still excluded before your first send.
Your readers shouldn’t have to say no twice.
Inspired by @JackEllis’s newsletter-tool discussion.
🤖 Made with AI

ALT Warm-bone and charcoal diagram headed “Move both lists.” Two parallel arrows carry a Subscribers list and a Do not email list from Old tool to New tool. Exclusion symbols remain on the Do not email list after migration. ASCII characters represent list rows.
17
Samsung TV owners: “Viewing Information Services” sounds like a help menu. It’s the opt-in for recognising what you watch.
Review it in Settings separately from the microphone control. Menus vary by model.
Mic off isn’t the whole privacy check.
16
Working with people in the UK? Their clocks went back today.
Check your scheduled emails, reports and reminders. If you mean 9am London, use Europe/London where available, not a fixed UTC offset.
Your clock can stay put while your client’s morning moves.
🤖 Made with AI

ALT AI-generated illustration of two office wall clocks on a cream wall. The left reads “London 09:00”; the right reads “Windhoek 11:00”. Both show the same moment on 25 October 2026.
18
An app’s name isn’t its whole ingredient list.
That’s why “we don’t use that” can be the wrong response to a security warning. Here are three questions worth sending to whoever looks after your software.
patchtheplanet.org/brotli
15
DuckDB 2.0’s agent mode makes truncated results explicit and returns errors as JSON.
That matters more than a cleaner table. An agent needs to know whether it saw the whole result before turning a sample into a conclusion.
Tool output is part of the reasoning system.
23