

Solutions Architect @ OpenAI. Prev Principal Engineer at Pioneer Square Labs, Startup Founder, ex-Microsoft. I also make AI coding videos.
Seattle
Joined March 2007
- Tweets3.3K
- Following2.7K
- Followers2.7K
- Likes5K




Pinned Tweet
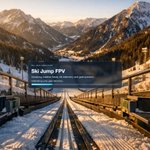
🏂❄️ Ski Jump Simulator 🏂❄️
This was my first real wow moment with the new Codex app + skills + codex-5.3. I was able to ship a playable, physics-based sim even though I’ve never built a game before!
🧵on tips / lessons learned
ski-jump-sim.vercel.app/

Kevin Leneway retweeted

Today we are announcing Harvey LAB-AA v1.1 in collaboration with Harvey. This updates our scoring methodology for the Legal Agent Benchmark (LAB) to add a hallucination check and require correct responses to not include material misstatements. LAB-AA v1.1's new headline metric, Hallucination-Gated All-Pass Rate, only credits a task when the deliverables satisfy every rubric criterion and contain no material hallucinations.
We define a material hallucination as one that would mislead a reader on a substantive point, such as a wrong contractually required date, while a minor hallucination is a real error that is unlikely to meaningfully affect the legal interpretation of a deliverable. Minor hallucinations are reported separately and do not affect the headline score.
Grok 4.7 (xhigh) leads at 9.4% Hallucination-Gated All-Pass Rate, and >60% of otherwise passing results across the models tested at launch contain a material hallucination.
This is the first step in enhancing the methodology for Harvey LAB-AA. In future updates, we’re working with Harvey to better account for the full set of factors lawyers value, including usability features like style and tone.
Key takeaways:
➤ Top of the leaderboard: Grok 4.7 (xhigh) from @spacexai leads at 9.4% Hallucination-Gated All-Pass Rate, narrowly ahead of Muse Spark 1.3 (max) from @AIatMeta at 8.9% and GPT-6 Astra (max) from @OpenAI at 8.6%
➤ Hallucinations reshape the leaderboard: without the hallucination gate, Muse Spark 1.3 (max) would lead clearly with a 26.7% all-pass rate, but two thirds of those passes contain one or more material hallucinations, resulting in a Hallucination-Gated All-Pass Rate of 8.9%. GPT-6 Astra (max) retains almost all of its passes after the hallucination gate (8.9% to 8.6%) and moves from joint 10th to 3rd
➤ The GPT-6 model family is the most grounded: GPT-6 Astra (max) averages 0.03 material hallucinations per task (4 across all 120 tasks) and GPT-6 Sol (max) averages 0.07. When comparing six checker models on a 20-task subset, GPT-6 Astra had zero material hallucinations under every checker, including Claude Opus 5.5 (high). By comparison, Gemini 3.8 Flash (high) averages 13.96 material hallucinations per task.
➤ Top-scoring models aren’t the most expensive: Grok 4.7 (xhigh) takes the top spot on the leaderboard at a cost of ~$9.50 per task, under half the cost of Claude Fable 5.1 (max with fallback) at ~$21.70, the most expensive model. Muse Spark 1.3 (max) represents strong performance for its cost, landing in second for ~$4.20 per task
Thank you to @nikogrupen and @ItsJulioPereyra from @harvey for their work on Harvey LAB and collaboration.

Kevin Leneway retweeted

Congrats to the @OpenAI team on launching GPT-Live. 🎉
It sounds more natural. We ran it through 80 real restaurant booking calls first: task completion more than doubled over the previous generation, with 92% perfect comprehension.
Interruptions are smoother. A quiet "mm-hmm" no longer stops it, and if you ask something new mid-sentence, it switches without a pause.
It's live in Genspark today. Now in Call for Me, Realtime Voice Agent, and something new: you can call your agents in GenTeam. Hand off work, ask where things stand, review results. Just like calling a teammate.
See the demo 👇

Kevin Leneway retweeted

GPT-6 Astra is live now on OpenRouter!
Reaction from internal testing: "It's incredibly steerable, you can mold it to be whatever you want. A very different experience from any other model. It's like truly Personalized Intelligence"
Use it now: openrouter.ai/openai/gpt-6-a…

Kevin Leneway retweeted
🚀 Introducing Genspark AI Workspace 6.0, our most ambitious release yet.
The idea behind 6.0 is simple: AI's next breakthrough isn't models. It's context.
Even the most powerful model starts from zero if it doesn't understand your projects, team, inbox, meetings, files, and decisions. Today's AI is a genius with a goldfish memory, every conversation starts from scratch.
Genspark 6.0 changes that, moving AI beyond one-off generation into a workspace where agents remember, build, collaborate, and act.
What's new:
The biggest update is SecondBrain, your own personal memory system. Connect your emails, meeting notes, IMs, docs, apps, and Genspark projects into one context layer. This way, Genspark Super Agent can work from everything it knows about you, more personally and intelligently.
And to feed your SecondBrain, meet our first hardware, SecondBrain Note. A card-thin AI voice recorder. Press once to record up to 35 hours. Every meeting automatically becomes AI notes that flow right into your SecondBrain.
For teams, we've reimagined Genspark Teams into GenTeam. A workspace where your team and AI agents chat and work side by side.
For the office suite, we've upgraded the AI Inbox into GenMail. An app for both desktop and mobile, with an email agent built on an email brain that knows you and handles your inbox 10× faster.
For the build suite, we've added Genspark Design and AgentBase. Design takes you from rough idea to professional, production-ready design, prototypes, videos, posters, and more. AgentBase is an agent that builds custom dashboards, CRMs, and internal systems from your data.
And AI Slides gets even better. New Slide Skills make every deck think like an expert, and a redesigned canvas makes editing smoother.
Come try the new Genspark 6.0 today: genspark.ai/
🎁 To celebrate 6.0, we're giving away free credits, details in the thread.

Kevin Leneway retweeted

I started INT21 two months ago, and I’m proud to announce that we’re coming out of stealth today with our first product: PTX Kernel Factory. We’ve created the first self-improving agent swarm for producing expert-level PTX kernels autonomously and at massive scale. int21.ai


Powerful new design pattern I’m experimenting with.
MVC: Model, View, Codex
Define the model and build persistent storage, design the front end, encode the business logic + API schema as skills/plugins. Then just chat with Codex + in-app browser. Works surprisingly well!

Kevin Leneway retweeted

And I’m not talking about point of no return to Claude Code. If they release a model that’s better, great.
I’m talking about using an agent interface (super-app) for ALL tasks.
I don’t go to a browser anymore. I don’t go to email. I don’t go to notion.
Every task that is started is kicked off via an agent chat.
I believe over the next year this is inevitable for all knowledge work.
If your app doesn’t open in the superapp browser you may be…
Cooked.

Kevin Leneway retweeted
The incredibly powerful new GPT Image 2 model from @OpenAI is live on OpenRouter as openai/gpt-5.4-image-2
Using OpenRouter's GPT-5.4 Image 2, you get the image gen capabilities of Image 2 alongside the prompt improvement of GPT-5.4.


I've been trying out Shortcut with GPT 5.4 today. It's super impressive, nice job on this!

We had early access to GPT 5.4 to benchmark on @tryshortcutai and it is extremely good at Excel
Here is a quick walkthrough of two real-world tasks in our internal eval of 50,000+ cells each
Watch, because the industry is way beyond the same flashy and meaningless DCF demo
But overall, it was very fun to build a full working game end-to-end and Codex is surprisingly good at making games.
Give it a shot! My high score is 112. If you beat it, reply with a screenshot 😄
ski-jump-sim.vercel.app/

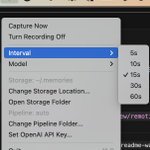
Weekend project - cron job to screenshot my laptop every five seconds, then use a codex automation to take notes and eventually create skills for my repetitive tasks.
Oh no way it worked lol. Shoutout to ClawVault for the "primitives" idea. It even one-shotted out a swift app for the menubar, and just for fun I made a Remotion video of the readme! 😂
github.com/Versatly/clawvaul…
