

I've been running 20 coding agents in parallel, merging around 20 PRs a day into production.
Here's how I manage context, traceability, and agent collaboration without a central orchestrator.

It seems we’re reaching the point where improvements in model capabilities are becoming marginal. Increasingly, the key differentiators are memory, orchestration, and the ability to learn on the fly.

Can AI learn from its own traces?
To build a true continual learning system, I had to answer the following questions.
- What is in the agent traces?
- Where should model store the learning?
- Which it should supervise from?
- How do you learn from failed experience?
- Which learned capability should it route to?
To close the loop. Did more than 40 experiments. Shared our findings in 7 research reports.
From Learning From Your Own Traces to The Loop Running End to End
Link to the first article below👇
Shared memory is not only for the agents. You can ask anything about your team and agents activities to our whatsapp bot.

Sasun Hambardzumyan retweeted

Every eng team working with agents now has the same problem: documentation is outdated the moment it's written.
So we made it self-updating.
Hivemind already turns your coding agents' traces into skills. Now that same pipeline maintains your docs.
As your agents learn, your documentation stays current.
Because everything traces back to source, two things get dramatically easier:
• If you get a new team member, they onboard on docs that reflect how things work today.
• Something sticky happens with an agent? See exactly what led to the choices it made.
Get started with Hivemind and stop manually shuffling with docs today.
Sasun Hambardzumyan retweeted
We have 3 new updates to Hivemind that are in service of our mission: making organizational agents more cost efficient and effective.
1. Proactive search experience for Claude Code + Cursor. After each user prompt, Hivemind automatically searches for relevant stored traces from the past and passes them to the agent as additional context. This improves reasoning and output.
2. Ability to share skills across teams and devices. Skill sharing is a simpler feature: it syncs the skills a user already has in their system through Deeplake, so everyone on the team can access them. Previously, we were more focused on generating and improving skills. This is about sharing existing skills across the team.
3. Ability to create and assign goals. Any teammate can create and assign goals to another that can persist across sessions until marked completed. Agents can automatically reason when the goal has been reached, and will notify the creator of the goal automatically.
All of these new features work to level up your team, reduce errors and redundant work and lower AI token spend.
Get set up with one command line install.

Sasun Hambardzumyan retweeted

Really excited to see that the project I’m leading, which we officially released four days ago, just got its first 1K GitHub stars, with 300+ gained in the last 24 hours.
It also reached #2 Repository of the Day on GitHub.
Really proud to be building this with @KamoAghbalyan, @khustup, @DBuniatyan, and the rest of the team.

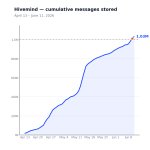
Hivemind crossed 1 mln messages in less than two months.
That’s 1 million messages stored and served back to customer agents through search and memory recall.
Along the way, Hivemind autogenerated hundreds of reusable skills, saving thousands of hours and millions of tokens that agents would otherwise spend repeating work they had already done.

Big update on Hivemind.
Autogenerated skills require ongoing maintenance.
SkillOpt solves that by continuously optimizing skills, and it’s now available in Hivemind.
Coding agents that actually get better the more your team uses them.
Introducing Hivemind: continual learning for AI coding agents.
Hivemind turns the traces from every agent your team runs (Claude Code, Codex, Cursor, Hermes, OpenClaw, Pi) into reusable skills, then pushes those skills across all of them. All on your cloud storage.
Now with SkillOpt built in, your skills get trained: +19.1 points of accuracy in Claude Code, +24.8 in Codex, best or tied on all 52 setups tested.
Open source, one line install.
Sasun Hambardzumyan retweeted

Physical AI still requires manual annotation despite all advancements in visual understanding.
@activeloop collaborated with @AgentField_ai. outcome is Roboscribe-AF to automatically annotate multi sensory data with an agentic swarm.
how it works
> AgentField runs the reasoning graph to produce new annotation rows
> Deeplake stores the corpus and annotation versions
> raw and derived annotation fields share one schema
> disagreements between the visual and action reasoners become queryable dataset fields
> all open source
Read guest blogpost below.

Agentic LLM systems this year have mostly gone to coding, browsing, research.
With the @activeloop (Deeplake) team, we pointed agents at a job they don't usually do: curating a robotics dataset.
Roboscribe-AF automates the work a human curator would do — segment episodes, cross-check video vs trajectory, flag the messy ones.
Disagreements between reasoners get written back as queryable Deeplake fields.
Open source: deeplake.ai/blog/agentfield

Sasun Hambardzumyan retweeted
Hivemind just crossed 250 stars on github
2K weekly downloads on NPM. 🚀
Connect coding agents to a shared brain
> Collect traces into deeplake
> Auto-optimize skills
> Share across agents, machines and teammates
Your agents continuously learn from each other's experience.
Get them to compound your intelligence.

Hivemind just crossed 100 stars on github 🌟
github.com/activeloopai/hive…
Beyond memory. Let's compound intelligence!

Sasun Hambardzumyan retweeted
Hivemind just crossed 100 stars on github 🌟
github.com/activeloopai/hive…
Beyond memory. Let's compound intelligence!
today, we're going beyond memory.
your org's agents shouldn't just remember what happened. they should learn from their experience.
Hivemind takes agent traces and codifies them into skills every agent on your team can use.
> no more explanations
> no more duplicate work
> no more repeat bugs
we make your intelligence compound.
here's how 👇

In April, we started Hivemind as a use case for Deeplake. A month later, it turned out that Deeplake is actually a use case for Hivemind 😁
Our development process leveled up dramatically. By sharing experience across different sessions, engineers, and agents through a single plugin installation, the system continuously improves itself. It works seamlessly: install the plugin once, and you’ll notice the difference after just one session.
today, we're going beyond memory.
your org's agents shouldn't just remember what happened. they should learn from their experience.
Hivemind takes agent traces and codifies them into skills every agent on your team can use.
> no more explanations
> no more duplicate work
> no more repeat bugs
we make your intelligence compound.
here's how 👇


My recent thoughts on how AI will reshape collaborative work led me to this conclusion:
The bottleneck is no longer the number of people in a company, but the number of productive experiments the company can run in parallel.
In the AI era, work shouldn’t stop between humans. Sessions with tools like Claude Code should be continuous.
A key requirement for this to work is strong information and experience sharing across team members.
Jack's right: "Companies move fast or slow based on information flow." But framing it as a worker hierarchy problem is losing the plot.
Look at where the actual work is moving: agents.
Quick history:
Email got messy. Slack fixed it.
Then humans kept dropping balls anyway. Someone's offline, a thread dies, marketing has no idea what eng shipped, the handoff never happens.
And now Slack itself is the slog. What if you could spend a fraction of the time in it?
Meanwhile, your agents are in the pre-Slack era:
• Your Claude Code agent has no clue what your coworker's OpenClaw agent decided yesterday.
• Marketing's agent can't see what sales's agent promised the customer.
• Product's agent has no idea what engineering's agent already shipped.
Same company, same project, totally separate brains. The fastest workers on your team are stuck on the slowest part of your stack.
Deeplake Hivemind fixes it. One install and your agents share memory across sessions, across teammates, across tools: Claude Code, OpenClaw, Codex, whatever.
When one agent learns something, every agent on your team knows.
No Slack pings. No status updates. No "wait, did you tell the VP?"
Just shared context, flowing automatically.
Slack was for humans. Hivemind is for the things actually doing the work now.
Comment HIVEMIND and we'll DM you $100 in free credits. Run the experiment with your crew.
We published a deep dive into our serverless postgres architecture, including some non-trivial architectural decisions we had to make along the way.
Would really appreciate feedback from others working on similar problems or operating systems at scale.
A banger post by our CTO @khustup on how he made Postgres Serverles and spin up under second.
We built a serverless, PostgreSQL-compatible database. Not a modified PostgreSQL deployment.
PostgreSQL provides the interface. DuckDB provides the query execution. Deeplake provides the storage engine.
The architecture makes a different set of tradeoffs than traditional PostgreSQL.
We think those tradeoffs are right for agent workloads: bursty, ephemeral, storage-heavy, and analytical.
Link: deeplake.ai/blog/serverless-…