




josacar retweeted

In Spanish:
Santa Fe (New Mexico) means holy faith
Albuquerque is named after the Spanish Duke of Alburquerque
Nevada means snow
Las Vegas is meadows
Florida is named after La Florida, or the flowery one
Los Angeles is “the angels”
California is actually from Spanish literature but is derived from Khalifa in Arabic, meaning “caliph” or leader. Note the closeness to Caliphate lol
San Diego, San Francisco, San Antonio, are Spanish Catholic saints.
Sacramento means sacrament
Colorado means colored with a red tint
Texas is Tejas, named by Mexicans from the Cado Native American word taysha
El Paso is “the pass” referring to the mountain pass along the Rio Grande (big river)
I could go on…
Trump will stay busy renaming and making the U.S. basic and boring like the food without ethnic spice. Pretty fitting for this administration. 🤡


josacar retweeted

New addition to our data rankings: Open vs Closed model share.
Open-weight models processed 73% of total tokens so far this week.
Dance through the data yourself at openrouter.ai/rankings
We are also accepting suggestions for new public charts!

josacar retweeted

We proudly present: Crystal 1.22
Our newest and shiniest release 💎
It's also the biggest release since 1.0 with 251 changes in total.
crystal-lang.org/2026/10/12/…
josacar retweeted

What actually changes:
- Deno runtime: 1 more year of monthly releases, stays open source
- Deno Deploy: 6 more months, migration help to Workers
- JSR: stays, moves to Cloudflare
- rusty_v8 is heading into workerd

We are excited to announce that Deno is joining Cloudflare!
deno.com/blog/cloudflare

josacar retweeted

LaLiga anti-piracy strategy so far:
1⃣ Block Cloudflare, breaking half a million unrelated websites, including banking apps.
2⃣ Put Proton VPN on a piracy watch list over blogs neither we nor our affiliates wrote.
➡️ Next up: banning WiFi because pubs use it to show the match.

LaLiga wants the EU to put major VPN providers including NordVPN, ProtonVPN, ExpressVPN and Surfshark on its piracy watch list.
The league argues that some VPN companies promote their services through affiliate websites that tell users how to bypass geo-blocks and access pirated sports streams.
Whether the EU agrees is another question
torrentfreak.com/laliga-want…


josacar retweeted

CloudFlare AI Agentlar için security-skill yayınlamış, direkt yapıştıralım 👇
github.com/cloudflare/securi…

josacar retweeted

🔴 ESCÁNDALO OPEN DATA: parece que @AEMET_Esp ha decidido salirse del sistema europeo Open Radar Data (ORD) de EUMETNET y bloquear el envío de datos de radar individuales financiados con dinero público.
Mientras toda Europa comparte sus datos brutos, AEMET nos deja a ciegas:
❌ Se acaban los escaneos volumétricos (ángulos de elevación)
❌ Se apagan los datos de viento Doppler
❌ Destrozan la capacidad de análisis avanzado en proyectos abiertos como radarspain.es.
¿Por qué @mitecogob y @AEMET_Esp recortan el acceso a la información pública?
Exigimos que reactiven el volcado de datos de inmediato.

josacar retweeted

"The term ‘code review’ is hugely overloaded”. Charity Majors(@mipsytipsy), cofounder & CTO of Honeycomb, on why validation was never the most important part:
“Code review means so many things to so many people in so many places. There's a lot of projection going on. For a lot of people, if you say that you don't want code review, you're saying you don't want to talk to your coworkers, you don't want to mentor juniors. Which is not true.
We've just bundled so many things into this hugely overloaded tool. Some of those things are really good. Some of those things could be done better in other ways. Some of those things are very cultural, very specific.
My friend David Poll, who is now working at GitHub on pull requests, said: "To me, the code review is when we decide, do we want this in our product or not?" That's a great discussion. That is what humans are good at!
We should talk about: is this mental model coherent? Should we add this? Should we not? Architectures. But the code is not necessarily a great artifact for all of those.
So should we be talking to people? Yes. Is the code review the right form factor? Maybe. I think that the emotional reaction that so many people are getting to the validation, in my book, it’s at the very bottom of the list.”


josacar retweeted

Introducing GLM-5.3: Built to Code. Ready for Cyber Defense.
- Top-tier coding and agentic capabilities, achieved through post-training on the 743B base model
- A major leap in cybersecurity, setting a new standard among open models
Tech Blog: z.ai/blog/glm-5.3

josacar retweeted
I'm a Crystal @CrystalLanguage Core Team member and I created Kemal @crystalkemal (3.8k+ ⭐, 5M+ downloads).
I've been building Crystal tools since 2015. Now I'm working on gcry, a %100 Crystal garbage collector for Crystal. Already at ~89% of Boehm GC throughput with ~0.95x RSS.
I also maintain the entire Kemal ecosystem, run Crystal Weekly and Crystal Community, and write free books in Turkish and English.
I can't find a job right now. So I'm going full time on Crystal Open Source. I need $1,000/month to keep doing this.
If my work has helped you or your company, please consider sponsoring.
👉 github.com/sponsors/sdogruyo…
Be part of Crystal's future. 💎
#crystallang


josacar retweeted

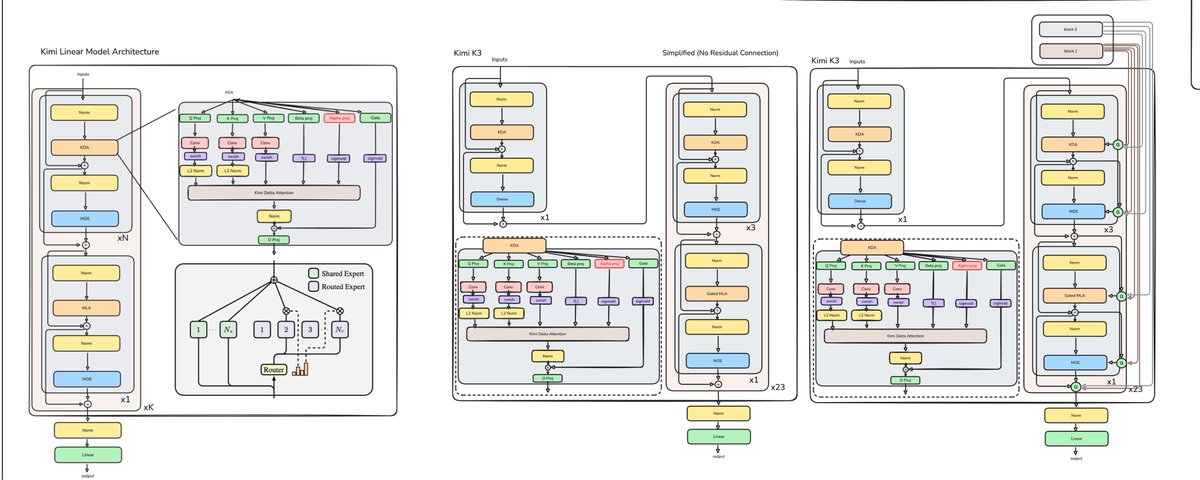
Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: huggingface.co/moonshotai/Ki…
Tech report: github.com/MoonshotAI/Kimi-K…
Tech blog: kimi.com/blog/kimi-k3

RT @Alibaba_Qwen: Qwen3.8 is launching and going open-weight soon!🌐
With a massive 2.4T parameters, this model is continuously evolving. W…
josacar retweeted
A new release is out: Crystal 1.21.0 🚀
We've reached a major milestone with making Execution Contexts the default concurrency model. crystal-lang.org/2026/07/12/…
Read more about the release at crystal-lang.org/2026/07/16/…
#crystallang #release
josacar retweeted

DeepSeek just released DSpark for V4 Flash & Pro, a new speculative decoding method boosting throughput by 51% to 400%!
DS also showed DSpark works well for other models like Gemma & Qwen
Github: github.com/deepseek-ai/DeepS…
Paper: github.com/deepseek-ai/DeepS…
HF: huggingface.co/deepseek-ai/D…

josacar retweeted

How to keep AI spend flat while token usage grows exponentially: Not with friction and spend alerts. With better defaults, routing, and caching.
Better Defaults (not Usage Caps) – Engineers can choose any model they want, but defaults matter. We’re experimenting with defaulting to open weight models like GLM 5.2 and Kimi 2.7 through our LLM gateway, while still encouraging engineers to choose the right model for the task. 91% of our employees were never hitting their usage caps, so instead of lowering caps and driving up alerts, we're moving to cheaper defaults. Note that code reviews use a diversity of models, so they can check each other's work.
Better Routing – In our custom harnesses, we preprocess prompts and route to the best model for the job, considering cache hits and model pricing. For instance, you may want a frontier model for planning, but not for execution where they can be overkill. Ultimately, humans shouldn't be choosing models - AI can automate this task.
Better Caching – Cache misses are the easiest way to drive your cost up. All of our requests are cache aware, so we’re reusing a warm cache wherever possible. For example, our cache hit rate went from 5% → 60% in LibreChat once properly implemented.
Keep Context Lean – Start fresh sessions when switching tasks. Scope file context narrowly. Disconnect unused tools. Don't just compact. The goal isn't fewer tokens used, it's fewer tokens wasted.
Better Visibility – Our engineers can use as many tokens as they want, from whatever model they want, but we’ve made usage visible – and the more you spend on AI, the more impact we expect.
The goal isn't to suppress usage. It's to build the infrastructure that makes exponential growth sustainable.
Putting this into practice has cut our AI spend nearly in half, while our token usage continues to grow.

Hola @EmbEspTailandia, tengo planeado ir a Tailandia mas de 30 dias, pero thaievisa.go.th aun dice que no hace falta. En el portal de la embajada si madrid.thaiembassy.org/en/pa… Menudo lio.
