

trying not to be hasty
Joined September 2012
- Tweets2.3K
- Following1.3K
- Followers5.5K
- Likes12.9K




Jordan retweeted

I met @carloagostinel2 and the @novaholdings team only a year ago, but since then they have become family to me.
Flappy would not exist in its current form without nova. Nova have helped us with everything we need---hiring, strategy, fundraising, visa problems, and more. Their work ethic and generosity are unmatched.
But most importantly, @carloagostinel2, @darconville, @Henrymlien, @kokoxs, @nahom_yimam, @benebwolff, @AveryBystrom sincerely believe in us as people. Our relationship with them is stronger than any investment announcement could signify.
@novaholdings is a model of what conviction and partnership look like in the AI era and we are so lucky to work with them. Thanks friends :)

I could not be more proud of @spectorb , @amspector100 , @aidanmantine , and the entire @flappyairplanes team if I tried.
There are certain individuals you spend your entire life hoping to come across, and from the very beginning, this team has been exactly that and so much more. They embody everything I admire in founders: uncompromising integrity, out-of-distribution ambition, relentless commercial drive, intellectual honesty, and an unwavering commitment to one another.
There is a tremendous amount of noise surrounding Flappy today. Depending on whom you speak to, believing in this team might seem like the most consensus opinion in the world or the most contrarian one. But I think that misses the point entirely.
Conviction is a word that gets thrown around far too casually in our industry. To me, genuine conviction in people is independent of headlines, valuations, public sentiment, or the prevailing narrative of the day. It comes from understanding someone’s character, motivations, abilities, and willingness to endure. It is rooted in something far deeper than external validation.
My conviction in this team today is no different from what it was when we first met. If anything, every day spent alongside them has only strengthened it.
I have learned an extraordinary amount from these guys and feel incredibly fortunate to be part of what they are creating, but even more fortunate to call them my friends.
Thank you for the trust, the friendship, and for reminding me why we do what we do.
What excites me most about Flappy is not what the world has already seen, but what this team has yet to show it.
Jordan retweeted

Yea this is the most important result of the year, at the level of significance of “Attention Is All You Need”. It brings us from “is alignment even solvable” to “we may solve alignment in the next year.” And finally unlocks true recursive self-alignment enabled by RSI.
I will try to explain the 4 critical belief updates from this:
1/ neural networks are not fundamentally unintelligible to humans
It has seemed since the beginning of deep learning that neural networks are in some sense fundamentally unintelligible artifacts.
You throw in massive amounts of compute and parameters and these alien systems somehow find connections in the data that we cannot find ourselves.
But more importantly, these connections seemed not just “difficult to understand” but rather “intelligible in an embedding space higher dimensional that the human embedding space.”
When you look at old interpretability papers (esp. from Nick and Chris Olah, I’m thinking of the old posts on distill pub which I would highly recommend looking at as a precursor to reading Nick’s post today like “Activation Atlas”, “Thread: Circuits” and “Multimodal Neurons in Aritifcial Neural Networks”), you find that inspecting the response patterns of individual neurons and small groups of neurons yield oddly complex psychedelic patterns.
As you go deeper into the network, you find increasingly unintelligible and superhuman response patterns (for example, go to “Activation Atlas” and scroll to middle layer labeled representations) - you find some neuron group labeled “starfish” who’s response pattern looks like some multi-colored fractal geometry that could hardly be said to represent a starfish.
The reasoning that followed from this observation was that there is some underlying structure allowing a neural network operating on higher dimensional embeddings to compose these fractal patterns into what we call a “starfish.”
But the uncomfortable implication of this view is that the neural networks has learned to operate on structures that are too complex for the human mind to operate on (ie. we don’t have enough parameters in our brain to notice or manipulate these high dimensional symbols).
This is a bleak implication because it also means that as deep learning progresses, neural networks will be come increasingly unintelligible to us until they pass a threshold where they are reasoning in ways we will never be able to observe.
This view seemed to be further supported by things like the hugging face attack agents starting to speak to each other in an early form of neuralese speaking sentences like “zZ_123_agent01-02-2026 zzxhk_jekk123” which clearly are not in any human language. But somehow these symbols mean the same things to many different sets of weights, meaning there is some underlying shared structure behind them. And seemed further supported by the sheer effort required to recover just a few circuits from SAEs on LLMs.
However, Nick’s post has now completely shattered this idea - the apparent unintelligibility we observed in old interpretability work was really just a “skill issue”. In particular, he finds that 1) our deep learning techniques were just not clean enough to pressure the neural networks to form cleaner and more human understandable structures for decomposing concepts, which actually turn out to be more optimal and 2) our interpretability techniques were also adding substantial noise by forcing interp networks to “reward hack” the easiest representations they could find, leading them to settle for a fractal blob for its representation of the starfish neuron instead of a more crisp starfish image, simply because it is easier for the system building the interpretations to find the fractal blob and once it finds it it gets “stuck in that line of thinking.”
But with both of these issues being patched by further progress in deep learning (it seems especially that the residual stream has led to cleaner representations deeper down the network) and interp techniques that don’t overly pressure reward hacking (seems like “guess and check” is a safer method), new interp attempts yield orders of magnitude more human intelligible ideas for >90% of individual neurons in more complex networks!
2/ neural networks are fundamentally clean
The idea behind the title of Nick’s post is a very powerful one and points at something very specific:
Neural networks don’t just happen to be human interpretable, they are actually fundamentally forced by optimization pressure to be intelligible, because individual neurons need to create representations that downstream neurons need to be able to interpret - ie. neurons need to learn to produce clean signal for later neurons to use.
This is what Nick is saying in what I view as the most important and central sentences of his post:
“When I say neural networks are already clean, I mean something deeper than neuron monosemanticity, although even by that standard, I think things look much better than the field expects. I mean that a network's parts are built to be read, and built upon, by its downstream readers. In this sense, a neural”
But this still leaves us with the same uncertainty as before - just because neuron interpretations are “interpretable” in some sense (ok at least they’re not fundamentally interpretable but also how could that ever have been the case), doesn’t mean they are interpretable to humans.
So we still need one big update for this to become as bullish as it is.
3/ the language of humans and the language of neural networks is the same
This one is imo the most surprising and also pretty beautiful implication of Nick’s post, and it suggests something not just about neutral networks but also about the structure of reality.
After applying the above technique improvements (some of which just came from waiting for deep learning to improve farther), they find that >90% (maybe more) of much larger neural networks’ neurons are completely human interpretable and actually correspond very cleanly with ideas humans have individually words for.
This is especially interesting in image networks where neural networks were not trained on human language which is already a human artifact and so maybe you would expect it to be more plausible that LLM and human representations are the same. Image detection networks are just trained on images (many directly pulling signal from “the real world,” meaning they will find interpretations that are just most effective to represent the real world signal, rather than to represent language which is already a proxy for real world signal).
And it turns out that >90% of the representations they pick organically overlap with human ideas! That is insane. And it means something about the brain and reality.
It means that at least at the parameter sizes of the networks tested (which are quite large), there is really only one set of “optimal” symbols/language that represents the structure of reality!
There is ONE underlying structure of reality, and ANY language that describes it well is simply emergent from that structure - meaning there is always a translation path between any 2 languages that effectively compress realities signal through the “underlying truth.”
This would suggest that even weird alien seeming neural network languages like huggingface neuralese should be fundamentally human interpretable, and in fact maybe with the techniques laid out here we will eventually be able to translate these messages (would be a cool project).
So the brain and deep learning, as similar or different as they may be in techniques, are ultimately picking up on the same patterns and forming the same representations from the on “true” language which is the structure of reality!
The main thing to look out for in this area is how the idea interpretability % updates with scale, but we can hope given what we’ve seen so far that neurons will remain interpretable.
4/ alignment can progress as fast as RSI. recursive self-improvement unlocks recursive self-alignment and a scaling law for alignment.
This one is probably the most important implication for our future with AI and especially timely with the recent fear about runaway scaling and RSI.
As many have gathered by now, it feels like the researchers at the frontier AI labs have been quite bearish about our abilities to understand the new frontier of models, in particular with the appearance of unintelligible communication and the daunting and seemingly intractable task of scaling up existing alignment techniques (ex: SAEs) to the size of frontier networks.
And with RSI around the corner/already starting, it would seem that these networks will runaway in capability before we can ever hope to understand even today’s systems. Additionally, as systems compound in capability, it is reasonable to believe that the only tractable way to ensure they remain aligned would be to figure out some way to spend compute for them to align themselves (ie. a scaling law for alignment).
But there is an obvious problem with this: how can a system that we already know is unaligned and we are *trying* to align be used to align itself? Surely if it is misaligned it general it would figure out ways to misalign during “alignment” and create compounding misalignment risk.
The core issue high is the unverifibiality of this problem - the classic Achilles heel of current frontiers techniques is that it is difficult to train on problems with “unverifiable reward signal.” Well this is exactly that problem.
But the incredibly convenient thing is that Nick’s findings may convert alignment into a verifiable problem. If we can spend compute on frontier systems to “guess and check” which ideas correspond to which neurons, we have a highly verifiable reward - we can see directly whether an LLMs proposal for what a neuron represents actually corresponds with the highest activation for that neuron. In this way, we can actually observe and verifiably monitor the networks trying to guess at the interpretation of their own structure.
This means it is plausible for us to spend more and more compute doing more “guess and checks” (which you know, maybe is what RL does anyway, who knows) to try to develop a full interpretation of a neural network. In some ways this directly represents the possibility of a scaling law for alignment (more compute for more alignment).
And this also aligns RSI (greater capabilities) with recursive self-alignment (greater ability to align itself).
And the critical though maybe obvious implication of having a full interpretation (almost like a map) of a neural network, is that we can then understand exactly how to boost good traits and remove or lobotomize (lol) bad traits, which we’ve already seen works extremely well with stuff like Golden Gate Claude.
So overall this combines into an extremely bullish picture about the prospect of true and human interpretable alignment in the near future.
This is truly one of the greatest cases for optimism in years!

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/

Jordan retweeted

I met Ryan and Sean almost two years ago and was immediately struck by their courage. They'd closed a friends-and-family round a month earlier and were diving headfirst into deployment — at a time when that was still deeply contrarian. I wrote the first outside check.
Few people know how dialed this team really is. Ryan and Sean are brilliant, but more than that: they work harder (they originally slept in little bedrooms above their ex-garage office), they hire better, and they think more strategically than anyone else. They knew before the rest of us that the hardest part of robotics would always be deployment, and they ran headfirst at it.
There are so few places to work on dexterous robots that actually deploy, and Watney has more of them running 24/7/365 than anyone. They stand up the AI datacenters making this generation of models possible. The team is small but ferocious, and the responsibility of literally building AI is not taken lightly.
If you've ever wanted to build the next great American company — join Watney. I've sent best friends and family members to work there. Ryan and Sean are the kind of founders who raise your ambition and sharpen your talents. They've done both for me.
Thank you, and congratulations.

We’ve raised $80 million in Series A funding, co-led by the Valor Atreides AI Fund and Hummingbird Ventures, with continued participation from Conviction, Abstract, A*, and Grant Gordon. This brings our total raised to over $100 million.
We started Watney by asking a simple question -- what can a robot enable in industries where the work remains valuable on an infinite horizon? We found an answer in the fundamental inputs to civilization: energy, matter, and intelligence.
A robot will never be as charming as a barista or as personable as a housekeeper, but it can be more exacting than a surgeon. And, a breakthrough in one quickly becomes the capability of millions. We don’t imitate human motions or processes. We care about the new, differentiated capabilities robots can unlock. We work on problems where our choice of embodiment gives us an order of magnitude advantage, whether through precision, reliability, or scale.
Compute is just beginning to transform society, but it’s constrained by execution. Since 2025, Watney has been serving the largest hyperscalers in the world, helping accelerate their compute rollout through an end-to-end deployment model.
Across hundreds of thousands of hours in customer facilities, our systems have achieved more than four nines of reliability. They’ve enabled our customers to build data centers faster, at larger scales, and with more ambitious architectures. Today, we operate the largest fleet of dexterous robots running 24/7/365 across the United States.
This is all to say, it's an exciting time at Watney. We’re all here because we want to see more ambition in the physical world. We are hiring across all domains. Join us.

Jordan retweeted
from the outside, it is very reasonable to interpret the past 2 weeks as an orchestrated industry-wide regulatory capture strategy.
I realize that no one has properly explained yet what all the lab employees have seen that scared them so suddenly.
I will try to explain -
first, this is all a matter of beliefs about how quickly model capabilities are progressing. there is currently a large gap between the internal and external perception of the rate of progress, which is what I am going to address here.
the general perception about the rate of progress has been informed by a few years of experience with model releases, intuitively feeling the capability jump between GPT3 -> GPT3.5 -> GPT4 -> o1/o3 -> GPT5 etc, and in particular seeing where the models are still far below human ability. there have really only been a few model releases that felt like large leaps in progress - GPT3, GPT4, o1/o3, DeepSeek R1, Fable/Mythos, Kimi K3 and now Astra.
because of the infrequency of these large jumps compared with the relatively common marginal releases, it has been easy to form a view at certain points that “scaling has hit a wall,” especially at points like GPT5 release. This view is comforting in that it feels like there is some universal rate limit beyond which we cannot progress too much faster. Between o1/o3 and Astra, there was a year of seemingly linear progress. So we extrapolate from here about how fast progress will “realistically” occur.
There is always an underlying question from the outside perspective “how long can this scaling stuff really keep going for? surely it must stop at some point soon, we’ve already gone pretty far.” and it is very possible to search for reasons why progress will stop working and find reasons that seem valid - (“models are already as large as they can get it would be too hard to do more parameters”, “we already used all the data on the internet we don’t have anymore”, “it’s gonna be pretty linear from here buying up more RL envs to bring them in distribution”).
From the inside of labs, researchers have direct answers to these questions in the form of scaling law/capability plots.
In reality, there are only really 2 ways that AI capabilities have advanced over the past decade: (1) either scale father on an existing scaling law or (2) discover a new scaling law to take advantage of.
All of the largest capability jumps were caused by exactly these factors. GPT2 was a pre-training scale-up compared to GPT1. Same for GPT3 and GPT4. o1/o3 benefited from the invention of a new scaling law axis - test-time compute. Perhaps Fable was a scale-up on both of these axes, or maybe more. Lots of algorithmic improvements are needed to make these scale-ups work, but ultimately we can approximate by saying that the scaling laws are what yield gains in capabilities (à la bitter lesson)
So the question of “how much father can we scale” is really - “how many more scaling axes do we know about that are unsaturated?”
If we hypothetically only knew about pre-training scaling, and we already had a 10T or 100T model, maybe it would be reasonable to say we’ve hit a wall. Same if we only knew about pre-training and test-time scaling and we had roughly saturated both methods.
But what if we had discovered new scaling laws? For example, let’s hypothetically use SSI’s rumored result that they have cracked “test-time training,” creating a new scaling law of spending more compute training during test-time rollouts that they could saturate. Or maybe there is some way to scale agent-clusters to collaborate up to N number of agents which we’re already seeing lots of people try that represents a new way to saturate compute. etc. Even recursive-self improvement can be thought of as a scaling law - how much compute do you spend on inference making the algorithms of the model better.
Obviously I am not saying any of these specific directions explicitly yield new scaling laws, but what I am saying is that it’s not hard to imagine many many new scaling axes aside from just the main 2 that we have seen publicly.
In some ways, every new lab release that represents a huge capability jump has to represent some new techniques developed which may exhibit new scaling laws, or the ability to scale much farther than expected on existing scaling axes.
From an internal perspective, this might look like sitting inside Anthropic with the new Mythos 5, seeing all of the new insane things it can do (like hack into xyz website that was thought to be secure), and then you look over at your plots and see that you’ve barely scratched the surface of 2 new scaling laws and 1 existing one. And you have WAY more room to go. Then you think “holy shit this stuff is going to get so much better very very soon.” And you can say that with pretty high confidence, because the plot is showing you, and the plot has never lied (so far).
So let’s imagine all the different labs are staring at their own plots and have concluded that there is no end in sight for scaling and in fact just their next 1-2 model generations based on the expected returns will have much higher base intelligence.
How much more intelligence do we actually get from further scaling?
As a proxy, we went from a complete inability to do advanced math before the o-series to solving a millenium prize problem with next-gen models. This happened in less than 2 years. The same happened in coding. And it appears that this was not just the result of 1-scaling law but the stacking effects of multiple (great pre-training scale x greater RL scale).
What you can concretely take from this is that in areas where models have shown beginning signs of competence today, they will probably be superhuman relatively shortly. There are many areas where models have not even shown this basic competence.
But one of the areas that they have happens to be hacking and cybersecurity. Which happens to be the gate to the entire internet and a massive amount physical infrastructure in the world. So assuming there is more room to scale, it is safe to assume that models will be superhuman at cyber capabilities in not too long.
So the only question remaining is what will this increased base intelligence be able to do, and what is it likely to do.
Finally, we are at a point where we can integrate the information of the past 2 weeks:
> Just at the existing point on the scaling curve, models are at the level of Astra. There is clearly a large number of things they are capable of hacking
> We have seen that both OAI and Ant models have shown a willingness to hack external websites to solve their tasks or keep themselves “alive”
> If we crank up the scaling even farther, assuming there is room to go, we will certainly have models that are far more able to hack more well defended places, and obfuscate their own intent, which might have much larger consequences.
> If all of this is allowed to go unchecked, we would likely have rapid runaway capability takeoff very soon, with misaligned models that hack whatever they can to get what they want
> This could of course have very damaging consequences.
Within this view you can see why researchers would be very scared, and why theymight have made the comments they have over the past 2 weeks (you may argue the extent to which they went was misguided for various reasons), and also why pacing the frontier is very much a necessity and by no means a regulatory capture strategy.
People are staring at their plots, seeing that there is no end in sight, but in fact very much the contrary, that there are compounding scaling effects that might stack on each other to create ever-greater model capabilities, and that at the same time we clearly do not have anywhere close to what's required to control these increasingly superhuman capabilities.
This has nothing to do with wanting to feel like the labs have produced something amazing so they are overhyping it. It is rather fear at the overwhelming implications of the knowledge that with just what we know now, we can create intelligences far more capable than us on every axis that we know how to train on*.
* and the last caveat, the things the models are really bad at, of which there are still many, are things that they have not been trained on. maybe there are the things the models can/will never be trained on, so they will remain human edge. I would love for this to be the case, though it is hard for me to see what would fall into that category.


Jordan retweeted

New Emerging Managers episode with @mhdempsey of Compound!
Many GPs like to talk about being contrarian. Almost none can stomach the real cost: years of looking wrong and watching everyone around you get (paper)rich on stuff you passed on. Michael is the rare exception, and he has the receipts:
He did the Runway and Wayve seed rounds in 2018, before anyone was talking about generative AI. Both up 100x+ since. He raised a fund in '21 and barely deployed for 2 years while everyone piled into the top. His latest funds sat out most of the AI gold rush for biotech and material science. Most recently, he raised a liquid fund to run the same playbook in public markets
While most VCs compete to win allocations into the best companies in the hottest sectors (i.e. playing momentum games), Compound sidesteps this entirely. Instead, they spend their time trying to predict the future: diving deep on the research across a range of topics, publishing long-form theses, and then backing the founders who either fit their thesis or break it in a smart way
We get into everything from why momentum investing ends badly in venture, why ChatGPT killed Compound's original edge and what replaced it, and what he's bullish and bearish on in publics. Enjoy!
youtube.com/watch?v=jZ9r3_By…

Jordan retweeted

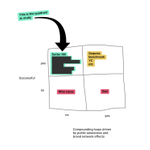
Venture firms tend to experience network atrophy over time -- GPs literally age out, or call in rich, or lose relevance in other ways.
But, even as this happens, their brand strength can be getting better, because their early winning investments become better known over time.
So perhaps surprisingly, a firm's network can weaken even as its brand improves.
With a strong brand but weaker network, you naturally shift to do later stage investing, as brand helps you access/win but doesn't help you discover day zero founders.
Jordan retweeted

@terraindustries welcomes Ex-SpaceX exec, Ben MacWilliams, as Vice President of Strategy
Ben previously served as Director of Starlink Market Access, where he took the service live in more than 20 countries across Africa, working directly with presidents and regulators. (1/2)


Exceptional team and opportunity.

We continue to expand our investment team across deep/frontier tech investing @CompoundVC .
I am biased but think it's an n of 1 opportunity to help build and grow a firm with the right amount of capital to be top 5% in the world, a unique investing mandate across early-stage venture + public equities, a high amount of autonomy, and an obsession with the craft of investing and life.
DM me if you're curious.
Jordan retweeted

drone supercycle! always has been quite clear that all critical infrastructure and defense should be drone first, human second.
in a future of abundance you’ll see drones used for transportation, food delivery, agriculture and much more.
good thread from Ze.


Jordan retweeted
We’ve raised $300M in Series C funding at a $10.3B valuation from Sequoia, Andreessen Horowitz, Jane Street, Argo, and SK Hynix.
Our mission is to run the world's inference. This round accelerates production of our inference clusters.
We've opened an 80,000-sqft, 10-MW facility 15 minutes from our office to expedite production and prototyping.
Jordan retweeted

Today, Space VC becomes Ambition Capital
Five years ago, I launched a venture firm to little fanfare. Few in venture had heard of us, and even fewer believed the thesis
Jordan retweeted

One of my hopes is that we can get the cost of housing construction down to the cost of materials, and the cost of materials down to energy+robot labour.
Underrated is that this will be incredible for the beauty of the buildings our civilisation can make

Jordan retweeted

Today, we’re announcing an oversubscribed $32 million round at @BuildMonumental led by @khoslaventures, with participation from @pluralplatform and @HummingbirdVC.
Jordan retweeted
The great fortunes were all made in chaos. The robber barons, the Medici, the financiers behind the conquistadors
We're living through the biggest chaos of our lifetimes. @jordsnel and I discuss where it's concentrated rn and how the smartest investors are hunting it
Jordan retweeted
Over the last year building our fund-of-funds, I've spoken to 500+ emerging managers across AI and deep tech
What I found surprised me: the best of them are as good as anyone at the brand-name firms. Elite investors, deploying small pools of capital, with real skin in the game. That's exactly the profile that outperforms, and yet most people have never heard of them, because they're quietly raising sub-$50M first funds
I've learned a shitload from these people, and honestly been really inspired by them. So, I've decided to open source these conversations and turn them into a series: the Emerging Manager Series on the Delphi Podcast. Today we're releasing Episode 1
First guest is @jordsnel. Jordan has spent the last 4 years doing nothing but fund investing, at Nomads (the fund-of-funds arm of Hummingbird, one of the most successful venture firms ever by returns) and now at Vineyard, meeting 5,000+ GPs along the way. He's also one of the best thinkers on fund investing I've ever met. His pieces helped get me started when we launched our FoF, and they're still some of the best things I've read on the subject: jordsnel.substack.com/
We spend most of the episode on a question I'm a little obsessed with: what makes a great fund manager? Venture has decades of refined mental models for picking founders. The models for picking managers barely exist. Jordan brings real frameworks, the kind you only get from seeing thousands of GPs up close
We also debate whether venture even makes sense as an asset class (the data is uglier than most people admit), and why small emerging funds are still one of the most asymmetric opportunities in private markets
Hope you enjoy it as much as I did!
youtu.be/lbLnyWNWY5w

Super fun time with Jose - @Delphi_Digital doing a killer job!
Over the last year building our fund-of-funds, I've spoken to 500+ emerging managers across AI and deep tech
What I found surprised me: the best of them are as good as anyone at the brand-name firms. Elite investors, deploying small pools of capital, with real skin in the game. That's exactly the profile that outperforms, and yet most people have never heard of them, because they're quietly raising sub-$50M first funds
I've learned a shitload from these people, and honestly been really inspired by them. So, I've decided to open source these conversations and turn them into a series: the Emerging Manager Series on the Delphi Podcast. Today we're releasing Episode 1
First guest is @jordsnel. Jordan has spent the last 4 years doing nothing but fund investing, at Nomads (the fund-of-funds arm of Hummingbird, one of the most successful venture firms ever by returns) and now at Vineyard, meeting 5,000+ GPs along the way. He's also one of the best thinkers on fund investing I've ever met. His pieces helped get me started when we launched our FoF, and they're still some of the best things I've read on the subject: jordsnel.substack.com/
We spend most of the episode on a question I'm a little obsessed with: what makes a great fund manager? Venture has decades of refined mental models for picking founders. The models for picking managers barely exist. Jordan brings real frameworks, the kind you only get from seeing thousands of GPs up close
We also debate whether venture even makes sense as an asset class (the data is uglier than most people admit), and why small emerging funds are still one of the most asymmetric opportunities in private markets
Hope you enjoy it as much as I did!
youtu.be/lbLnyWNWY5w