




Jon Perl retweeted

A lot of what we do at QA Wolf is designing agentic systems to do what humans do naturally. Humans are great at sorting test failures by a root cause, but slow. Agents are fast but need explicit rules to work together. Check it out: qawolf.com/blog/how-qa-wolf-…

Jon Perl retweeted

AI investigation is now live for everyone.
The moment a test fails, an agent jumps in. Broken tests are updated, bugs are filed, flakes are re-run.
QA cycles run 6.5x faster because you're not waiting for the whole suite before triaging failures.
qawolf.com/changelog/ai-inve…

tried to resolve a customer support ticket assigned to me but the ai held me accountable to a proper solution 😅

Jon Perl retweeted

how it feels to interact with my human family after another 14 hour day of interacting with Claude

Jon Perl retweeted
'twas no small feat building the infrastructure for Windows testing — check it out 👇


not just tests, even our ai chats get a computer. here is why:

A new model launches every other week. GPT-6.1 Sol, Gemini 4 Argon, Claude Opus 5.5, each new release beating the last on some benchmark. But on its own, even the smartest model can only tell you how to fix a broken test. To actually fix it, it needs somewhere to work: your code, a browser to open your app, and a way to run the test and see it pass, that’s the sandbox.
QA Wolf AI’s is warm in milliseconds, with a real file system, a git clone of your test suite and a live browser you can watch. When the task is big, it spins up 50 more sandboxes, each with its own browser and branch.
Here’s how we built it: qawolf.com/blog/every-ai-age…

Jon Perl retweeted
A new model launches every other week. GPT-6.1 Sol, Gemini 4 Argon, Claude Opus 5.5, each new release beating the last on some benchmark. But on its own, even the smartest model can only tell you how to fix a broken test. To actually fix it, it needs somewhere to work: your code, a browser to open your app, and a way to run the test and see it pass, that’s the sandbox.
QA Wolf AI’s is warm in milliseconds, with a real file system, a git clone of your test suite and a live browser you can watch. When the task is big, it spins up 50 more sandboxes, each with its own browser and branch.
Here’s how we built it: qawolf.com/blog/every-ai-age…
Jon Perl retweeted
Welcome to self-driving QA 🚗
Your agent builds a feature
⬇️
Calls QA Wolf to test it
⬇️
QA Wolf bulk automates Playwright & Appium tests
⬇️
Tests run in parallel
⬇️
Verified bugs are shared with your agent
⬇️
Agent fixes
⬇️
Re-test & ship
Start here: docs.qawolf.com/

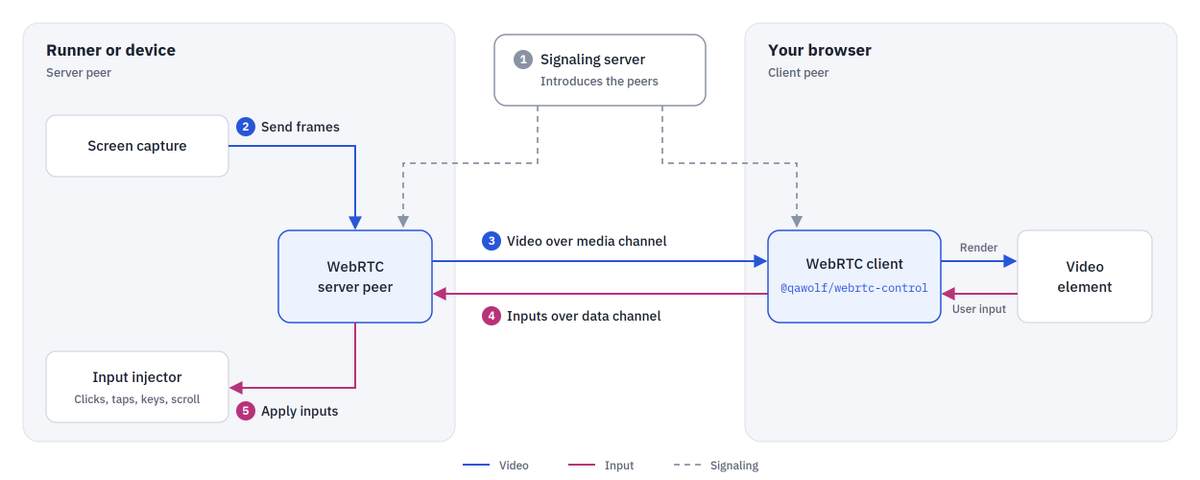
web and real phones streamed to the browser. you don't need to watch the tests live. but if you want to you can. it's little things like this that make a product experience magical
Now! Watch test runs live and in living color.
When test runs get stuck they hold up your release. Before today, if you wanted to know why a test was hanging, you had to wait for the recording and logs.
Now you (or our agent) can jump in and intervene.
qawolf.com/changelog/live-st…